Key Microbiome & Genomics Solutions
Optimized platforms designed to address challenging sample profiles and deliver precise taxonomic resolutions.
Understanding the 16S rRNA Hypervariable Regions
The 16S ribosomal RNA (rRNA) gene has long served as the gold standard for bacterial taxonomic classification and phylogenetic analysis. Approximately 1,500 base pairs (bp) in length, the gene contains nine hypervariable regions (V1–V9) interspersed among highly conserved regions. While the conserved regions serve as universal binding sites for PCR primers, the hypervariable regions contain sequence signatures unique to specific bacterial taxa.
V1–V3 Region
Excellent for identifying complex skin microbiome components and resolving Actinobacteria species.
V3–V4 Region
The most widely adopted region for gut microbiota studies, offering balanced coverage and databases compatibility.
V1–V9 Full-Length
Utilizes long-read sequencing (PacBio/Nanopore) to capture the entire gene, enabling species- and strain-level resolution.
In environmental, clinical, and industrial metagenomics, choosing the appropriate hypervariable region is critical. Short-read platforms (like Illumina NovaSeq) typically target specific sub-regions (e.g., V3-V4 or V4), balancing sequencing depth with cost-efficiency. However, when addressing low-input samples, the selection of the target region must be meticulously balanced with primer binding efficiency, amplification bias, and database representation.
The Challenge of Low-Input Samples in Microbiome Profiling
Low-input, or low-biomass samples present a unique set of challenges in molecular biology. These samples include clinical biopsies, cerebrospinal fluid (CSF), skin swabs, deep-sea cores, cleanroom surfaces, and forensic residues. The primary hurdles when dealing with trace DNA levels include:
- Contamination Susceptibility ("The Kitome"): When target DNA is extremely low, background DNA originating from extraction reagents, laboratory environments, and plasticware can dominate the sequencing output.
- PCR Bias and Chimera Formation: To obtain sufficient library concentration for sequencing, low-input samples require additional PCR cycles. This exponentially increases the risk of generating chimeric sequences and amplifying minor contamination.
- Sample Loss During Extraction: Standard purification protocols can lead to significant loss of trace nucleic acids, resulting in a skewed representation of the microbial community or complete library failure.
Industrial Solution Framing: Overcoming the Low-Biomass Bottleneck
To successfully analyze low-input samples, researchers must adopt a holistic workflow that integrates ultra-clean sample preparation, optimized primer design, high-fidelity polymerases, and advanced bioinformatics filters. By selecting the optimal 16S hypervariable region and combining it with automated library preparation, we minimize contamination and maximize taxonomic recovery.
Deep Scenario Analysis: Where Low-Input 16S Sequencing Matters
1. Clinical Diagnostics & Non-Invasive Biomarker Discovery
In modern medicine, the microbiome is recognized as a key player in systemic health. However, many clinical samples are inherently low-biomass. For instance, blood microbiome profiling, lung bronchoalveolar lavage fluid (BALF), and tumor tissue biopsies contain very few bacterial cells compared to host human cells. By optimizing 16S hypervariable region amplification (often V4 or V1-V3) with specialized host DNA depletion protocols, researchers can identify low-abundance pathogens or diagnostic biomarkers without the cost of deep metagenomic shotgun sequencing.
2. Environmental and Extreme Microbiome Exploration
Astrobiology, deep sub-surface geology, and glacial ice core research rely heavily on extracting biological signals from environments with virtually no nutrients. In these scenarios, DNA yields are often sub-nanogram. Framing a robust 16S amplicon solution involves using customized primers that target conserved regions of ancient or extremophilic bacteria while suppressing the amplification of modern contaminants.
3. Pharmaceutical and Probiotic Quality Control
Industrial fermentation and cleanroom monitoring require rapid, high-throughput verification of microbial purity. In cleanrooms where sterile conditions are mandatory, any microbial presence is a critical event. Low-input 16S sequencing allows facility managers to identify trace contaminants on surfaces or in air samples, ensuring compliance with strict regulatory standards (e.g., FDA, GMP).
Commercial Landscape and Future Technological Trends
The global microbiome sequencing market is experiencing rapid expansion, driven by the rise of personalized medicine, agricultural biologicals, and environmental monitoring. The commercial demand is transitioning from simple "who is there" profiling to absolute quantification and high-resolution strain tracking.
Key trends shaping the future of this industry include:
- The Rise of Long-Read Amplicon Sequencing: While short-read V3-V4 profiling remains cost-effective, PacBio and Oxford Nanopore full-length (V1-V9) sequencing are gaining market share. Full-length sequencing eliminates the need to choose a single hypervariable region, resolving species-level taxonomy that was previously indistinguishable.
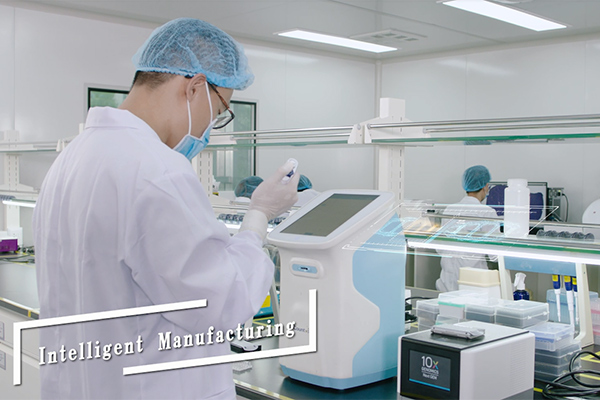
- Automation and High-Throughput Pipelines: To reduce human error and kit-derived contamination, commercial providers are adopting fully automated liquid handling systems (such as the Brilliant Lab 1000) to execute library preparation in ultra-clean environments.
- AI-Driven Taxonomic Classification: Machine learning algorithms are replacing traditional naive Bayesian classifiers. These AI models leverage structural modeling of the 16S rRNA molecule alongside sequence data to predict taxonomic placement even when sequencing quality is compromised by low input.
Biomarker Technologies (BMKGene)
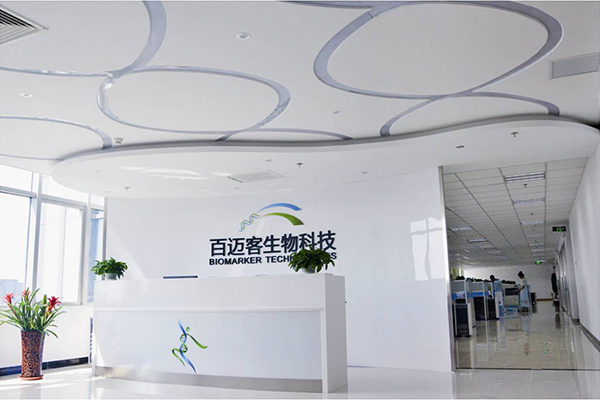
Biomarker Technologies (BMKGene), founded in 2009, is a leading genomics service provider with over 16 years of continuous innovation in high-throughput sequencing and bioinformatics. Backed by more than 60 national invention patents and 200+ software copyrights, we deliver comprehensive multi-omics solutions—spanning genomics, metagenomics, epigenetics, single-cell omics, transcriptomics, and our proprietary BMKMANU S3000 spatial transcriptome technology—supported by our advanced BMKCloud bioinformatics platform. We have established long-term collaborations with organizations across 84 regions worldwide, providing reliable genomic solutions on a scale that meets both academic and industrial needs.
Our Advanced Platforms & Infrastructure
Equipped with cutting-edge sequencing systems and automated molecular biology laboratories to process complex samples.

Multi-level Sequencing Platforms
PacBio platforms: Sequel II, Sequel, RSII
Nanopore platforms: PromethION P48, GridION X5, MinION
10X Genomics: 10X ChromiumX, 10X Chromium Controller
Illumina platforms: NovaSeq
BGI platforms: DNBSEQ-G400, DNBSEQ-T7
Others: Bionano Irys, Waters QTOF, QTRAP 6500+

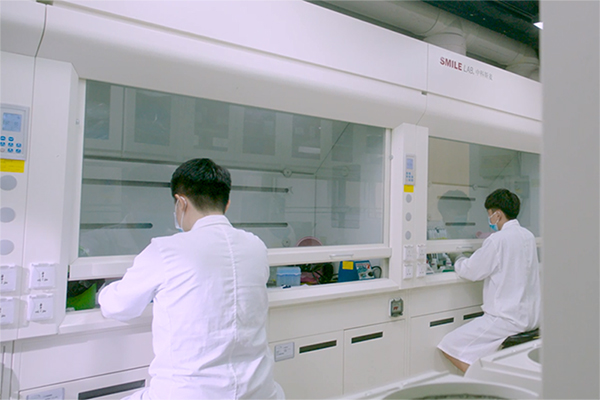
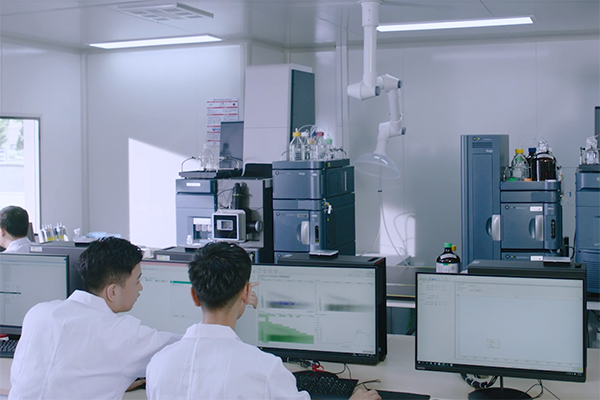
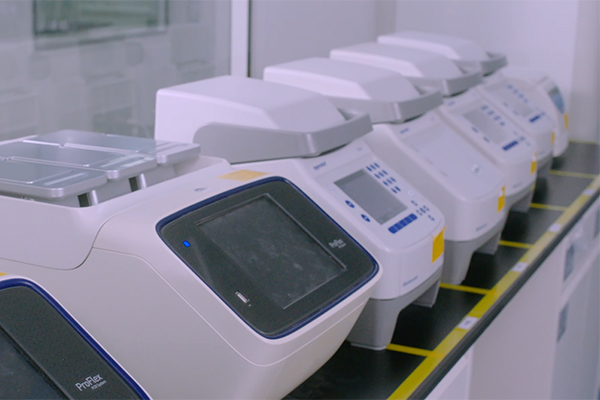
20,000+ Sq. Ft. Molecular Lab
Advanced biomolecular laboratory instrumentation.
Standardized workflows for sample extraction, library construction, clean rooms, and sequencing.
All laboratory procedures executed under strict Standard Operating Procedures (SOPs).

BMKCloud Bioinformatic Platform
Self-developed, high-performance cloud platform.
4,260 computing cores with peak computing power over 121,708.8 Gflop/s.
CPUs with 41,104 memory and 3 PB total storage capacity for rapid analysis.
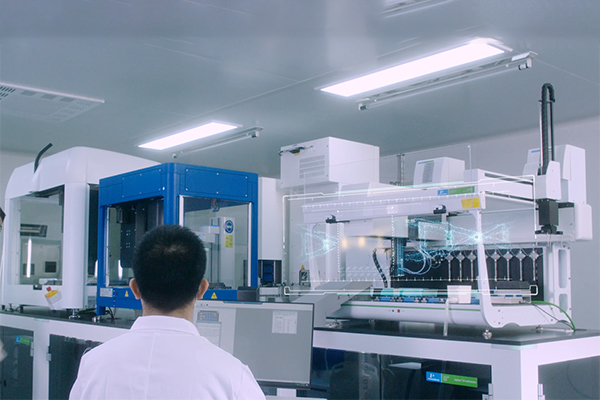
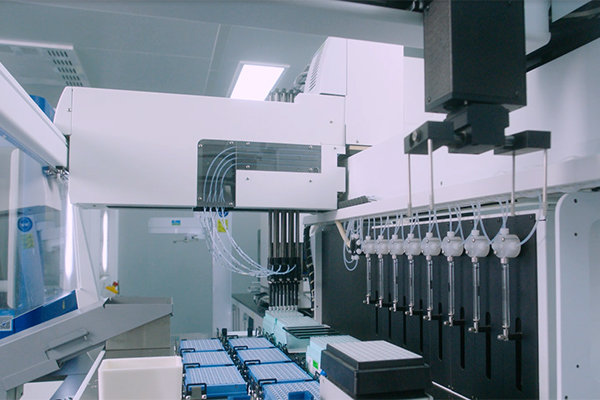
Fully Automated Platform for NGS: Brilliant Lab 1000
Biomarker Technologies (BMKGENE) and PerkinElmer have jointly built a fully automated experimental production line, called Brilliant Lab 1000 (BL1000), which is applied to high-throughput NGS library construction services.
By integrating automation, BMKGENE strives to greatly improve the entire line of sequencing products in terms of product types, production line throughput, delivery quality, and cycle time, providing customers with reliable, error-free, and scale-ready sequencing services.
Enterprise Qualifications & Certifications
Demonstrating our commitment to quality, compliance, and scientific rigor across all genomic operations.


ISO Certifications, Patents & Software Copyrights


Ready to Frame Your Low-Input Sequencing Solution?
For inquiries about our products, workflows, or custom pricelists, please connect with our genomics experts. We will be in touch within 24 hours.
Inquiry NowBrowse All Genomic & Sequencing Services
Explore our complete portfolio covering de novo sequencing, transcriptomics, epigenetics, and cloud analysis tools.