
Featured Amplicon & Sequencing Solutions
Amplicon (16S/18S/ITS)
Comprehensive profiling of microbial communities targeting key hypervariable regions.

Non-Reference based mRNA Sequencing-NGS
De novo transcriptomics to profile gene expression without a reference genome.

Whole Genome Bisulfite Sequencing (WGBS)
Single-base resolution DNA methylation mapping for comprehensive epigenomics.
Prokaryotic RNA Sequencing
In-depth exploration of bacterial and archaeal transcriptomes for functional analysis.
1. Introduction to the 16S Hypervariable Region
The 16S ribosomal RNA (rRNA) gene has long served as the gold standard for phylogenetic classification and taxonomic profiling of prokaryotic communities. Spanning approximately 1,500 base pairs, this gene contains nine hypervariable regions (V1 to V9) interspersed among highly conserved sequences. The conserved regions provide universal primer binding sites, allowing researchers to amplify the intervening hypervariable regions across diverse bacterial and archaeal taxa. The sequence variation within the V1–V9 regions offers unique molecular signatures that differentiate distinct microbial taxa, making it a cornerstone for microbiome research.
Strategic selection of specific hypervariable regions (such as V3–V4 or V4) is crucial, as primer bias and sequence length can significantly affect taxonomic resolution and community composition estimates across different ecosystems.
In modern genomics, selecting the appropriate hypervariable region depends heavily on the target environment (e.g., human gut, marine water, soil, or extreme industrial environments) and the sequencing platform used. For instance, the V4 region is widely adopted due to its low primer bias and high compatibility with short-read sequencing platforms like Illumina, while V3–V4 constructs are favored for providing broader taxonomic coverage. With the advent of long-read sequencing technologies such as PacBio and Oxford Nanopore, researchers can now sequence the full-length 16S rRNA gene, eliminating the need to choose a single hypervariable region and delivering species-level or even strain-level resolution.
2. The Industrial and Commercial Landscape of Multi-Omics
The global biotechnology and pharmaceutical sectors are experiencing a paradigm shift from single-omic analyses to integrated multi-omic workflows. While 16S rRNA profiling answers the fundamental question of "who is there" within a microbial ecosystem, it falls short of explaining "what they are doing" and "how they interact with their host or environment." To bridge this knowledge gap, commercial enterprises and academic institutions are combining 16S amplicon sequencing with metagenomics, metatranscriptomics, metaproteomics, and metabolomics. This holistic approach provides a comprehensive view of microbial taxonomy, functional capacity, active transcription, and metabolic output.
In the pharmaceutical industry, multi-omic pipelines are accelerating the development of microbiome-based therapeutics. Companies targeting inflammatory bowel disease (IBD), metabolic syndrome, and cancer immunotherapy responsiveness leverage 16S profiling to identify dysbiosis patterns, metatranscriptomics to assess active bacterial pathways, and metabolomics to quantify short-chain fatty acids (SCFAs) and other bioactive compounds. In agriculture, commercial biostimulant developers utilize multi-omics to design synthetic microbial consortia that enhance crop yields, improve nutrient uptake, and build resistance against environmental stressors. The integration of these diverse datasets requires robust bioinformatics platforms, driving the demand for specialized cloud computing services and AI-driven analytical tools.
Genomics & Metagenomics
Uncovering taxonomic diversity through hypervariable regions and decoding the full metabolic potential of complex environmental samples.
Metatranscriptomics
Analyzing active gene expression profiles to determine how microbial communities respond dynamically to host and environmental shifts.
Metabolomics Integration
Correlating taxonomic abundance with chemical profiles to validate the functional outputs of the microbiome under varying conditions.
3. Advanced Application Scenarios of 16S in Multi-Omics
A. Clinical Diagnostics & Personalized Medicine
The human microbiome is deeply intertwined with host physiology, and its disruption is linked to numerous chronic conditions. By incorporating 16S rRNA sequencing into multi-omic clinical trials, researchers can track patient-specific microbial signatures over time. For example, in oncology, the composition of the gut microbiota has been shown to influence the efficacy of immune checkpoint inhibitors. Integrating 16S taxonomic data with host transcriptomics and serum metabolomics allows clinicians to build predictive models for patient response, paving the way for personalized adjuvant therapies and dietary interventions.
B. Agricultural Biotechnology & Soil Health
Sustainable agriculture relies heavily on the complex interactions within the rhizosphere. 16S hypervariable region profiling of soil microbiomes, combined with plant transcriptomics and soil metabolomics, helps decipher the chemical signaling between plant roots and beneficial microbes. This multi-omic perspective enables the development of tailored biofertilizers and biocontrol agents, reducing reliance on chemical pesticides and promoting long-term soil health and carbon sequestration.
C. Industrial Bioprocessing & Waste Management
In industrial bioreactors and anaerobic digesters, microbial consortia carry out complex biochemical transformations. Monitoring the composition of these consortia via 16S sequencing ensures process stability and optimizes yield. When coupled with metatranscriptomics, operators can detect metabolic bottlenecks or stress responses in real-time, allowing for proactive adjustments to temperature, pH, or substrate feed rates. This is particularly valuable in biofuel production, wastewater treatment, and bioremediation of contaminated sites.
4. Future Trends: Full-Length Sequencing and Spatial Resolution
As sequencing technologies continue to mature, the field is moving toward high-throughput, full-length 16S rRNA gene sequencing. Long-read platforms like PacBio Sequel II and Oxford Nanopore PromethION allow researchers to sequence all nine hypervariable regions in a single read. This eliminates the taxonomic ambiguity associated with short-read amplicon sequencing and enables precise identification of closely related species and strains. Additionally, the emerging field of spatial metagenomics aims to map microbial communities within their physical microenvironments, providing spatial context to host-microbe interactions.
About Biomarker Technologies (BMKGene)
Biomarker Technologies (BMKGene), founded in 2009, is a leading genomics service provider with over 16 years of continuous innovation in high-throughput sequencing and bioinformatics. Backed by more than 60 national invention patents and 200+ software copyrights, we deliver comprehensive multi-omics solutions—spanning genomics, metagenomics, epigenetics, single-cell omics, transcriptomics, and our proprietary BMKMANU S3000 spatial transcriptome technology—supported by our advanced BMKCloud bioinformatics platform. We have established long-term collaborations with organizations across 84 regions worldwide, providing reliable genomic solutions on a global scale.
Our Advanced Platforms & Facilities
Leading Sequencing Platforms
PacBio: Sequel II, Sequel, RSII
Nanopore: PromethION P48, GridION X5, MinION
10X Genomics: ChromiumX, Chromium Controller
Illumina: NovaSeq
BGI: DNBSEQ-G400, DNBSEQ-T7
Bionano: Irys system
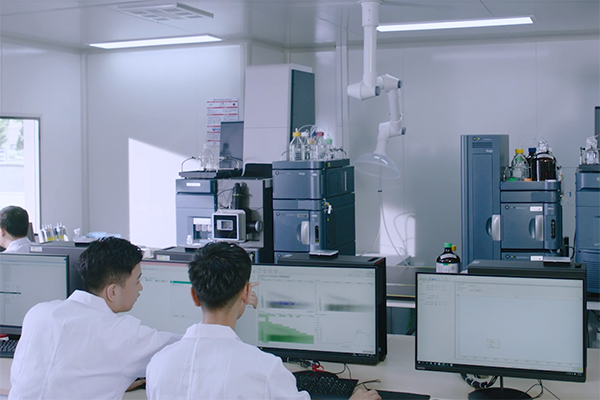
Mass Spec: Waters XEVO G2-XS QTOF, QTRAP 6500+
State-of-the-Art Laboratory
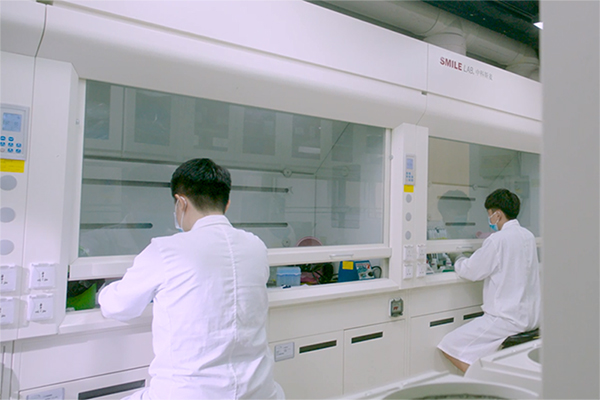
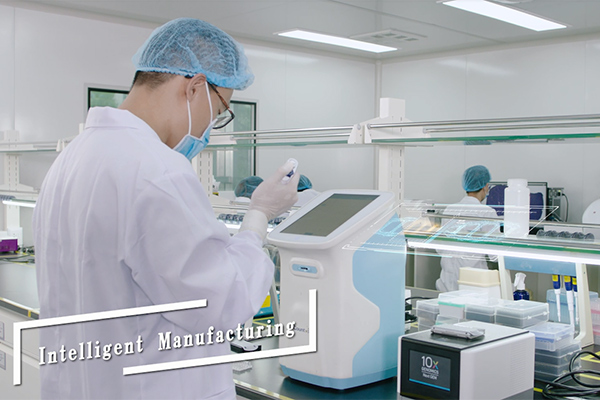
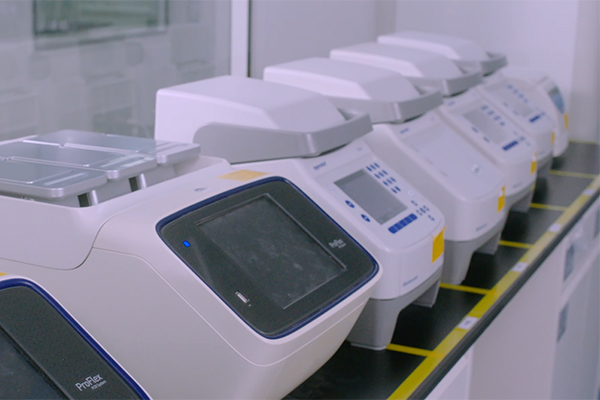
Over 20,000 square feet of space featuring advanced biomolecular laboratory instruments. Standardized laboratories for sample extraction, library construction, clean rooms, and sequencing operate under strict SOPs to ensure high-quality data delivery.
BMKCloud Bioinformatics
Our self-developed bioinformatic analysis platform is powered by 4,260 computing cores, 41,104 memory capacity, and 3 PB of total storage, delivering a peak computing power of over 121,708.8 Gflop per second.


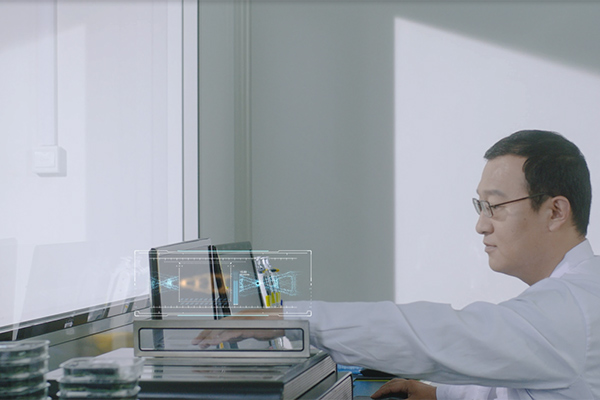
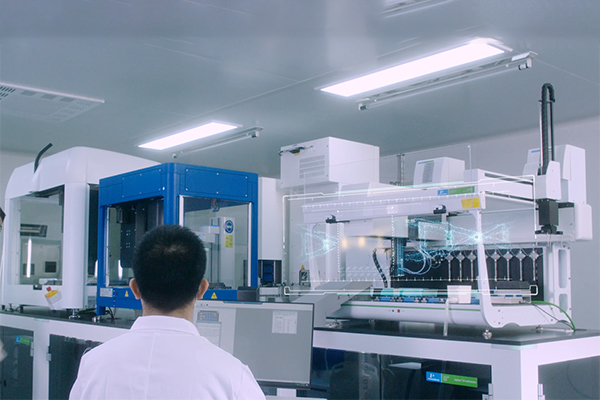
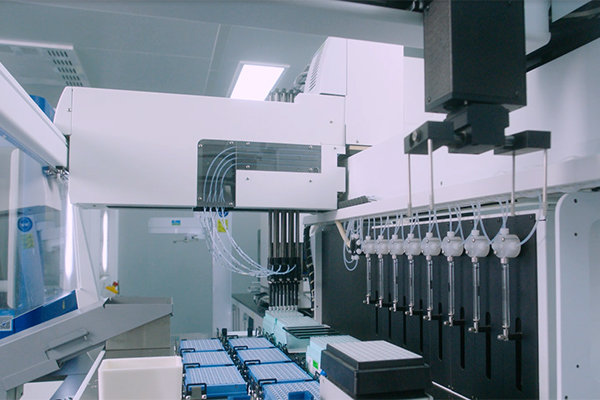
Fully Automated Platform for Next-generation sequencing -- Brilliant Lab 1000
Biomarker Technologies (BMKGENE) and PerkinElmer have jointly built a fully automated experimental production line, called Brilliant Lab 1000 (BL1000), which is applied to the high-throughput NGS library construction service.
BMKGENE strives to greatly improve the entire line of sequencing products in terms of product types, production line throughput, delivery quality, and cycle time, to provide customers with better sequencing services.
Enterprise Qualification & Patents


Our Complete Product Portfolio

Human Whole Exome Sequencing
Deep coverage sequencing of the protein-coding regions of the human genome.

Bulked Segregant Analysis
Rapid identification of genetic markers associated with specific mutant phenotypes.

Illumina Pre-made Libraries
Ready-to-sequence DNA and RNA libraries optimized for Illumina platforms.

T2T Genome Assembly | Ultra Long Sequencing
Telomere-to-telomere complete genome reconstruction using long-read technology.
Whole Genome Bisulfite Sequencing (WGBS)
Single-base resolution DNA methylation mapping for comprehensive epigenomics.
Non-Reference based mRNA Sequencing-NGS
De novo transcriptomics to profile gene expression without a reference genome.
Amplicon (16S/18S/ITS)
Comprehensive profiling of microbial communities targeting key hypervariable regions.
Prokaryotic RNA Sequencing
In-depth exploration of bacterial and archaeal transcriptomes for functional analysis.


