
1. Technical Briefing of Amplicon Sequencing
Amplicon sequencing is a highly targeted Next-Generation Sequencing (NGS) approach that focuses on analyzing specific genomic regions of interest. By utilizing PCR primers designed to flank targeted loci, researchers can amplify and subsequently sequence specific genes, genetic variants, or hypervariable regions. This methodology contrasts with whole-genome sequencing (WGS) by concentrating sequencing depth on defined targets, resulting in significantly higher coverage, sensitivity, and cost-efficiency.
In microbiome research, amplicon sequencing targeting phylogenetic marker genes—such as the 16S rRNA gene for bacteria and archaea, the 18S rRNA gene for eukaryotes, and the Internal Transcribed Spacer (ITS) region for fungi—has become the gold standard. By analyzing the sequence variations within these hypervariable regions, scientists can profile the taxonomic composition, relative abundance, and diversity of complex microbial communities without the need for culturing.
Beyond microbial profiling, custom amplicon panels are widely deployed in human genetics, oncology, and agricultural genomics. These custom panels allow researchers to target hundreds of disease-associated hotspots, single nucleotide polymorphisms (SNPs), or insertions/deletions (indels) simultaneously. The workflow typically involves genomic DNA extraction, target enrichment via multiplex PCR or hybridization capture, adapter ligation, high-throughput sequencing, and bioinformatics profiling.
2. Commercial & Industrial Landscape
The commercial market for amplicon sequencing has experienced exponential growth over the past decade, driven by the declining cost of NGS, the rise of personalized medicine, and an increased appreciation of the human microbiome's role in health and disease. In the clinical sector, targeted amplicon panels are integral to oncology companion diagnostics, non-invasive prenatal testing (NIPT), and infectious disease identification.
Industrially, the demand for standardized, high-throughput, and automated workflows has reshaped the service provider landscape. Leading genomics service providers are shifting from manual library preparation to fully automated, robotic liquid-handling systems. This transition minimizes human error, increases reproducibility, and substantially reduces turnaround times. Furthermore, regulatory compliance, such as ISO certifications and clinical laboratory accreditations, has become a prerequisite for providers catering to pharmaceutical and clinical clients.
On the commercial side, cloud-based bioinformatics platforms have democratized data analysis. Historically, processing massive amplicon datasets required specialized bioinformatics expertise and local high-performance computing clusters. Today, integrated platforms like BMKCloud allow researchers to upload raw sequencing data and receive comprehensive taxonomic assignments, diversity indices, and comparative statistics through user-friendly graphical interfaces, accelerating the transition from data to biological insight.
3. Deep-Dive Application Scenarios
A. Clinical Diagnostics & Oncology
In clinical oncology, amplicon sequencing is utilized to detect low-frequency somatic mutations from liquid biopsies (circulating tumor DNA or ctDNA) and formalin-fixed paraffin-embedded (FFPE) tissue samples. By focusing sequencing power on known oncogenes (e.g., EGFR, KRAS, BRAF), clinicians can identify actionable mutations with detection limits as low as 0.1% variant allele frequency (VAF). This precision enables personalized therapy selection, monitoring of treatment response, and early detection of drug-resistance mutations.
B. Environmental Metagenomics & Agricultural Biotechnology
In agriculture, amplicon sequencing of soil and rhizosphere microbiomes provides crucial insights into plant-microbe interactions, nutrient cycling, and disease suppression. Researchers analyze how different soil treatments, crop rotations, or bio-fertilizers alter the microbial community structure, paving the way for sustainable farming practices. Similarly, in environmental monitoring, amplicon sequencing is used to track water quality, monitor wastewater treatment plants, and assess the impact of pollutants on marine and terrestrial ecosystems.
C. Pharmaceutical Development & Therapeutics
The pharmaceutical industry increasingly leverages amplicon sequencing to evaluate the impact of novel drugs, probiotics, and prebiotics on the human gut microbiome. Clinical trials routinely incorporate gut microbiota profiling to correlate drug efficacy and patient response with specific microbial signatures. Additionally, in the field of live biotherapeutic products (LBPs), amplicon sequencing serves as a critical quality control tool to verify the identity and purity of bacterial strains throughout the manufacturing process.
4. Technological Trends & Future Outlook
The future of amplicon sequencing is defined by two major technological shifts: the transition to long-read sequencing and the integration of artificial intelligence (AI) in bioinformatics.
Traditional short-read sequencing (e.g., Illumina) restricts amplicon analysis to specific hypervariable regions (e.g., V3-V4 of the 16S rRNA gene), which often limits taxonomic resolution to the genus level. Long-read sequencing technologies, such as PacBio HiFi sequencing and Oxford Nanopore Technologies (ONT), enable the sequencing of full-length marker genes (e.g., the entire 1.5 kb 16S rRNA gene or the 2.5 kb ribosomal operon). This full-length sequencing provides species- and strain-level taxonomic resolution, unlocking a deeper understanding of microbial diversity and function.
Concurrently, bioinformatics pipelines are incorporating machine learning models to improve taxonomic classification, predict functional profiles from amplicon data, and distinguish true biological variants from sequencing artifacts. These advancements, combined with automated laboratory setups, will continue to lower barriers to entry and drive novel discoveries across clinical, industrial, and environmental sectors.
About Biomarker Technologies (BMKGene)
Biomarker Technologies (BMKGene), founded in 2009, is a leading genomics service provider with over 16 years of continuous innovation in high-throughput sequencing and bioinformatics. Backed by more than 60 national invention patents and 200+ software copyrights, we deliver comprehensive multi-omics solutions—spanning genomics, metagenomics, epigenetics, single-cell omics, transcriptomics, and our proprietary BMKMANU S3000 spatial transcriptome technology—supported by our advanced BMKCloud bioinformatics platform. We have established long-term collaborations with organizations across 84 regions worldwide, providing reliable genomic solutions on a global scale.
Our Advanced Multi-level Sequencing Platforms

Sequencing Platforms
PacBio platforms: Sequel II, Sequel, RSII
Nanopore platforms: PromethION P48, GridION X5, MinION
10X Genomics: 10X ChromiumX, 10X Chromium Controller
Illumina platforms: NovaSeq
BGI-sequencing platforms: DNBSEQ-G400, DNBSEQ-T7
Bionano Irys system
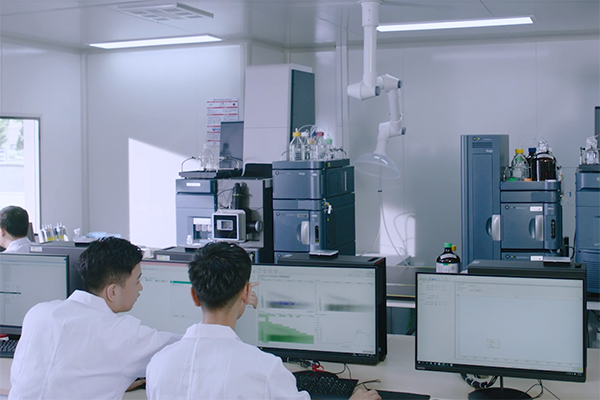
Waters XEVO G2-XS QTOF
QTRAP 6500+

Professional Facilities
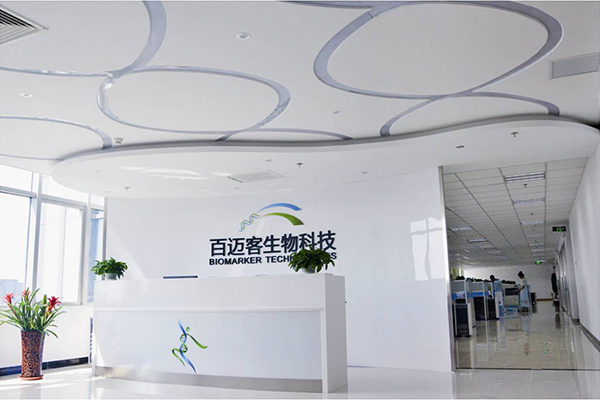
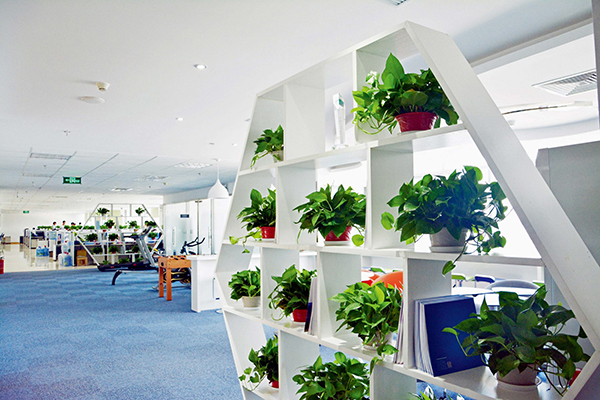
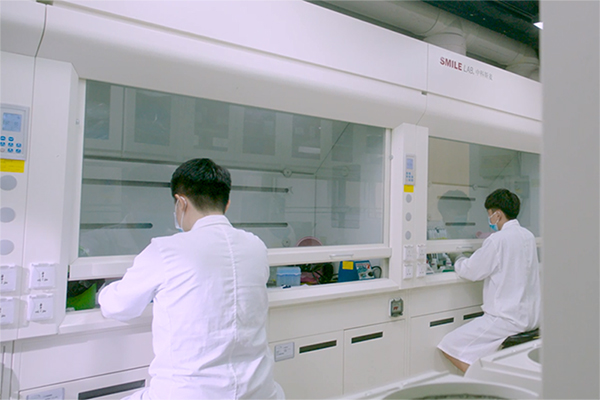
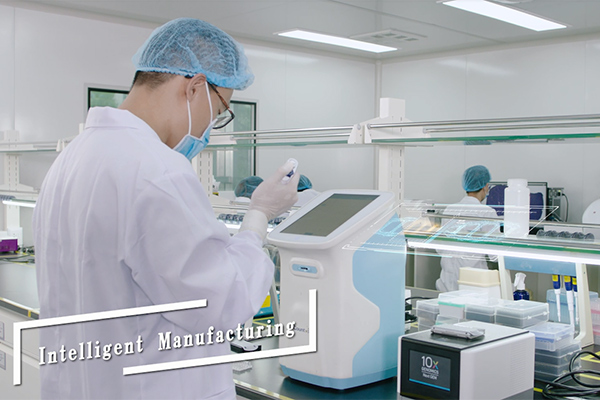
Over 20,000 square feet facility equipped with advanced biomolecular laboratory instruments. Standardized laboratories for sample extraction, library construction, clean rooms, and sequencing labs operating under strict SOPs.

BMKCloud Platform
Self-developed BMKCloud bioinformatics analysis platform featuring CPUs with 41,104 memory, 3 PB total storage, and 4,260 computing cores with peak computing power over 121,708.8 Gflop per second.
Fully Automated Library Construction
Brilliant Lab 1000 (BL1000)
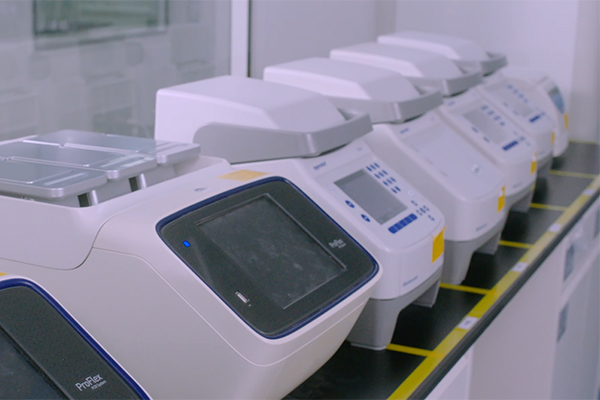
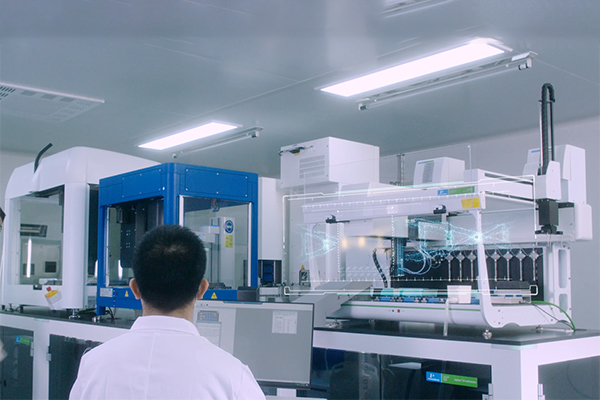
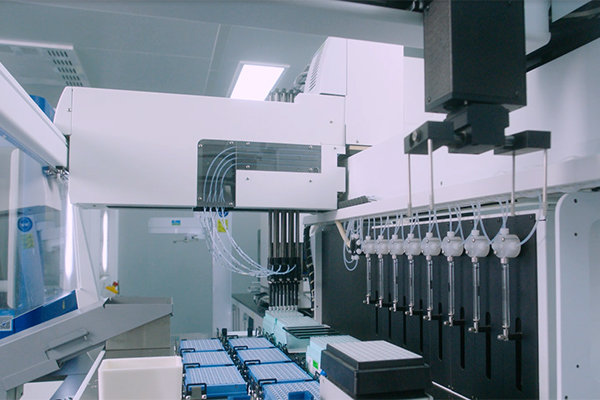
Biomarker Technologies (BMKGENE) and PerkinElmer have jointly built a fully automated experimental production line, called Brilliant Lab 1000 (BL1000), which is applied to the high-throughput NGS library construction service.
BMKGENE strives to greatly improve the entire line of sequencing products in terms of product types, production line throughput, delivery quality, and cycle time, to provide customers with better sequencing services.
State-of-the-Art Production Facility
Enterprise Qualification & Patents
Our commitment to quality and innovation is demonstrated by our extensive list of international certifications, academic partnerships, and proprietary patents.