Featured Amplicon & Sequencing Solutions
Explore our core sequencing methodologies tailored for multi-omic research and development pipelines.


The Critical Role of Amplicon Sequencing in Multi-Omic Frameworks
In modern life sciences, biological systems are rarely governed by a single layer of molecular information. To understand the complex interactions within human health, agricultural systems, and ecological niches, researchers rely on multi-omics. Amplicon sequencing serves as the fundamental taxonomic and targeted genetic cornerstone of this integrated approach. By focusing on specific genomic regions—such as the 16S rRNA gene for bacteria, 18S/ITS regions for fungi, or targeted functional genes—amplicon sequencing provides high-resolution profiling of community structures and targeted genetic variations.
When integrated into multi-omic workflows alongside metatranscriptomics, proteomics, and metabolomics, amplicon sequencing acts as the structural baseline. It answers the question of "who is present" in a biological sample, while other omics layers explain "what they are doing" and "how they are interacting." This holistic view is crucial for developing robust commercial solutions in biotechnology, pharmaceuticals, and environmental engineering.
“Multi-omic solution development demands absolute precision at the foundational genetic level. Amplicon sequencing delivers targeted, cost-effective, and highly scalable data that anchors complex biological datasets.”
Industrial and Commercial Landscapes: Scaling Up Targeted Genomics
The commercial landscape for amplicon sequencing has evolved from academic curiosity to a multi-billion-dollar industrial driver. Key market segments include:
1. Clinical Diagnostics & Microbiome Therapeutics
Pharmaceutical companies leverage amplicon sequencing to profile patient microbiomes during clinical trials. By correlating taxonomic shifts with drug efficacy or side effects (particularly in cancer immunotherapy and inflammatory bowel disease therapies), developers can design targeted microbiome-based therapeutics. Furthermore, rapid amplicon assays are increasingly utilized in clinical diagnostics to detect specific pathogens or drug-resistance genes in human samples.
2. Precision Agriculture & Soil Health Indexing
In agriculture, the transition toward sustainable biologicals requires deep characterization of the soil and plant rhizosphere microbiome. Agribusinesses use high-throughput amplicon sequencing to evaluate the impact of bio-fertilizers, monitor crop disease indicators, and optimize soil health programs. This helps in breeding climate-resilient crops by selecting for beneficial microbial associations.
3. Industrial Biotechnology & Bioremediation
Industrial fermentations, wastewater treatment, and environmental clean-up operations rely on complex microbial consortia. Amplicon sequencing allows operators to monitor these communities in real-time, preventing batch failures and optimizing biological processes for degrading toxic pollutants or producing bio-fuels.
Deep-Dive Application Scenarios of Amplicon-Driven Multi-Omics
To truly appreciate the power of targeted sequencing within multi-omics, we must examine specific, complex application scenarios where these technologies are actively solving industrial bottlenecks.
Scenario A: The Gut-Brain Axis and Neuro-Therapeutics
Developing therapeutics for neurological conditions like Parkinson's disease or depression now routinely involves mapping the gut microbiome. Researchers combine 16S amplicon sequencing with serum metabolomics. The amplicon data identifies specific bacterial taxa that are depleted or enriched in patients. Simultaneously, mass-spectrometry-based metabolomics measures circulating neurotransmitters and short-chain fatty acids (SCFAs). By correlating these datasets, biopharma firms can identify specific bacterial strains that produce neuroactive compounds, paving the way for "psychobiotics."
Scenario B: Marine Environmental DNA (eDNA) Surveillance
Monitoring marine biodiversity for conservation or commercial fishing management traditionally required physical sampling and manual taxonomy. Today, eDNA amplicon sequencing targeting the 12S rRNA or COI (Cytochrome c Oxidase subunit I) genes allows rapid screening of entire marine ecosystems from simple water samples. When combined with environmental metabolomics, this approach reveals not just the presence of commercial fish species or invasive pathogens, but also the physiological stress levels of the ecosystem.
Scenario C: Targeted Variant Screening in Synthetic Biology
In synthetic biology, directed evolution campaigns generate millions of genetic variants of a target enzyme to improve industrial production. Amplicon sequencing is the primary tool used to screen these massive variant libraries. By sequencing the specific target locus across millions of cells, researchers can identify beneficial mutations rapidly. Integrating this with transcriptomic profiling of the host organism ensures that the engineered pathway does not trigger cellular stress responses, optimizing yield and stability.
Leading Multi-level High-throughput Sequencing Platforms
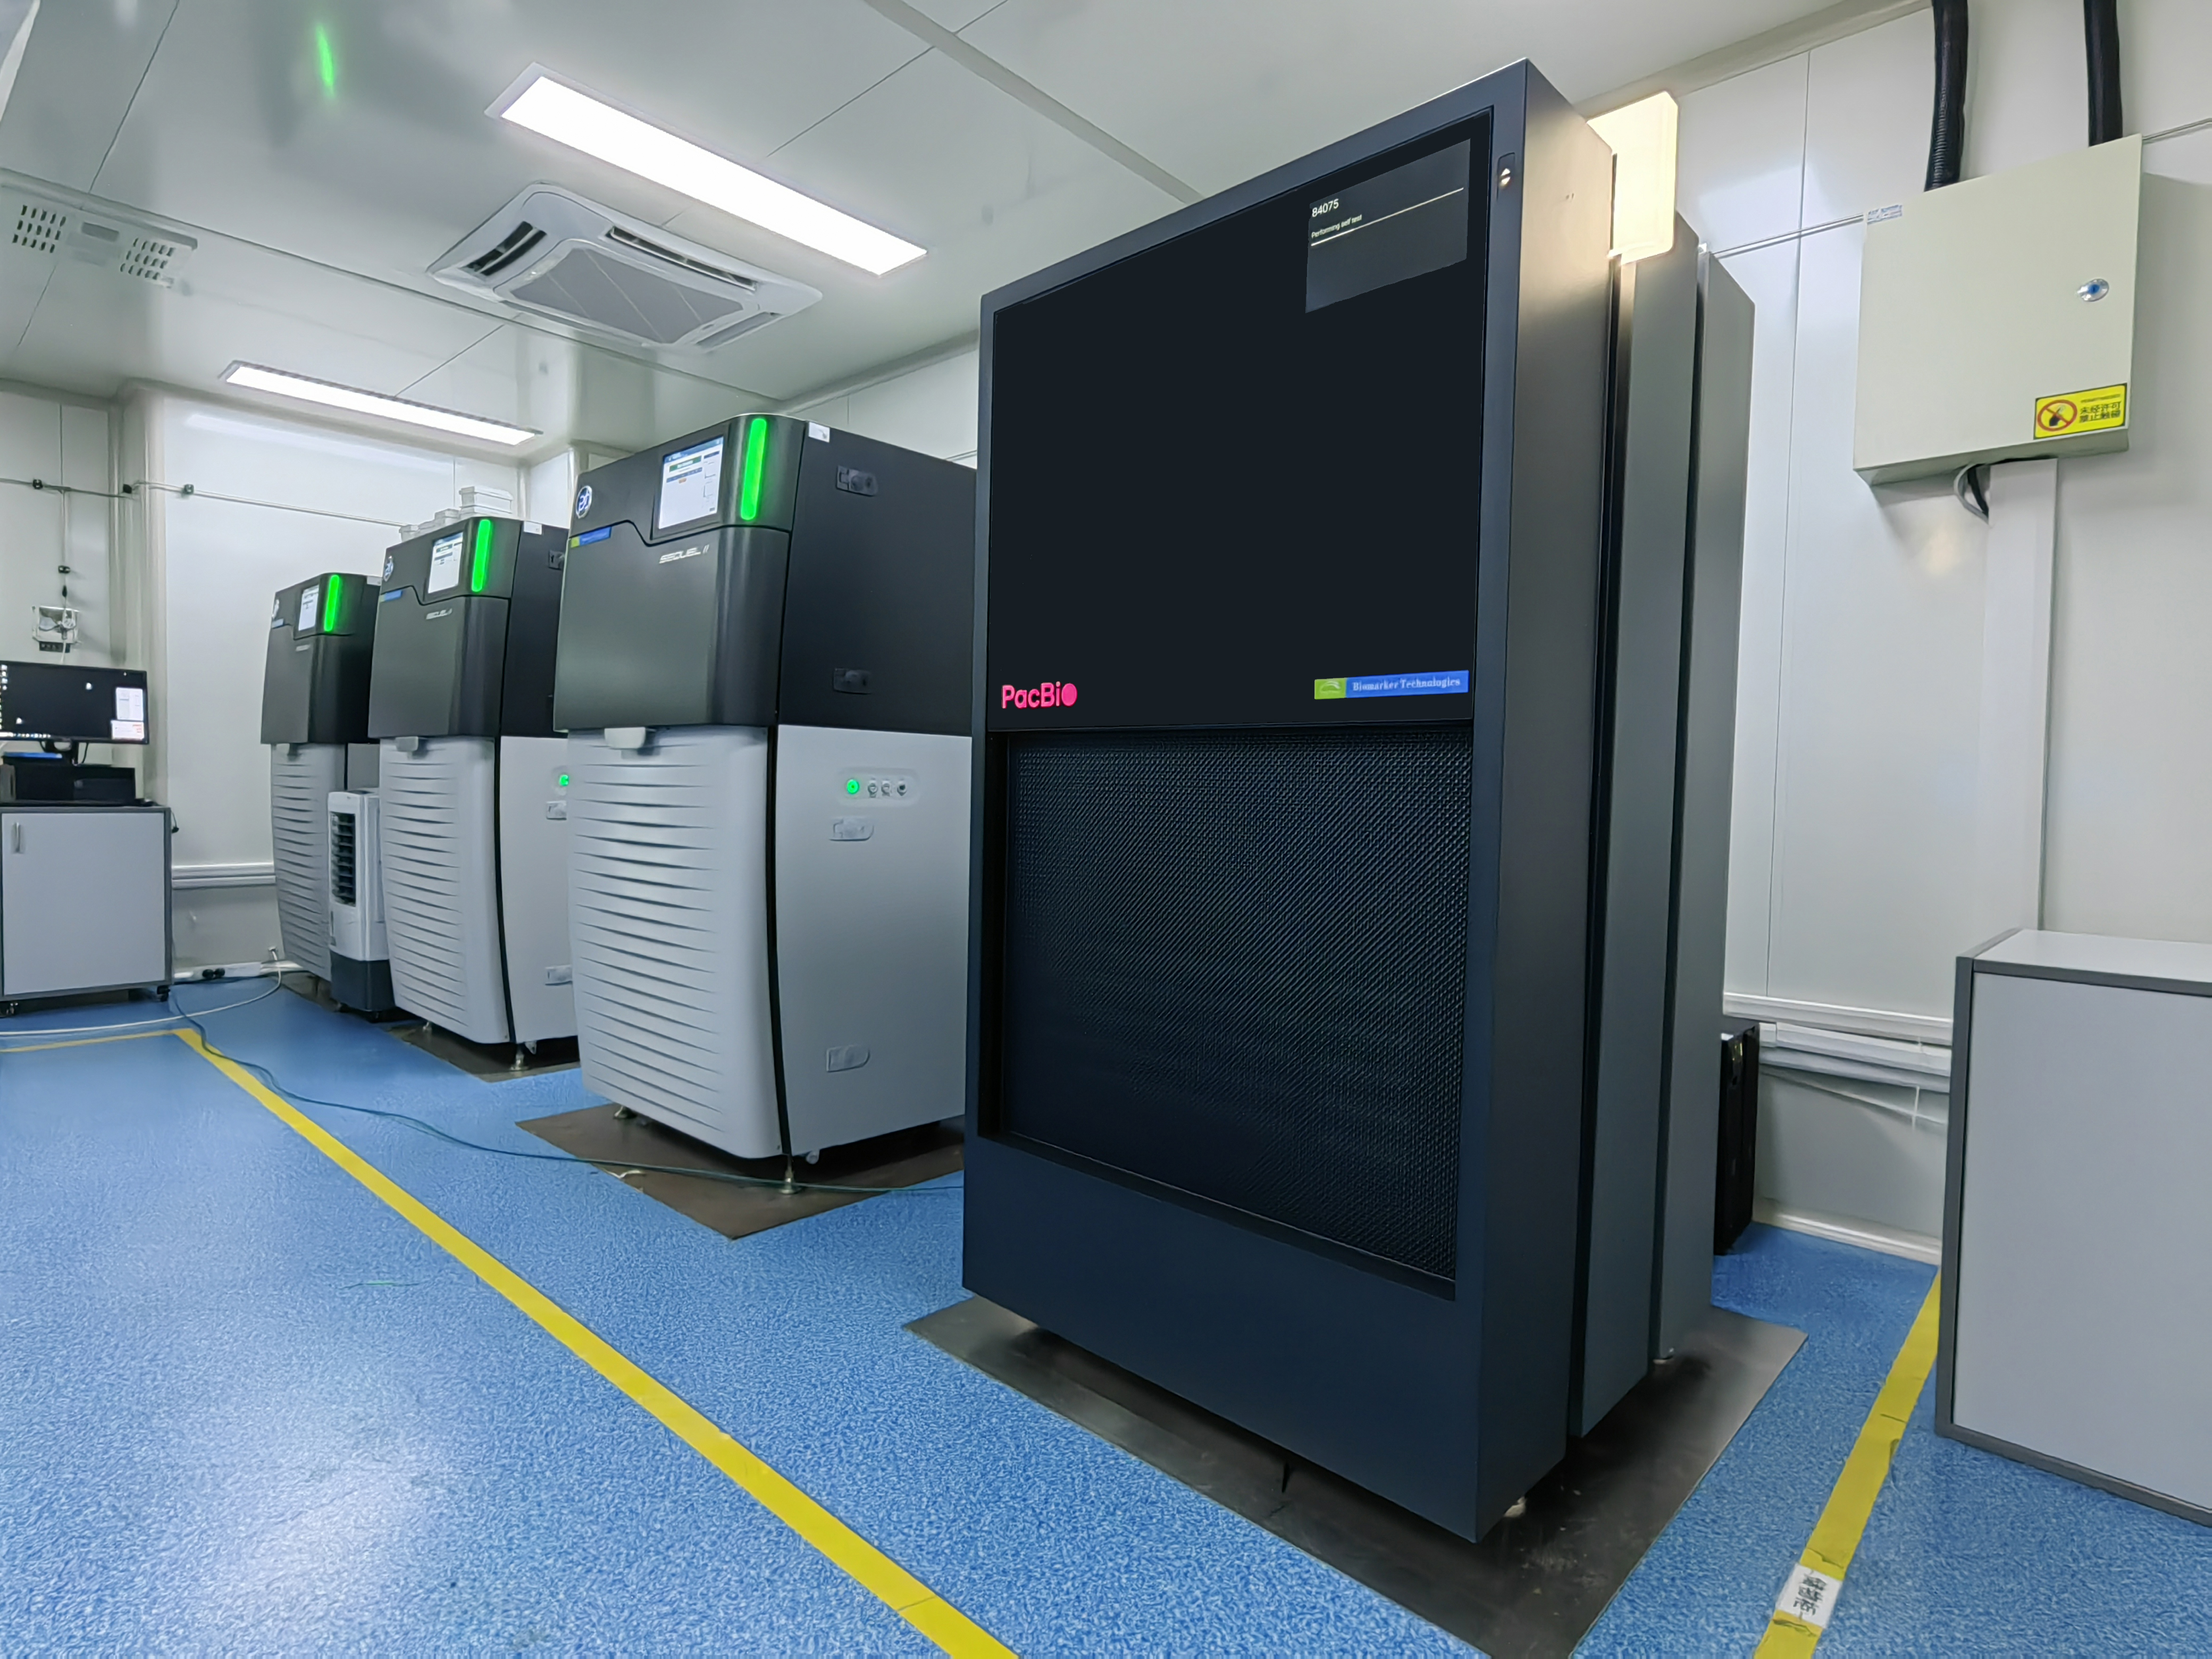
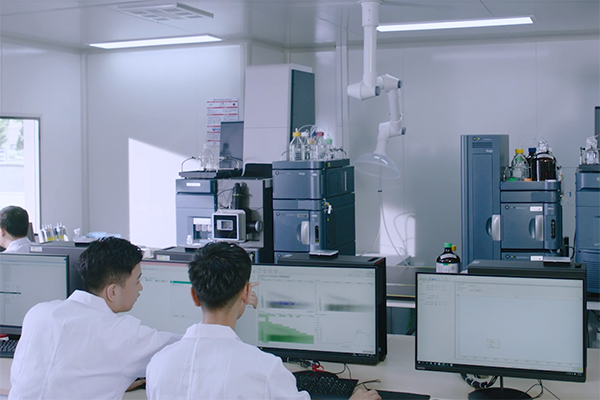
Our robust laboratory infrastructure supports advanced amplicon and multi-omic pipelines globally.
Our Advanced Platforms
- PacBio platforms: Sequel II, Sequel, RSII
- Nanopore platforms: PromethION P48, GridION X5, MinION
- 10X Genomics: 10X ChromiumX, 10X Chromium Controller
- Illumina platforms: NovaSeq
- BGI-sequencing platforms: DNBSEQ-G400, DNBSEQ-T7
- Bionano Irys system
- Waters XEVO G2-XS QTOF
- QTRAP 6500+
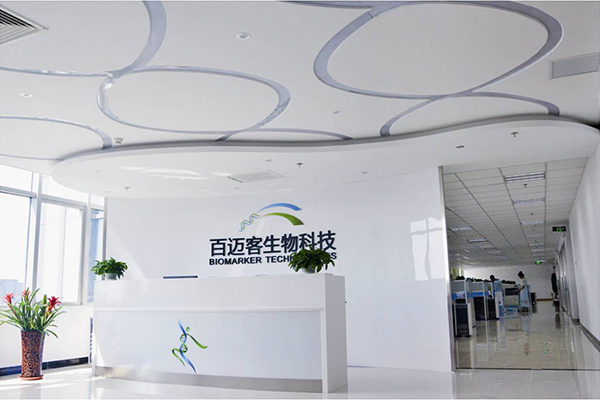
Over 20,000 Square Feet Facility
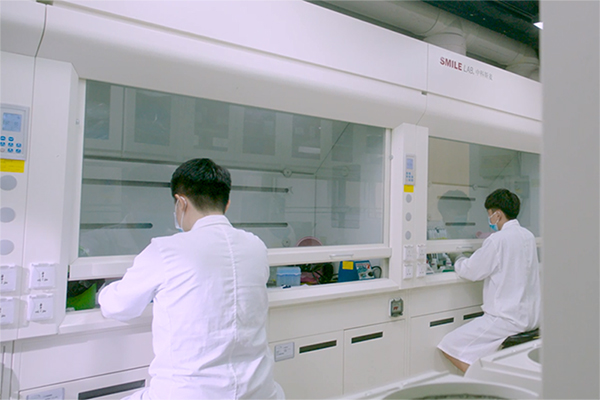
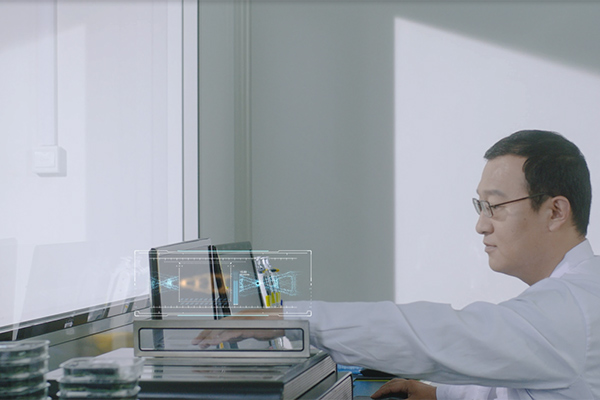
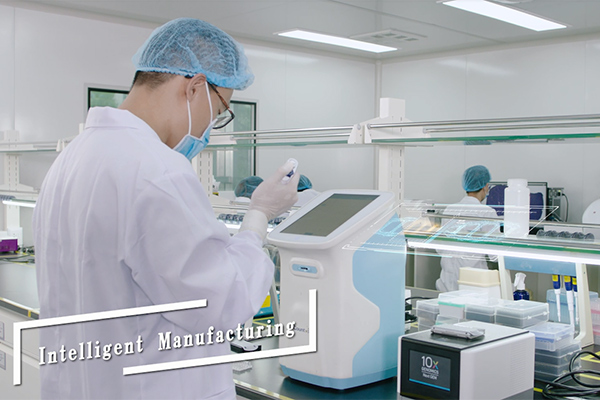
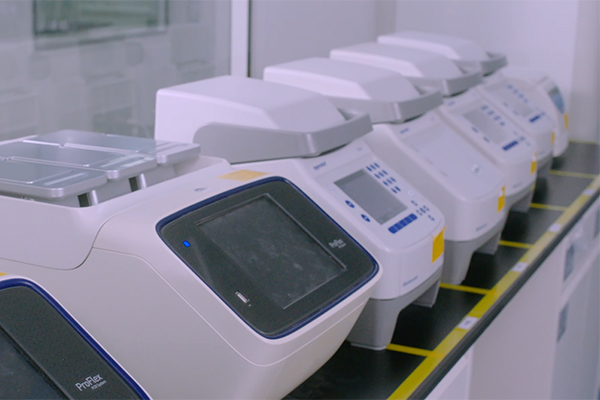
Our professional, automatic molecular laboratory is designed to handle high-throughput demands with maximum accuracy:
- Advanced biomolecular laboratory instruments.
- Standardized laboratories for sample extraction, library construction, clean rooms, and sequencing.
- Standard operating procedures (SOPs) governing every step from sample receipt to final bioinformatic delivery.


Fully Automated NGS Library Construction & Cloud Analysis
Driving efficiency and minimizing human error through advanced robotics and high-performance computing.
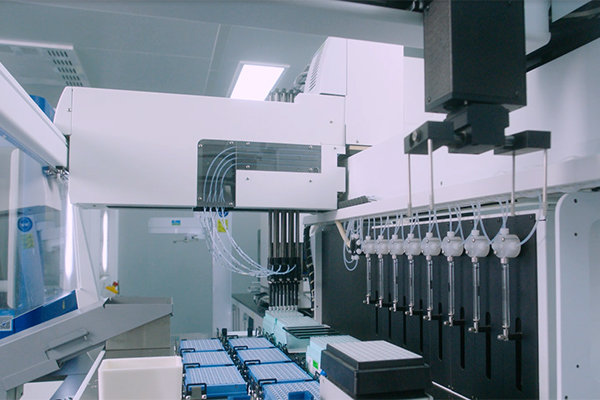
Brilliant Lab 1000 (BL1000) Automation
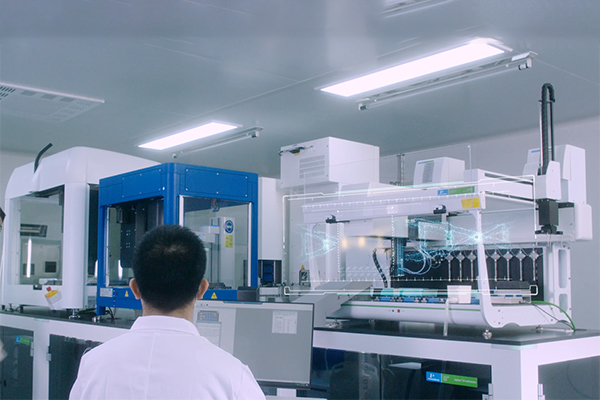
Biomarker Technologies (BMKGENE) and PerkinElmer have jointly built a fully automated experimental production line, called Brilliant Lab 1000 (BL1000), which is applied to our high-throughput NGS library construction service.
BMKGENE strives to greatly improve the entire line of sequencing products in terms of product types, production line throughput, delivery quality, and cycle time, to provide customers with better sequencing services.
BMKCloud Bioinformatic Analysis Platform
Our self-developed BMKCloud platform provides a reliable, easy-to-use online bioinformatic analysis environment. Powered by CPUs with 41,104 memory, 3 PB total storage, and 4,260 computing cores, it boasts a peak computing power exceeding 121,708.8 Gflop per second, enabling rapid multi-omic data integration.
Enterprise Qualification & Scientific Patents
Backed by more than 60 national invention patents, 200+ software copyrights, and international quality standards.


About Biomarker Technologies (BMKGene)
Biomarker Technologies (BMKGene), founded in 2009, is a leading genomics service provider with over 16 years of continuous innovation in high-throughput sequencing and bioinformatics. Backed by more than 60 national invention patents and 200+ software copyrights, we deliver comprehensive multi-omics solutions—spanning genomics, metagenomics, epigenetics, single-cell omics, transcriptomics, and our proprietary BMKMANU S3000 spatial transcriptome technology—supported by our advanced BMKCloud bioinformatics platform. We have established long-term collaborations with organizations across 84 regions worldwide, providing reliable genomic solutions on a global scale.
Our Complete Multi-Omics Product Catalog
Select from our full suite of sequencing and analysis services designed to power your research.