Featured Multi-Omics Integration Services
Explore our core high-throughput profiling technologies optimized for correlative analysis across genomics, transcriptomics, proteomics, and metabolomics.
Understanding Amplicon Sequencing in the Context of Proteomics & Metabolomics
In modern biological research, the isolation of a single molecular layer is no longer sufficient to explain complex biological phenomena. Life operates through a continuous cascade of information: from the genetic blueprint (genomics) to transcription (transcriptomics), translation into functional machinery (proteomics), and finally to the biochemical outputs of cellular processes (metabolomics). Amplicon sequencing, traditionally recognized as a targeted approach to profile specific genomic regions (such as the 16S rRNA gene in bacteria, 18S rRNA/ITS in fungi, or custom target genes), serves as the foundational taxonomic and genetic catalog. By integrating amplicon sequencing with proteomics and metabolomics, researchers can construct a complete functional map showing not just *who* is present in a biological system, but *what* they are capable of producing and *how* they actively alter the physiological environment.
Why Integrate Amplicon Sequencing with Proteomics & Metabolomics?
While amplicon sequencing identifies the taxonomic composition and potential functional pathways within a community (such as a microbiome), it cannot verify active gene expression or actual metabolic outputs. Proteomics bridges this gap by quantifying synthesized enzymes and structural proteins, while metabolomics directly measures the downstream substrates and products. Together, this multi-omic triad reveals the direct causal relationships between genetic identity, enzymatic activity, and metabolic phenotypes.
The Paradigm Shift in Multi-Omics Workflow Integration
Historically, genomics, proteomics, and metabolomics were treated as separate entities, analyzed in silos by different laboratories. Today, the industrial and academic landscape demands integrated multi-omics pipelines. When analyzing host-microbiome interactions, for example, amplicon sequencing identifies microbial community structures. Concurrently, metaproteomics identifies the active functional enzymes secreted by these microbes, and untargeted or targeted metabolomics measures the changes in short-chain fatty acids (SCFAs), bile acids, or lipid profiles. This holistic method eliminates false positives generated by genomic prediction alone, providing absolute empirical validation of biological pathways.
Industrial & Commercial Status of Amplicon Sequencing in Multi-Omics
The global market for multi-omics services is experiencing unprecedented growth, driven by the declining cost of high-throughput sequencing and the rising demand for personalized medicine, sustainable agriculture, and advanced biotechnology. Amplicon sequencing remains the most cost-effective and high-throughput method to characterize complex microbial ecosystems. Industrially, it is widely utilized for screening thousands of samples in clinical cohorts, soil health assessments, and food fermentation tracking. However, service providers are transitioning from offering single-omic data generation to providing complete multi-omic synthesis. High-throughput platforms like PacBio (Sequel II) and Oxford Nanopore (PromethION) have revolutionized amplicon sequencing by delivering full-length gene reads (e.g., full-length 16S rRNA, ITS, or custom metabolic gene clusters). This high taxonomic resolution is crucial when correlating microbial strains with specific proteomic profiles and metabolomic signatures, as even closely related strains can possess vastly different metabolic capabilities.
Development Trends: AI-Driven Multi-Omics Data Synthesis
A major bottleneck in multi-omics is data integration. The current trend focuses heavily on bioinformatics platforms that employ machine learning and artificial intelligence to correlate amplicon taxonomic abundances with mass spectrometry-derived proteomics and metabolomics datasets. By mapping amplicon data onto metabolic pathway databases (like KEGG and MetaCyc) and matching them with empirical proteomic expression levels, researchers can pinpoint precise metabolic nodes. This enables the discovery of novel biomarkers, the design of synthetic microbial consortia for industrial biomanufacturing, and the identification of therapeutic targets for metabolic disorders.
Fully Automated Platform: Brilliant Lab 1000
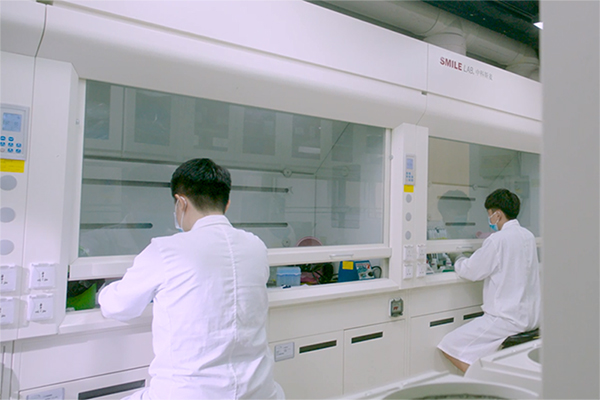
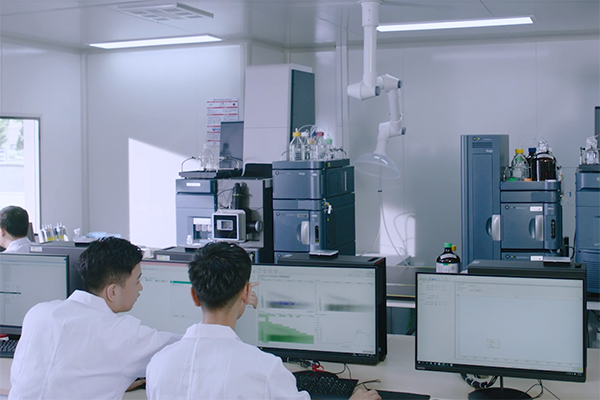
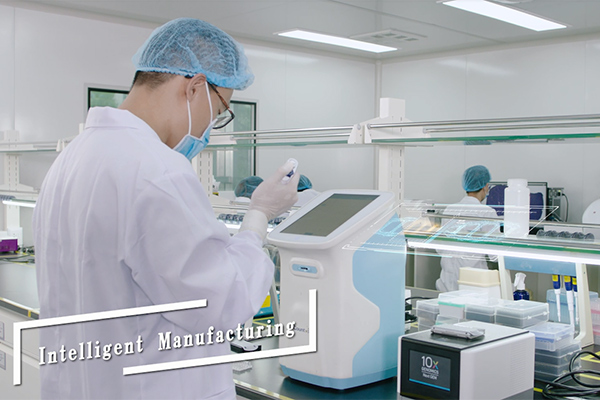
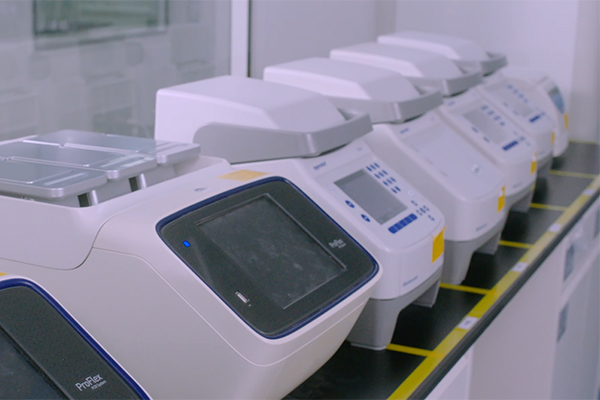
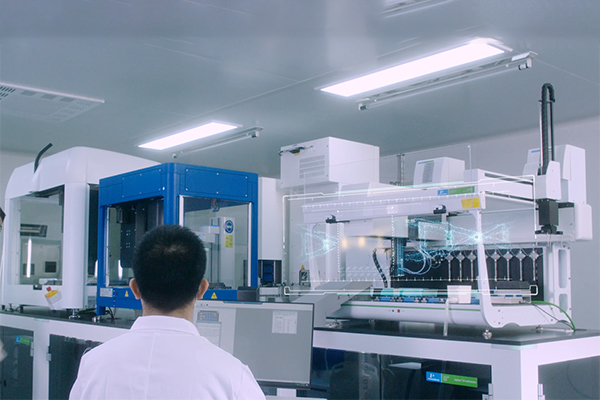
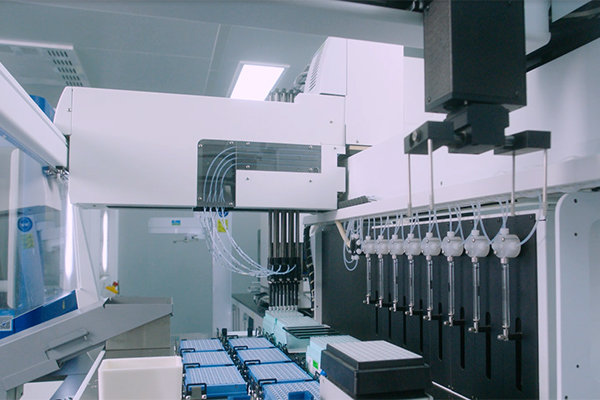
Biomarker Technologies (BMKGENE) and PerkinElmer have jointly built a fully automated experimental production line, called Brilliant Lab 1000 (BL1000), which is applied to the high-throughput NGS library construction service.
BMKGENE strives to greatly improve the entire line of sequencing products in terms of product types, production line throughput, delivery quality, and cycle time, to provide customers with better sequencing services.
Deep Application Scenarios of Integrated Amplicon-Proteo-Metabolomics
1. Clinical Medicine and Therapeutics
In human health, the gut microbiome acts as an endocrine organ, releasing metabolites that enter the bloodstream and impact distant systems. By combining amplicon sequencing of the gut microbiota with plasma proteomics and serum metabolomics, clinical researchers can identify specific bacterial taxa responsible for producing inflammatory proteins or protective metabolites like short-chain fatty acids. This integrated approach is currently driving drug discovery in inflammatory bowel disease (IBD), cardiovascular diseases, obesity-related metabolic syndromes, and even neurodegenerative disorders through the gut-brain axis.
2. Agricultural Biotechnology and Crop Resilience
Modern agriculture leverages the plant microbiome (rhizosphere and endosphere) to enhance nutrient uptake and pathogen resistance. Amplicon sequencing identifies the beneficial microbes colonizing the roots. Proteomics reveals the plant's defense proteins and the microbes' nitrogen-fixing enzymes, while metabolomics profiles root exudates (such as organic acids and flavonoids) that recruit specific microbial species. Understanding this three-way communication allows for the development of targeted bio-fertilizers and bio-pesticides, reducing reliance on chemical inputs.
3. Environmental Science and Bioremediation
In ecosystems affected by industrial pollutants, microbial communities adapt to degrade toxic compounds. Amplicon sequencing of functional genes (e.g., genes encoding alkane hydroxylases or biphenyl dioxygenases) reveals the genetic potential for biodegradation. Metaproteomics verifies if these degradation enzymes are actively expressed in response to the pollutant, and metabolomics monitors the breakdown intermediates and final non-toxic metabolites. This ensures the design of highly efficient bio-monitoring and in-situ bioremediation strategies.
About Biomarker Technologies (BMKGene)
A global pioneer in genomics and bioinformatics solutions, empowering scientific discovery for over 16 years.
Biomarker Technologies (BMKGene), founded in 2009, is a leading genomics service provider with over 16 years of continuous innovation in high-throughput sequencing and bioinformatics. Backed by more than 60 national invention patents and 200+ software copyrights, we deliver comprehensive multi-omics solutions—spanning genomics, metagenomics, epigenetics, single-cell omics, transcriptomics, and our proprietary BMKMANU S3000 spatial transcriptome technology—supported by our advanced BMKCloud bioinformatics platform. We have established long-term collaborations with organizations across 84 regions worldwide, providing reliable genomic solutions on a global scale.
Our Advanced Platforms
- PacBio Platforms: Sequel II, Sequel, RSII
- Nanopore Platforms: PromethION P48, GridION X5, MinION
- 10X Genomics: 10X ChromiumX, 10X Chromium Controller
- Illumina Platforms: NovaSeq
- BGI-Sequencing Platforms: DNBSEQ-G400, DNBSEQ-T7
- Bionano: Irys System
- Waters MS: XEVO G2-XS QTOF
- SCIEX MS: QTRAP 6500+
World-Class Laboratory Infrastructure
- Over 20,000 Square Feet: State-of-the-art facility optimized for molecular biology research.
- Advanced Instrumentation: Fully automated sample preparation, library construction, and quality control systems.
- Standardized Operations: Dedicated clean rooms and sequencing laboratories operating under strict SOPs.
- BMKCloud Bioinformatics: 4,260 computing cores with peak computing power over 121,708.8 Gflop/s, supported by 3 PB storage.


Enterprise Qualifications & Global Certifications
Demonstrating our commitment to the highest quality standards, technological innovation, and data integrity.


Our Comprehensive Product Portfolio
Explore our full suite of sequencing and multi-omics solutions designed to support your scientific breakthroughs.