Featured Sequencing Services
Cutting-edge molecular tools tailored for advanced target discovery and transcriptomic profiling.


Industrial and Commercial Status of Full-Length mRNA-Seq
The genomics landscape has witnessed a paradigm shift in transcriptomics analysis. While short-read Next-Generation Sequencing (NGS) has dominated the market for over a decade, it is fundamentally limited by the need to fragment RNA molecules before sequencing. This fragmentation obscures the connectivity between exons, leaving researchers to rely on probabilistic algorithms to reconstruct transcripts. Today, the industrial and commercial demand for Full-Length mRNA-Seq is expanding exponentially. Technology platforms powered by Pacific Biosciences (PacBio) Iso-Seq and Oxford Nanopore Technologies (ONT) have revolutionized how biotechnology companies, clinical researchers, and agricultural scientists approach gene expression analysis.
From a commercial standpoint, service providers are transitioning from offering simple count-based expression profiling to providing comprehensive, isoform-level resolution. This shift is critical for pharmaceutical companies engaged in target discovery and drug development. Recognizing the exact splice variants present in diseased tissues versus healthy controls is vital for designing highly specific therapeutic agents, such as antisense oligonucleotides (ASOs), small interfering RNAs (siRNAs), and monoclonal antibodies. Consequently, Full-Length mRNA-Seq has transitioned from a niche academic research tool to a foundational industrial platform for precision medicine, biotechnology, and agri-genomics.
No Transcript Assembly Required
Direct sequencing of intact, full-length cDNA or RNA molecules from the 5' end to the poly-A tail eliminates assembly errors and algorithmic bias.
Alternative Splicing Resolution
Accurately identify and quantify complex alternative splicing events, novel isoforms, and alternative polyadenylation (APA) sites across the transcriptome.
Fusion Gene & Modification Detection
Uncover gene fusion events and directly map chemical RNA modifications (such as m6A) without bisulfite conversion or chemical treatment.
Global Trends: The Future of Long-Read Transcriptomics
The global genomics market is experiencing a rapid convergence of long-read sequencing technologies and clinical diagnostics. One major trend is the reduction of sequencing costs, which previously limited the widespread adoption of full-length sequencing. With high-throughput platforms like the Nanopore PromethION P48 and PacBio Sequel II, the cost per gigabase has dropped significantly, making large-cohort clinical studies feasible.
Another prominent trend is the integration of Full-Length mRNA-Seq with single-cell and spatial transcriptomics. Traditional single-cell sequencing only capture the 3' or 5' ends of transcripts, missing critical structural information. By combining single-cell isolation with long-read sequencing, researchers can now profile full-length isoforms at single-cell resolution, revealing cell-type-specific splicing patterns that drive cellular differentiation and disease progression. Furthermore, direct RNA sequencing (dRNA-Seq) is gaining momentum as it avoids PCR amplification and reverse transcription biases, allowing for the simultaneous detection of RNA modifications and poly-A tail length dynamics.
Deep Application Scenarios of Full-Length mRNA-Seq
1. Clinical Oncology and Fusion Gene Discovery
Cancer genomes are characterized by massive structural variations, leading to abnormal splicing and the formation of oncogenic fusion genes. Short-read sequencing often fails to span the entire junction of fusion transcripts, resulting in false negatives. Full-Length mRNA-Seq reads through the entire chimeric molecule, providing unambiguous evidence of gene fusion events. This is instrumental in identifying novel fusion drivers in leukemia, sarcomas, and solid tumors, paving the way for personalized cancer therapies and companion diagnostics.
2. Neurodegenerative Disease Research
The human brain exhibits the highest complexity of alternative splicing of any organ. Dysregulation of splicing factors is a hallmark of neurodegenerative diseases such as Alzheimer's, Parkinson's, and Amyotrophic Lateral Sclerosis (ALS). Utilizing long-read sequencing allows scientists to characterize the complex isoform landscape of neuronal genes (e.g., MAPT, APP), identifying disease-specific splice variants that could serve as early-stage biomarkers or therapeutic targets.
3. Agri-Genomics and Crop Improvement
Many economically important crops possess complex polyploid genomes with highly repetitive regions, making transcript assembly with short reads nearly impossible. Full-Length mRNA-Seq enables the construction of high-quality reference transcriptomes (de novo transcriptomics) for non-model organisms. This helps agricultural scientists map gene structures, identify functional isoforms involved in abiotic stress tolerance (such as drought and salinity), and accelerate molecular breeding programs for high-yield crop varieties.
About Biomarker Technologies (BMKGene)
Biomarker Technologies (BMKGene), founded in 2009, is a leading genomics service provider with over 16 years of continuous innovation in high-throughput sequencing and bioinformatics. Backed by more than 60 national invention patents and 200+ software copyrights, we deliver comprehensive multi-omics solutions—spanning genomics, metagenomics, epigenetics, single-cell omics, transcriptomics, and our proprietary BMKMANU S3000 spatial transcriptome technology—supported by our advanced BMKCloud bioinformatics platform. We have established long-term collaborations with organizations across 84 regions worldwide, providing reliable genomic solutions on a global scale.
Our Platforms

PacBio platforms: Sequel II, Sequel, RSII
Nanopore platforms: PromethION P48, GridION X5, MinION
10X Genomics: 10X ChromiumX, 10X Chromium Controller
Illumina platforms: NovaSeq
BGI-sequencing platforms: DNBSEQ-G400, DNBSEQ-T7
Bionano Irys system
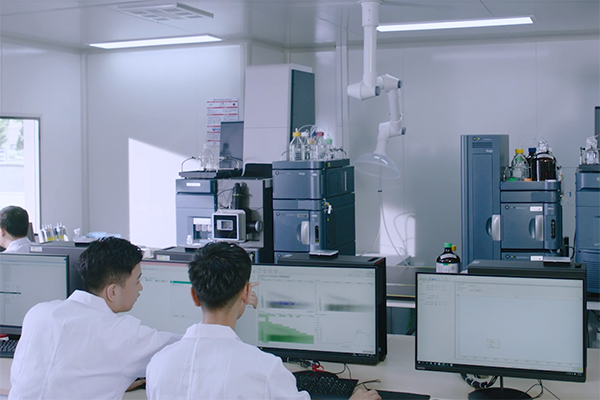
Waters XEVO G2-XS QTOF
QTRAP 6500+
Over 20,000 Square Feet Facility

Advanced biomolecular laboratory instruments designed for high-throughput genomic processing.
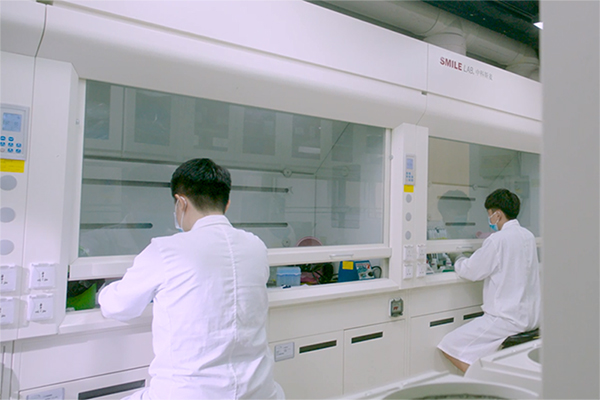
Standardized laboratories covering sample extraction, library construction, clean rooms, and dedicated sequencing rooms.
Standard operating procedures (SOPs) from sample receipt to data delivery, ensuring the highest data quality and consistency.
Reliable, Easy-to-use Bioinformatics

Our self-developed BMKCloud platform offers user-friendly online bioinformatic analysis tools.
Equipped with CPUs featuring 41,104 memory capacity and a total storage capacity of 3 PB.
Features 4,260 computing cores with a peak computing power exceeding 121,708.8 Gflop per second.
For inquiries about our products or pricelist, please leave your email to us.
We will be in touch within 24 hours to discuss your Full-Length mRNA-Seq project requirements.
Inquiry NowFully Automated NGS Platform: Brilliant Lab 1000
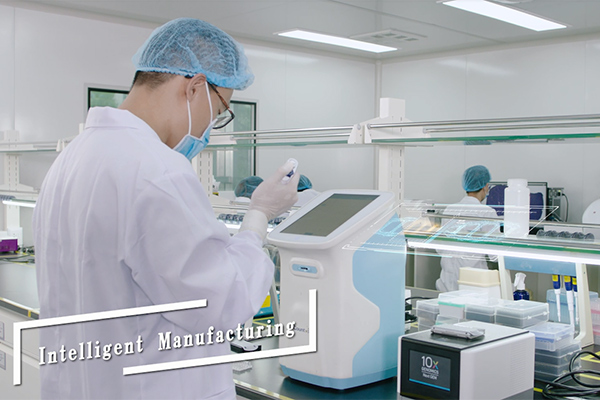
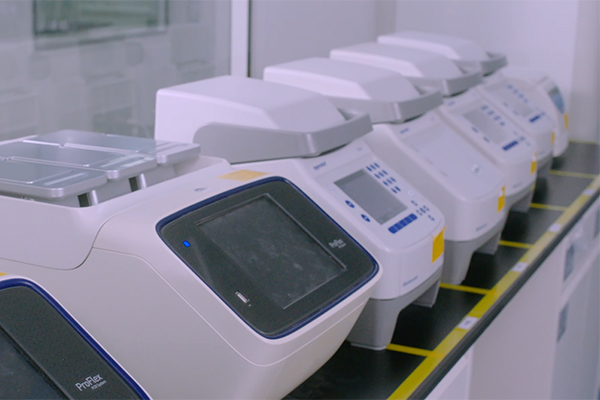
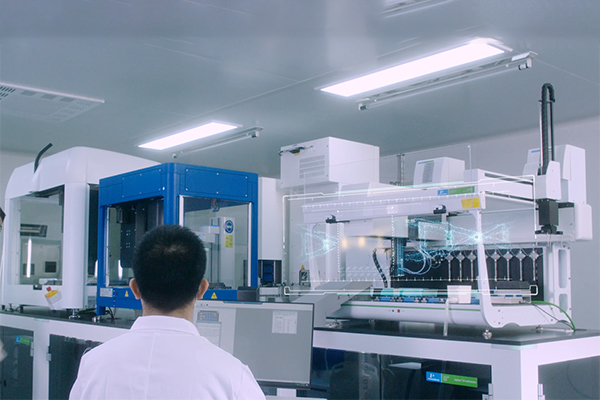
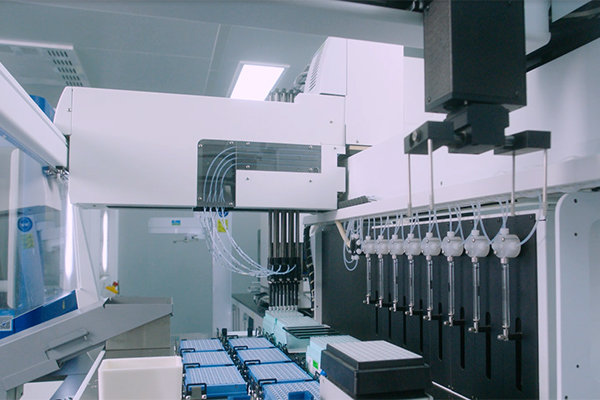
Biomarker Technologies (BMKGENE) and PerkinElmer have jointly built a fully automated experimental production line, called Brilliant Lab 1000 (BL1000), which is applied to high-throughput NGS library construction services.
BMKGENE strives to greatly improve the entire line of sequencing products in terms of product types, production line throughput, delivery quality, and cycle time, to provide customers with better sequencing services.


Complete Sequencing Portfolio
Explore our full range of sequencing services designed to meet diverse research goals.