
Featured Genomic Sequencing Services
Explore our core high-throughput sequencing and mapping services engineered to unlock deep genomic insights.
Deep Dive: Haplotype-Resolved Phased Genomes
Why phasing is reshaping the landscape of modern bio-industry, agricultural selection, and precision medicine.
In the era of precision genomics, the standard reference genome assembly is undergoing a massive paradigm shift. Traditionally, genomic sequencing platforms collapsed diploid or polyploid chromosomes into a single, artificial "consensus" reference genome. While this simplified computational analysis, it completely obscured the critical differences between maternal and paternal chromosomes. Enter Haplotype-Resolved Phased Genomes—the gold standard of modern genome assembly that separates and reconstructs the precise genetic sequences of homologous chromosome pairs.
Generating a haplotype-resolved phased genome involves identifying which genetic variants (SNPs, Indels, and structural variations) reside together on the same chromosome inherited from a single parent. This process, known as phasing, is crucial for understanding allele-specific expression, compound heterozygosity, and structural variations that dictate complex phenotypic traits. Without phasing, key biological mechanisms remain invisible to researchers and clinical diagnosticians alike.
Organisms inherit two sets of chromosomes. Collapsing these distinct parental sequences into a single reference sequence generates a mosaic genome that does not exist in nature. Phased genomes solve this by generating true-to-life, haplotype-specific representations of genetic code.
Industrial & Commercial Landscape
The commercial demand for haplotype-resolved phased genomes has surged alongside the maturation of long-read sequencing technologies. In the agricultural sector, commercial breeders rely on phased genomes to untangle the highly complex, polyploid genomes of cash crops such as wheat, sugarcane, and potatoes. Identifying which parent contributed a specific disease-resistance or yield-enhancing allele allows for marker-assisted selection and gene-editing programs with unprecedented precision.
In the biopharmaceutical and clinical diagnostics industries, the application of phased genomes is revolutionizing drug discovery and personalized medicine. For instance, in human health, knowing whether two mutations are on the same chromosome (in cis) or on different chromosomes (in trans) determines if a patient has one functional copy of a gene or none. This distinction is critical for diagnosing recessive genetic disorders and predicting patient responses to targeted therapies.
Key Industrial Applications & Deep Scenarios
1. Agricultural Polyploid Breeding
Unraveling polyploid crop genomes (like tetraploid potatoes or hexaploid wheat) to map valuable traits to specific homologous chromosomes, accelerating the development of resilient, high-yield crop varieties.
2. Rare Disease Diagnostics
Identifying compound heterozygous mutations where a patient inherits two different mutations in the same gene. Phasing confirms if both copies of the gene are disrupted, confirming clinical diagnoses.
3. Cancer Genomics & Immunotherapy
Analyzing allele-specific expression and somatic mutations in tumors. Phased genomes help identify novel tumor neoantigens, paving the way for highly personalized cancer vaccines.
Future Development Trends
Looking forward, the integration of artificial intelligence (AI) and machine learning with long-read sequencing technologies is set to democratize haplotype-resolved assembly. Currently, constructing phased genomes requires high-coverage long-read data combined with parental sequencing (trio binning) or physical mapping techniques like Hi-C. Emerging AI-driven assembly algorithms are beginning to phase complex genomes directly from single-individual sequencing data without requiring parental samples, drastically reducing the cost and complexity of projects.
Furthermore, the global scientific community is shifting from single reference genomes to "pan-genomes"—collections of phased genomes representing the entire genetic diversity of a species. This approach allows researchers to capture structural variations and copy number variations that are completely missed by traditional sequencing pipelines, setting a new benchmark for genomic content creation and bioinformatic analysis.
Biomarker Technologies (BMKGene)
Over 16 years of continuous innovation in high-throughput sequencing and bioinformatics.
Biomarker Technologies (BMKGene), founded in 2009, is a leading genomics service provider with over 16 years of continuous innovation in high-throughput sequencing and bioinformatics. Backed by more than 60 national invention patents and 200+ software copyrights, we deliver comprehensive multi-omics solutions—spanning genomics, metagenomics, epigenetics, single-cell omics, transcriptomics, and our proprietary BMKMANU S3000 spatial transcriptome technology—supported by our advanced BMKCloud bioinformatics platform. We have established long-term collaborations with organizations across 84 regions worldwide, providing reliable genomic solutions on a global scale.
Our mission is to empower life science research by offering cutting-edge sequencing technologies, robust bioinformatic pipelines, and highly automated laboratory services. We are dedicated to translating complex genomic data into actionable biological insights for researchers in agriculture, medicine, and environmental science.

Our Leading Sequencing & Bioinformatic Platforms
Multi-level Sequencing Platforms
PacBio platforms: Sequel II, Sequel, RSII
Nanopore platforms: PromethION P48, GridION X5, MinION
10X Genomics: 10X ChromiumX, 10X Chromium Controller
Illumina platforms: NovaSeq
BGI-sequencing platforms: DNBSEQ-G400, DNBSEQ-T7
Bionano Irys system
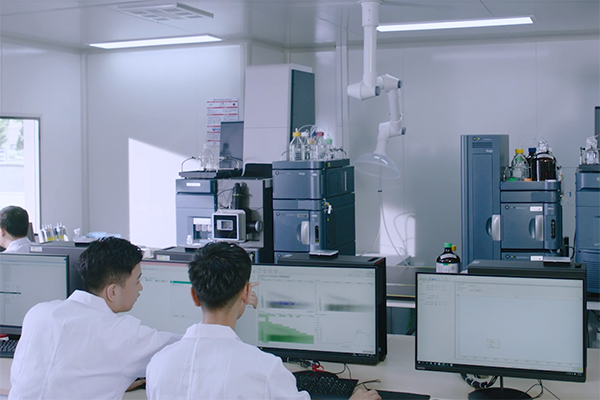
Waters XEVO G2-XS QTOF & QTRAP 6500+
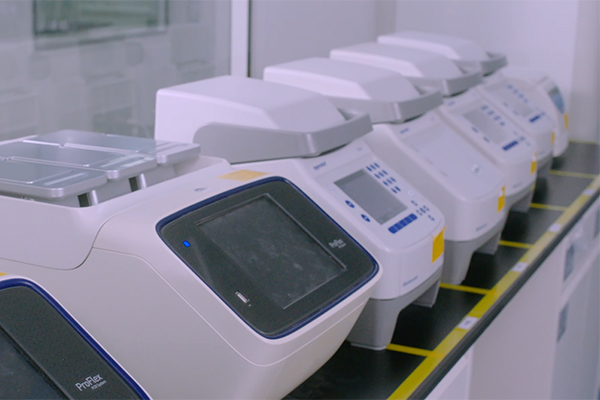
Advanced Molecular Laboratory
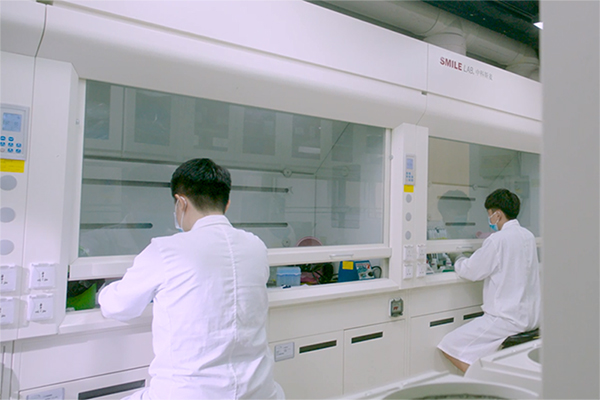
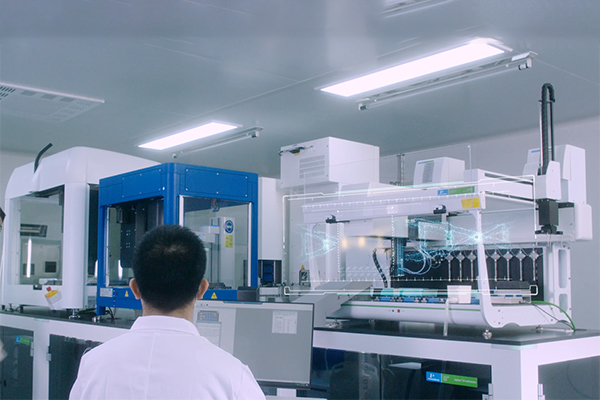
Our facility features advanced biomolecular laboratory instruments, structured into standard labs for sample extraction, library construction, clean rooms, and sequencing operations. Every step is executed under strict SOPs to ensure sample integrity and high-quality data generation.

BMKCloud Bioinformatic Platform
Our self-developed online platform features 4,260 computing cores and a peak computing power exceeding 121,708.8 Gflop per second. Backed by CPUs with 41,104 memory and 3 PB total storage, it offers researchers robust, easy-to-use analysis pipelines.

Fully Automated NGS Library Construction
Jointly built by Biomarker Technologies (BMKGENE) and PerkinElmer.
Brilliant Lab 1000 (BL1000)
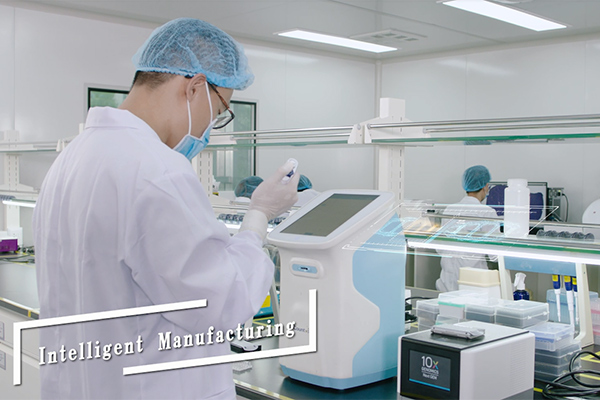
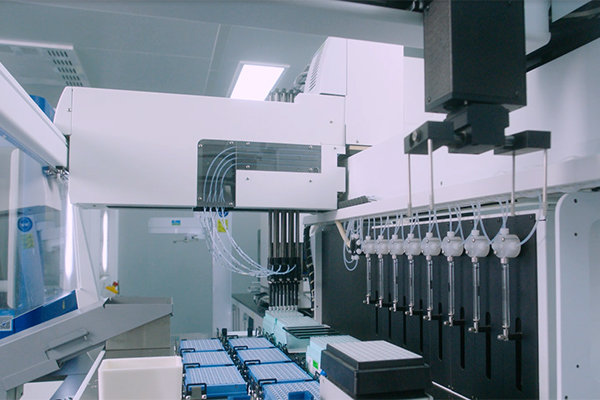
Biomarker technologies (BMKGENE) and PerkinElmer have jointly built a fully automated experimental production line, called Brilliant Lab 1000 (BL1000), which is applied to the high-throughput NGS library construction service.
BMKGENE strives to greatly improve the entire line of sequencing products in terms of product types, production line throughput, delivery quality, and cycle time, to provide customers with better sequencing services.
Inside Our State-of-the-Art Automated Facilities
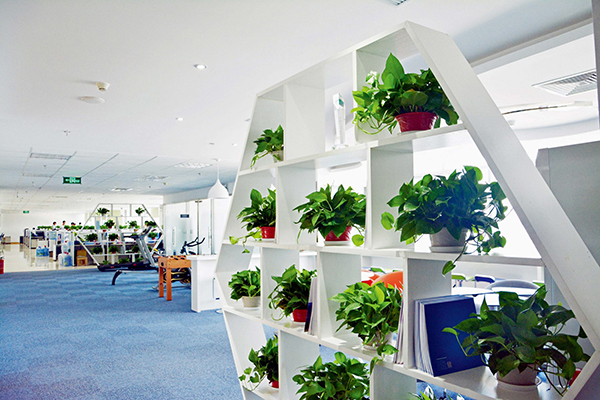
Enterprise Qualifications & Patents
Our commitment to quality management, continuous research, and proprietary technological innovation.


For inquiries about our products or pricelist, please leave your email to us. We will be in touch within 24 hours.
Inquiry NowOur Complete Sequencing Product Portfolio

Specific-Locus Amplified Fragment Sequencing (SLAF-Seq)
Genotyping
Hi-C based Chromatin Interaction
3D Genomics
Metagenomics (NGS)
Microbiome
Chromatin Immunoprecipitation Sequencing (ChIP-seq)
Epigenetics
Metatranscriptome Sequencing
Transcriptomics
PacBio 2+3 Full-Length mRNA Solution
Iso-Seq
Hi-C Based Genome Assembly
De Novo Assembly


