Featured Low-Input lncRNA Sequencing Solutions
High-performance genomics workflows tailored for limited sample volumes and complex transcriptomic profiles.
Introduction to lncRNA and the Low-Input Sample Paradigm
Long non-coding RNAs (lncRNAs) represent a diverse class of RNA molecules transcripts longer than 200 nucleotides that do not translate into functional proteins. Once dismissed as genomic "dark matter" or transcriptional noise, lncRNAs are now recognized as pivotal regulators of cellular physiology. They control gene expression at epigenetic, transcriptional, and post-transcriptional levels through interactions with DNA, RNA, and proteins. Consequently, lncRNAs have emerged as key players in developmental biology, immunology, and oncology.
Despite their biological significance, profiling lncRNAs presents unique technical challenges. Unlike messenger RNAs (mRNAs), lncRNAs are typically expressed at lower levels and exhibit highly tissue- and cell-type-specific patterns. This problem is compounded when working with low-input samples, such as clinical biopsies, circulating tumor cells (CTCs), exosomes, microdissected tissues, or early-stage embryos. Standard RNA sequencing (RNA-Seq) protocols often require micrograms of high-quality total RNA, which is unattainable for these precious samples. To address this limitation, specialized low-input lncRNA sequencing solution framing is required, combining ultra-sensitive library preparation, efficient ribosomal RNA (rRNA) depletion, and powerful bioinformatic algorithms.
Commercial and Industrial Landscape of lncRNA Sequencing
The biotechnology and pharmaceutical industries have witnessed a surge in demand for non-coding RNA analysis. In precision oncology, lncRNAs are utilized as highly specific biomarkers. Because their expression is tightly linked to specific tumor stages and subtypes, profiling lncRNAs from liquid biopsies (such as blood or urine) offers a non-invasive method for early cancer detection and treatment monitoring.
In the therapeutic sector, lncRNAs are no longer just diagnostic targets; they are therapeutic entities. Companies are actively developing RNA-targeted therapeutics, including antisense oligonucleotides (ASOs) and small interfering RNAs (siRNAs), designed to modulate lncRNA activity. To validate these therapies, researchers require robust sequencing workflows that can detect target knockdown in small tissue biopsies or primary cell cultures.
Furthermore, the agricultural biotechnology sector leverages lncRNA sequencing to study plant development and stress tolerance. Whether analyzing plant meristems or specific cell types under drought conditions, low-input sequencing allows researchers to map regulatory networks in micro-scale samples, driving the development of climate-resilient crops.
Overcoming Technical Bottlenecks in Low-Input RNA-Seq
Sequencing lncRNAs from low starting material (often less than 10 ng of total RNA) requires addressing three major obstacles:
Ribosomal RNA Domination
rRNA constitutes over 80-90% of total cellular RNA. For lncRNA sequencing, poly(A) selection is insufficient because many lncRNAs are non-polyadenylated. Therefore, target-specific rRNA depletion is mandatory. BMKGene utilizes optimized enzymatic digestion and hybridization strategies to remove rRNA from low-yield samples without degrading precious non-coding transcripts.
Library Complexity Loss
Low-input samples are prone to PCR duplication and bias during library amplification, leading to a loss of transcript diversity. BMKGene addresses this by employing high-fidelity, low-cycle amplification enzymes and molecular identifiers (UMIs) to track individual transcripts, ensuring quantitative accuracy.
Strand-Specific Integrity
Many lncRNAs overlap with protein-coding genes on opposite strands (antisense lncRNAs). Standard RNA-Seq cannot distinguish which strand a transcript originated from. BMKGene's strand-specific library preparation preserves this directional information, crucial for identifying antisense regulatory mechanisms.
In-Depth Application Scenarios for Low-Input lncRNA-Seq
1. Oncology and Liquid Biopsies
Tumor cells shed exosomes containing RNA (including lncRNAs) into the bloodstream. By isolating these exosomes from plasma, researchers can obtain a snapshot of the tumor microenvironment. Since the amount of exosomal RNA is extremely small (often in the picogram range), our low-input lncRNA-Seq solution framing allows for deep profiling of these biofluids, facilitating the discovery of novel cancer biomarkers and monitoring treatment resistance in real-time.
2. Single-Cell and Spatial Transcriptomics Integration
While single-cell RNA-Seq provides cellular resolution, spatial transcriptomics preserves the tissue context. Combining low-input lncRNA sequencing with spatial technologies, such as our proprietary BMKMANU S3000 spatial transcriptome platform, allows researchers to map lncRNA expression within specific tissue niches, revealing how non-coding RNAs regulate cellular communication in complex organs like the brain.
3. Developmental Biology and Stem Cell Research
Early embryonic development is governed by rapid changes in gene expression, heavily regulated by lncRNAs. Utilizing low-input sequencing, scientists can profile lncRNAs from single blastomeres or small embryonic structures, shedding light on the molecular switches that guide differentiation and pluripotency.
4. Neurogenomics
The mammalian brain expresses more lncRNAs than any other organ, with many restricted to specific neural subpopulations or brain regions. By using laser capture microdissection (LCM) to isolate precise brain nuclei, researchers can leverage our low-input solutions to study the role of lncRNAs in cognitive function, synaptic plasticity, and neurodegenerative diseases like Alzheimer's and Parkinson's.
Biomarker Technologies (BMKGene)
Biomarker Technologies (BMKGene), founded in 2009, is a leading genomics service provider with over 16 years of continuous innovation in high-throughput sequencing and bioinformatics. Backed by more than 60 national invention patents and 200+ software copyrights, we deliver comprehensive multi-omics solutions—spanning genomics, metagenomics, epigenetics, single-cell omics, transcriptomics, and our proprietary BMKMANU S3000 spatial transcriptome technology—supported by our advanced BMKCloud bioinformatics platform. We have established long-term collaborations with organizations across 84 regions worldwide, providing reliable genomic solutions on a global scale.
Our High-Throughput Sequencing Platforms
- PacBio platforms: Sequel II, Sequel, RSII
- Nanopore platforms: PromethION P48, GridION X5, MinION
- 10X Genomics: 10X ChromiumX, 10X Chromium Controller
- Illumina platforms: NovaSeq
- BGI-sequencing platforms: DNBSEQ-G400, DNBSEQ-T7
- Bionano Irys system, Waters XEVO G2-XS QTOF, and QTRAP 6500+


Advanced Automated Lab Facilities
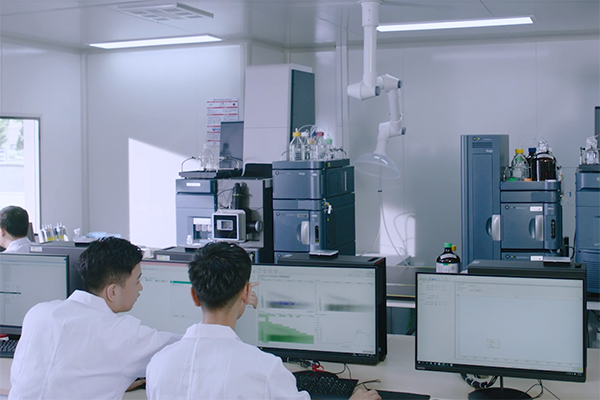
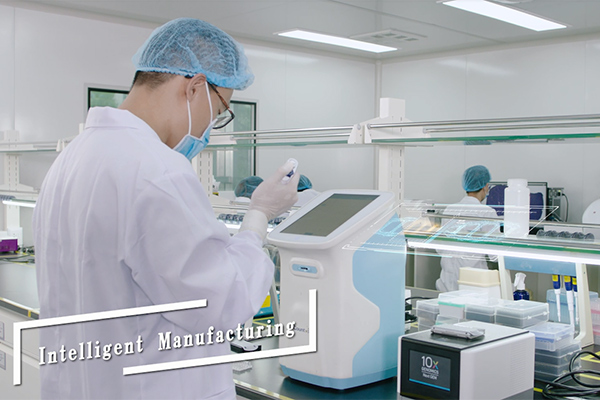
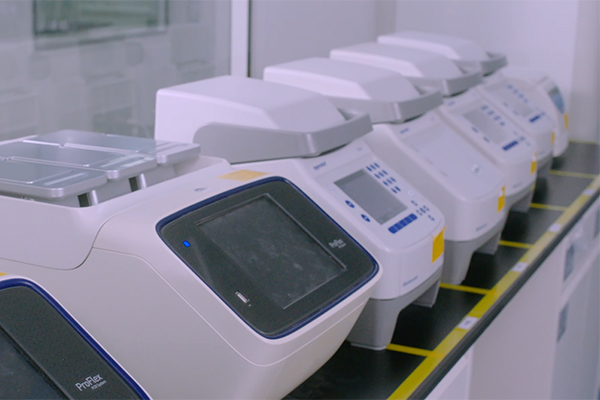
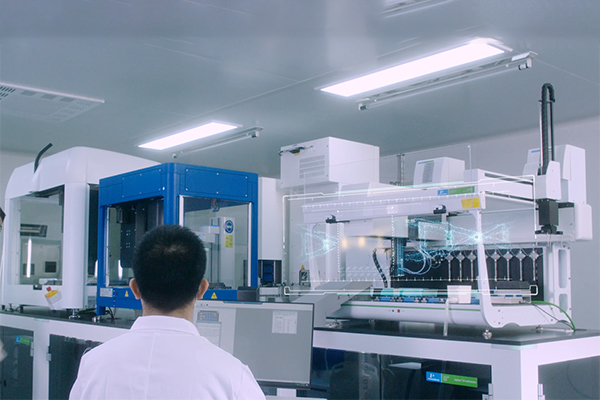
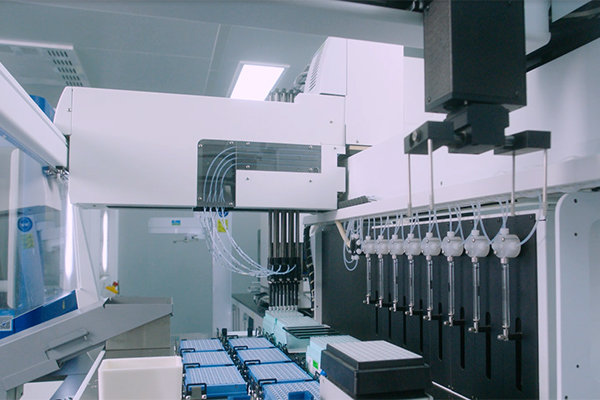
Operating from a facility spanning over 20,000 square feet, our laboratory features advanced biomolecular instruments and standard labs designed for sample extraction, library construction, clean rooms, and sequencing. Every phase of our workflow, from sample extraction to sequencing, is conducted under strict Standard Operating Procedures (SOPs).
BMKCloud Bioinformatics Platform: Our self-developed cloud platform provides a reliable, easy-to-use online analysis environment. Equipped with CPUs featuring 41,104 memory, 3 PB of total storage, and 4,260 computing cores, the platform achieves a peak computing power exceeding 121,708.8 Gflop per second, enabling rapid and robust data processing.
Flexible Experimental Designs
We offer multiple and flexible experimental designs to fulfill diverse research goals. By tailoring library construction pathways, sequencing depths, and bioinformatic pipelines, we ensure that every low-input sample project is optimized for maximum transcript recovery and biological insight.

Fully Automated NGS Library Construction
Brilliant Lab 1000 (BL1000) — Eliminating manual variance for low-input samples.
Brilliant Lab 1000 (BL1000)
Biomarker Technologies (BMKGene) and PerkinElmer have jointly built a fully automated experimental production line, called Brilliant Lab 1000 (BL1000), which is applied to the high-throughput NGS library construction service.
BMKGENE strives to greatly improve the entire line of sequencing products in terms of product types, production line throughput, delivery quality, and cycle time, to provide customers with better sequencing services.
Our State-of-the-Art Facilities
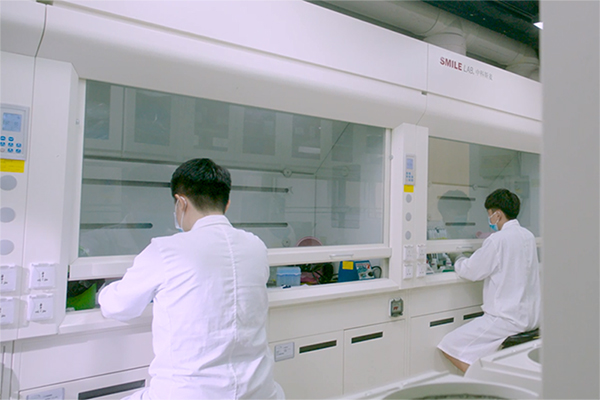
Enterprise Qualification & Patents
A legacy of scientific excellence, standard operations, and intellectual property.


Our Complete Product Portfolio
Explore our full suite of sequencing services and molecular products optimized for diverse transcriptomic applications.

Comparative Genomics for lncRNA Profiling

TGuide Smart Universal DNA/RNA Kit
Low-Input Metagenomic & Transcriptomic Sequencing
Low-Input circ-RNA & lncRNA Analysis
Nanopore Full-length lncRNA Transcriptomics

Bulked Segregant Analysis for Transcriptomics

Integrated lncRNA-Metabolomics Solutions