Featured Transcriptomics & Genomics Technologies
Explore our core low-input sequencing services and molecular solutions tailored to maximize discovery from precious, low-yield biological samples.


Deep-Dive: Low-Input mRNA-Seq for Genome Sequencing Content Creation
In modern genomics, the ability to generate high-quality transcriptomic data from limited starting material has shifted from a niche experimental requirement to an industrial standard. Low-Input mRNA-Seq refers to the methods and technologies optimized to sequence messenger RNA from samples containing minute amounts of total RNA—often ranging from sub-nanogram levels down to single-digit picograms. This capability is pivotal for modern genome sequencing content creation, enabling researchers, clinical laboratories, and biotech companies to unlock biological insights that were previously hidden due to technological limitations.
Traditional RNA-Seq protocols require microgram quantities of high-integrity total RNA. However, in real-world clinical and ecological scenarios—such as circulating tumor cells (CTCs), micro-dissected tissues, fine-needle biopsies, and environmental micro-samples—extracting such quantities is impossible. Low-input technologies bypass these limits through specialized template-switching mechanisms, optimized cDNA amplification, and highly sensitive library preparation chemistry, preventing sample loss and maintaining transcript representation without introducing excessive PCR duplication bias.
Commercial & Industrial Landscape of Low-Input Transcriptomics
The biotechnology industry is witnessing an exponential demand for low-input sequencing solutions. From pharmaceutical drug development to personalized oncology, the commercial applications are vast. Contract Research Organizations (CROs) and genomic service providers are continuously upgrading their workflows to support low-input pipelines. The industrialization of these workflows has led to lower per-sample costs, faster turnaround times, and higher reproducibility. By standardizing automated library construction, manufacturers can process thousands of low-input samples simultaneously, providing the scale required for large-cohort clinical trials and agricultural breeding programs.
Development Trends & Future Outlook
Looking forward, the integration of long-read sequencing technologies (such as PacBio and Oxford Nanopore) with low-input protocols is set to redefine isoform detection. While short-read sequencing (Illumina) remains the gold standard for quantitative expression profiling, long-read sequencing offers full-length transcript characterization without assembly artifacts. Additionally, the convergence of low-input mRNA-Seq with spatial transcriptomics allows researchers to map gene expression profiles back to their original physical coordinates within tissue slices, offering an unprecedented look at cellular microenvironments.
Deep-Dive Application Scenarios
1. Oncology & Liquid Biopsies
In cancer research, monitoring disease progression and treatment response through non-invasive methods is crucial. Liquid biopsies isolate circulating tumor cells (CTCs) or exosomes from blood samples. Because the yield of RNA from these sources is extremely low, low-input mRNA-Seq is the only viable pathway to analyze the dynamic transcriptome of tumor cells in real-time. This reveals emerging drug-resistance mutations and alternative splicing events, guiding oncologists to adjust therapies dynamically.
2. Developmental Biology & Embryology
Understanding early embryonic development requires analyzing gene expression patterns within individual blastomeres or small cell clusters. Low-input sequencing allows developmental biologists to track transcriptional changes during zygotic genome activation without pooling multiple embryos. This preserves the unique genetic identity of each sample, providing clear insights into lineage commitment and developmental abnormalities.
3. Agricultural & Environmental Genomics
In plant biology and environmental metagenomics, researchers often work with difficult-to-extract samples, such as single root hairs, specific floral compartments, or microscopic soil organisms. Low-input sequencing enables the profiling of these fragile biological systems, paving the way for the discovery of novel stress-tolerance genes, plant-microbe symbiotic pathways, and metabolic networks that can be engineered for climate-resilient agriculture.
4. Stem Cell Differentiation & Therapeutics
Stem cell therapies rely on precise differentiation protocols. During these processes, rare subpopulations of cells may transition into unexpected lineages. Low-input mRNA-Seq allows quality control teams to isolate and sequence these minor subpopulations, ensuring the purity and safety of stem-cell-derived therapeutic products before clinical application.
About Biomarker Technologies (BMKGene)
Biomarker Technologies (BMKGene), founded in 2009, is a leading genomics service provider with over 16 years of continuous innovation in high-throughput sequencing and bioinformatics. Backed by more than 60 national invention patents and 200+ software copyrights, we deliver comprehensive multi-omics solutions—spanning genomics, metagenomics, epigenetics, single-cell omics, transcriptomics, and our proprietary BMKMANU S3000 spatial transcriptome technology—supported by our advanced BMKCloud bioinformatics platform. We have established long-term collaborations with organizations across 84 regions worldwide, providing reliable genomic solutions on a global scale.
Our Advanced Multi-level High-Throughput Sequencing Platforms
Our facilities are equipped with a diverse suite of sequencing platforms, enabling us to tailor our services to the exact depth, read length, and throughput requirements of each project.

Sequencing Platforms
PacBio platforms: Sequel II, Sequel, RSII
Nanopore platforms: PromethION P48, GridION X5 MinION
10X Genomics: 10X ChromiumX, 10X Chromium Controller
Illumina platforms: NovaSeq
BGI-sequencing platforms: DNBSEQ-G400, DNBSEQ-T7
Bionano Irys system
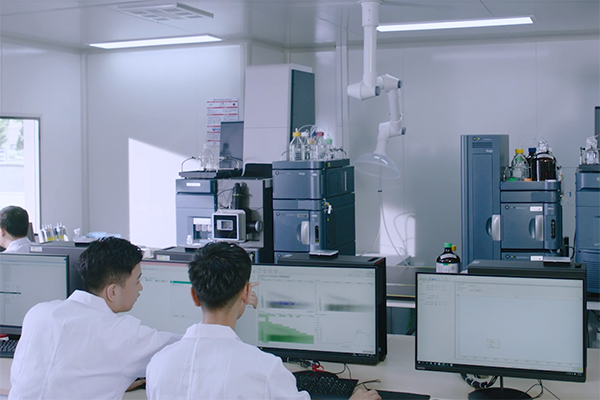
Waters XEVO G2-XS QTOF
QTRAP 6500+

World-Class Facilities
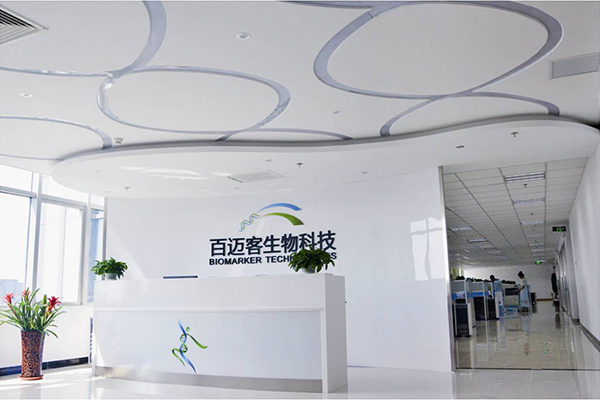
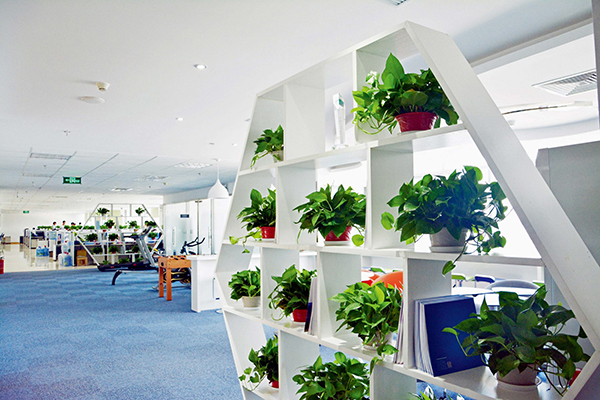
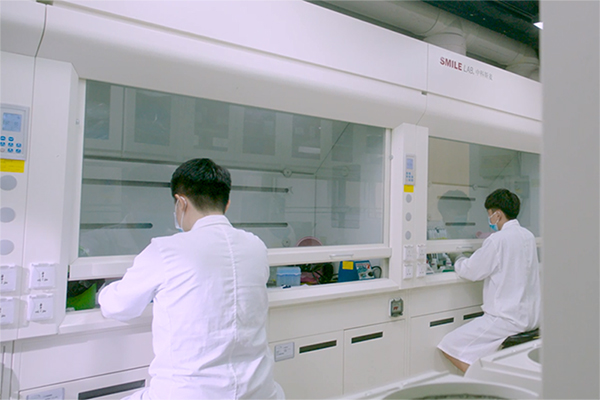
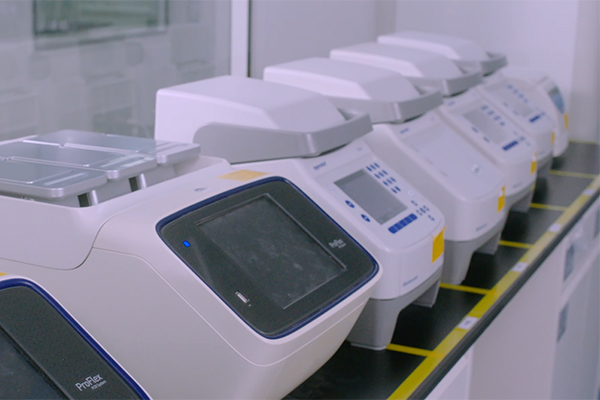
Our operations span over a 20,000 square feet facility equipped with advanced biomolecular laboratory instruments.
We feature standard laboratories for sample extraction, library construction, clean rooms, and dedicated sequencing rooms.
All procedures, from sample receipt to final data delivery, are carried out under strict Standard Operating Procedures (SOPs).

BMKCloud Bioinformatic Platform
We provide a reliable, easy-to-use online bioinformatics analysis platform developed in-house.
Powered by CPUs with 41,104 memory and a massive 3 PB total storage capacity.
Features 4,260 computing cores with a peak computing power exceeding 121,708.8 Gflop per second, ensuring rapid data analysis.
Automated Workflows & Production Capabilities
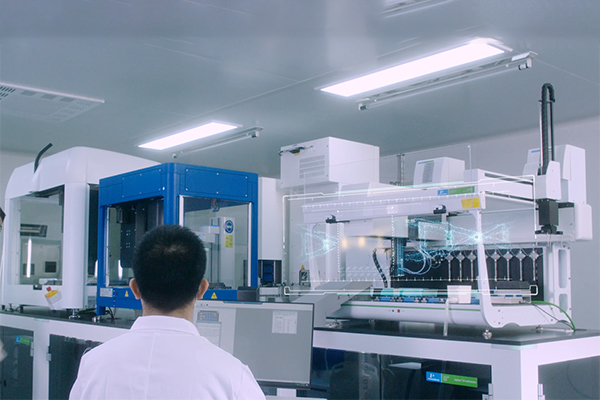
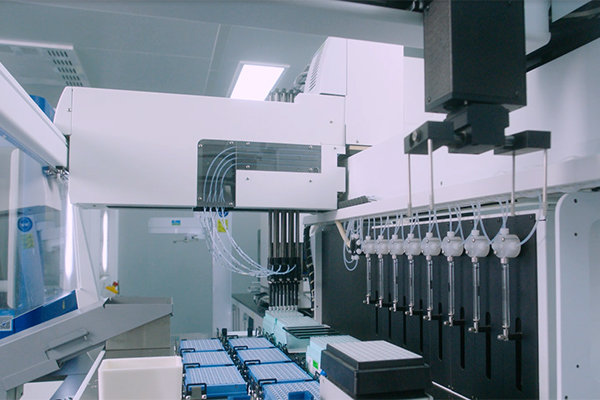
Fully Automated Platform for Next-generation sequencing--Brilliant Lab 1000
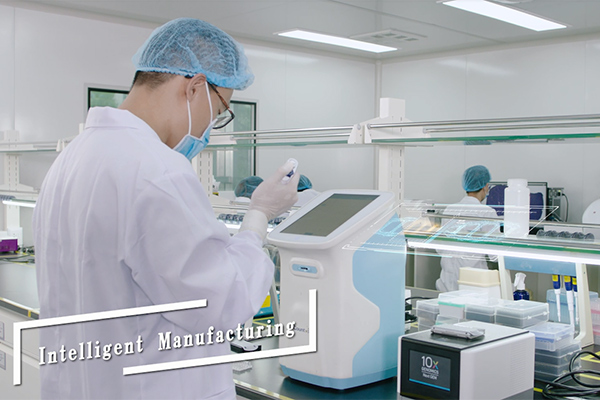
Biomarker technologies (BMKGENE) and PerkinElmer have jointly built a fully automated experimental production line, called Brilliant Lab 1000 (BL1000), which is applied to the high-throughput NGS library construction service.
BMKGENE strives to greatly improve the entire line of sequencing products in terms of product types, production line throughput, delivery quality, and cycle time, to provide customers with better sequencing services.
Our State-of-the-Art Sequencing Facilities
Enterprise Qualifications & Certifications
Our commitment to excellence is backed by international quality standards, academic partnerships, and extensive patent portfolios.


Proprietary Patents & Software Copyrights
Our continuous investment in research and development has yielded an extensive IP portfolio, ensuring protected, high-performance methodologies for our clients.


Explore Our Full Range of Genomic Products & Services
Discover our comprehensive suite of high-throughput sequencing services, automated DNA extraction kits, and advanced transcriptomics solutions.