
Featured Multi-Omics & Sequencing Solutions
Discover our core services bridging genomic sequencing and proteomic profiling for comprehensive biological insights.

Eukaryotic mRNA-Seq & Proteomics Integration
Learn More →
Metagenomics & Metaproteomics Co-analysis
Learn More →
[Copy] Eukaryotic mRNA-Seq & Quantitative Proteomics
Learn More →
Evolutionary Genetics & Comparative Proteomics
Learn More →The Paradigm Shift: Mass Spectrometry-Based Proteomics in the Era of Genomics
In modern life sciences, the transition from genomics to multi-omics has revolutionized our understanding of biological complexity. While genomics provides the blueprint of life, proteins are the functional executioners of cellular processes. Consequently, genomic sequencing alone often falls short of capturing dynamic cellular states, post-translational modifications, and real-time physiological responses. This is where Mass Spectrometry-Based Proteomics enters the spotlight, serving as an indispensable pillar in next-generation sequencing (NGS) and multi-omics service pipelines.
Commercial & Industrial Landscape: The Multi-Omics Synergy
The global biotechnology and pharmaceutical industries are experiencing a massive surge in demand for integrated sequencing and proteomics services. Traditionally, genomics and proteomics operated in silos. Today, contract research organizations (CROs) and research service providers must offer unified multi-omics platforms to remain competitive. By combining high-throughput sequencing technologies (such as Illumina, PacBio, and Oxford Nanopore) with state-of-the-art mass spectrometers (like Waters QTOF and QTRAP systems), service providers can deliver comprehensive readouts that accelerate drug discovery, biomarker validation, and agricultural trait selection.
Industrially, this integration optimizes research budgets and timelines. Pharma companies no longer need to coordinate with separate vendors for genomic sequencing and proteomic profiling. A single, unified workflow reduces sample consumption, eliminates batch effects across different laboratories, and provides harmonized bioinformatics analysis, significantly streamlining the regulatory pathway for clinical trials and therapeutic approvals.
Emerging Technological Trends in Quantitative Proteomics
The field of mass spectrometry-based proteomics is evolving rapidly, driven by innovations in instrument sensitivity, sample preparation, and computational biology. Key trends include:
- Data-Independent Acquisition (DIA-MS): Unlike traditional Data-Dependent Acquisition (DDA), DIA sweeps through pre-defined mass-to-charge ranges, fragmenting all ions within those windows. This results in highly reproducible, high-throughput protein quantification with fewer missing values, making it ideal for large-scale clinical cohorts.
- Tandem Mass Tagging (TMT): Isobaric labeling techniques like TMT allow multiplexing of up to 16 or 18 samples in a single LC-MS/run, drastically reducing machine time and minimizing experimental variation.
- Single-Cell Proteomics: Mirroring the success of single-cell RNA sequencing (scRNA-seq), ultra-sensitive mass spectrometers can now profile proteomes of single cells, revealing cellular heterogeneity that bulk proteomics hides.
- Spatial Proteomics: Combining imaging mass spectrometry with spatial transcriptomics allows researchers to map protein expression and distribution directly within tissue microenvironments, preserving crucial spatial context.
Genomic-Proteomic Correlation
Directly link transcript abundance with actual protein copy numbers to uncover post-transcriptional regulatory mechanisms.
Isoform Verification
Validate alternative splicing events detected by PacBio or Nanopore long-read sequencing at the functional protein level.
Bioinformatics Integration
Leverage cloud computing to merge genomic variant calling with mass spectrometry peptide mapping for proteogenomics.
Deep Application Scenarios
1. Precision Medicine and Oncology
In cancer research, the genome reveals mutations (such as SNPs and indels), but the proteome reveals the phenotypic consequences of those mutations. Mass spectrometry-based proteomics is critical for defining the "druggable" proteome. For instance, in neoantigen discovery, researchers use RNA-seq to identify tumor-specific mutations, and then employ mass spectrometry (immunopeptidomics) to verify whether these mutated peptides are actually presented by MHC molecules on the cell surface. This dual verification is the cornerstone of personalized cancer vaccines and T-cell therapies.
2. Agricultural Biotechnology and Crop Breeding
Modern agriculture relies heavily on molecular breeding to develop crops resistant to climate change, pests, and disease. While genomic selection models predict traits based on DNA markers, proteomic profiling provides a functional snapshot of crop stress responses. By integrating Bulked Segregant Analysis (BSA) sequencing with quantitative proteomics, breeders can pinpoint the exact proteins and metabolic pathways responsible for drought tolerance or salinity resistance, accelerating the development of high-yield, resilient cultivars.
3. Metaproteomics in Microbiome Studies
Metagenomic sequencing tells us "who is there" in a microbial community, and metatranscriptomics tells us "what they are trying to do." However, metaproteomics—the mass spectrometry-based study of all proteins expressed by a microbiome—reveals "what they are actually doing." This is particularly vital in gut microbiome research, where microbial proteins interact directly with host cells to modulate immunity, metabolism, and neurological health. Combining metagenomics (NGS) with metaproteomics provides a complete functional map of host-microbe interactions.
4. Drug Target Identification & Mechanism of Action (MoA)
For pharmaceutical developers, understanding how a small molecule or biologic interacts with the cellular proteome is vital. Mass spectrometry approaches like Thermal Proteome Profiling (TPP) or Limited Proteolysis-Mass Spectrometry (LiP-MS) allow researchers to identify drug-protein binding events across the entire proteome in living cells. When combined with transcriptomic profiling, these techniques provide a multi-layered view of drug efficacy, off-target toxicity, and cellular resistance mechanisms.
Biomarker Technologies (BMKGene) Profile
A pioneer in high-throughput sequencing and multi-omics innovation since 2009.
Biomarker Technologies (BMKGene), founded in 2009, is a leading genomics and multi-omics service provider with over 16 years of continuous innovation in high-throughput sequencing and bioinformatics. Backed by more than 60 national invention patents and 200+ software copyrights, we deliver comprehensive multi-omics solutions—spanning genomics, metagenomics, epigenetics, single-cell omics, transcriptomics, and our proprietary BMKMANU S3000 spatial transcriptome technology—supported by our advanced BMKCloud bioinformatics platform. We have established long-term collaborations with organizations across 84 regions worldwide, providing reliable genomic and proteomic solutions on a global scale.
Our integration of mass spectrometry platforms alongside cutting-edge sequencing technologies allows us to offer seamless proteogenomic workflows, helping researchers translate genomic data into concrete biological discoveries.

Our Advanced Technology Platforms
Long-Read Platforms
PacBio platforms: Sequel II, Sequel, RSII
Nanopore platforms: PromethION P48, GridION X5 MinION
Short-Read & Single-Cell
Illumina platforms: NovaSeq
BGI-sequencing: DNBSEQ-G400, DNBSEQ-T7
10X Genomics: 10X ChromiumX, Chromium Controller
Mass Spectrometry & Physical Mapping
Waters XEVO G2-XS QTOF
QTRAP 6500+
Bionano Irys system
Fully Automated NGS & Multi-Omics Platform
Unlocking industrial-scale efficiency and reproducibility with the Brilliant Lab 1000.
Brilliant Lab 1000 (BL1000)
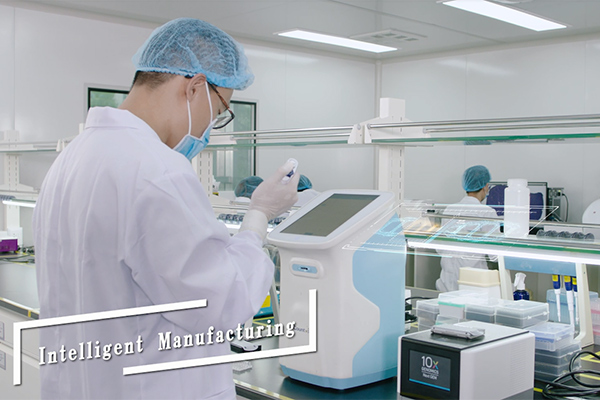
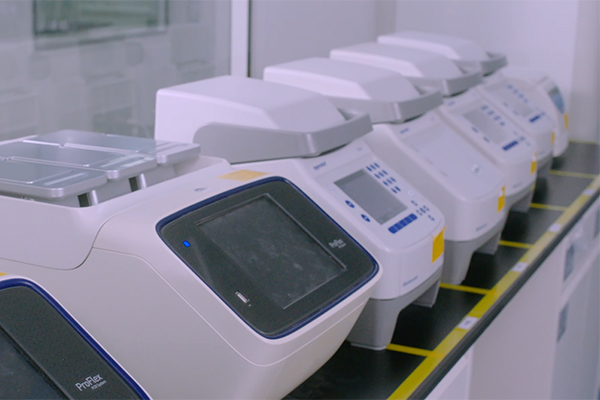
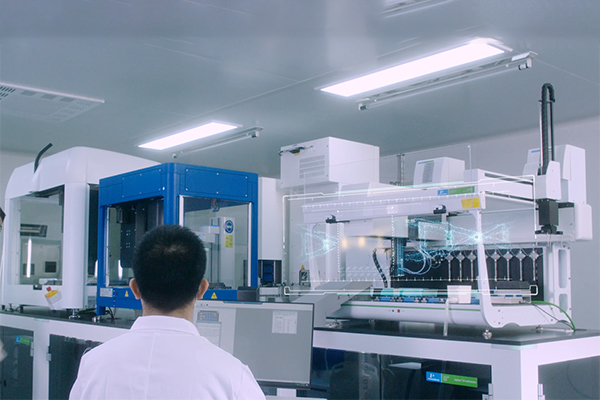
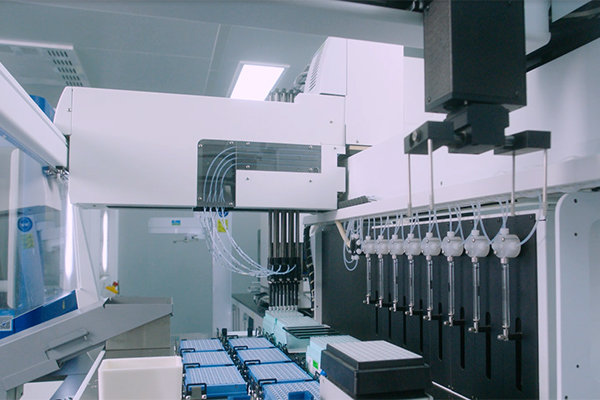
Biomarker Technologies (BMKGENE) and PerkinElmer have jointly built a fully automated experimental production line, called Brilliant Lab 1000 (BL1000), which is applied to the high-throughput NGS library construction service.
By automating labor-intensive molecular biology steps, BMKGENE strives to greatly improve the entire line of sequencing and sample preparation products in terms of product types, production line throughput, delivery quality, and cycle time, providing global customers with superior, highly standardized sequencing and multi-omics workflows.
World-Class Lab Infrastructure & Bioinformatics
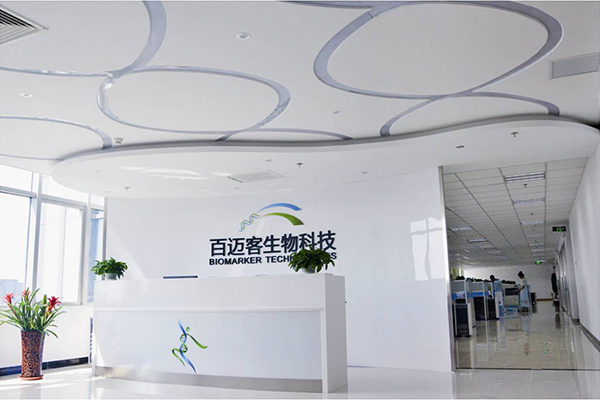
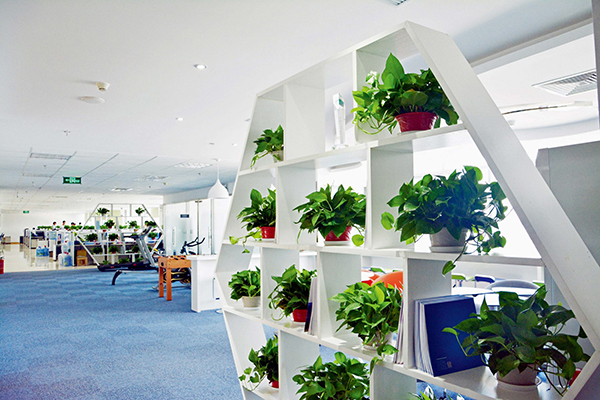
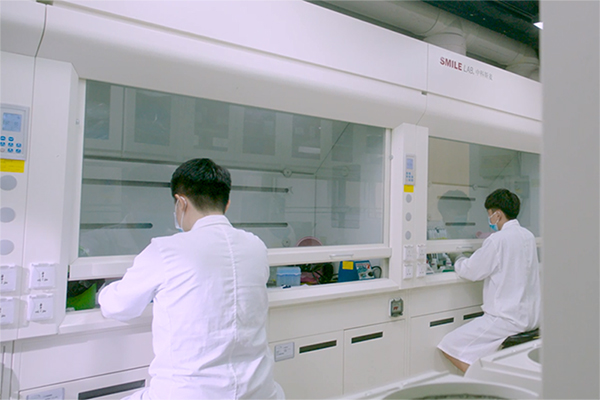
Over 20,000 Square Feet of Advanced Laboratory Space
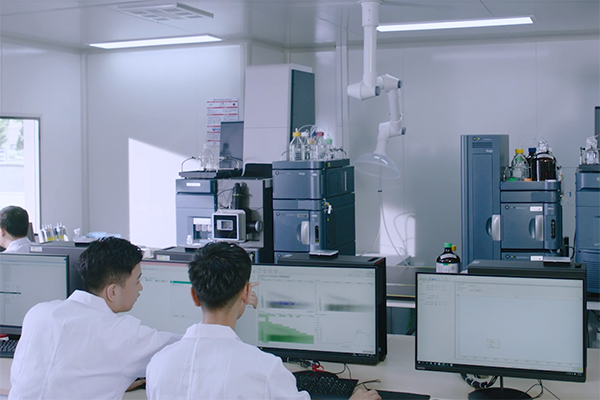
Our state-of-the-art facility houses advanced biomolecular laboratory instruments. We operate standardized laboratories for sample extraction, library construction, clean rooms, and high-throughput sequencing/mass spectrometry runs. Every stage of your project is handled under strict Standard Operating Procedures (SOPs) to ensure maximum data integrity and reproducibility.
Reliable, Easy-to-Use Online Bioinformatic Analysis Platform
To support the massive data outputs generated by modern multi-omics studies, we developed the BMKCloud platform. Powered by 4,260 computing cores and a peak computing power exceeding 121,708.8 Gflop per second, BMKCloud offers CPUs with 41,104 memory and 3 PB of total storage. This high-performance computing environment allows researchers to perform complex genomic and proteomic data integration, pathway enrichment, and statistical modeling through an intuitive web interface.


Enterprise Qualifications & Global Certifications
Our commitment to quality is backed by international standards, academic partnerships, and extensive intellectual property.


Patents & Software Copyrights
Continuous R&D investment translates to proprietary methodologies that guarantee superior service performance.


Complete Multi-Omics Product Catalog
Explore our full suite of sequencing and proteomics-related products designed to accelerate your research.
Eukaryotic mRNA-Seq & Proteomics Integration
Explore Service →
Metagenomics & Metaproteomics Co-analysis
Explore Service →
[Copy] Eukaryotic mRNA-Seq & Quantitative Proteomics
Explore Service →
Evolutionary Genetics & Comparative Proteomics
Explore Service →
Long Non-coding RNA & Regulatory Proteomics
Explore Service →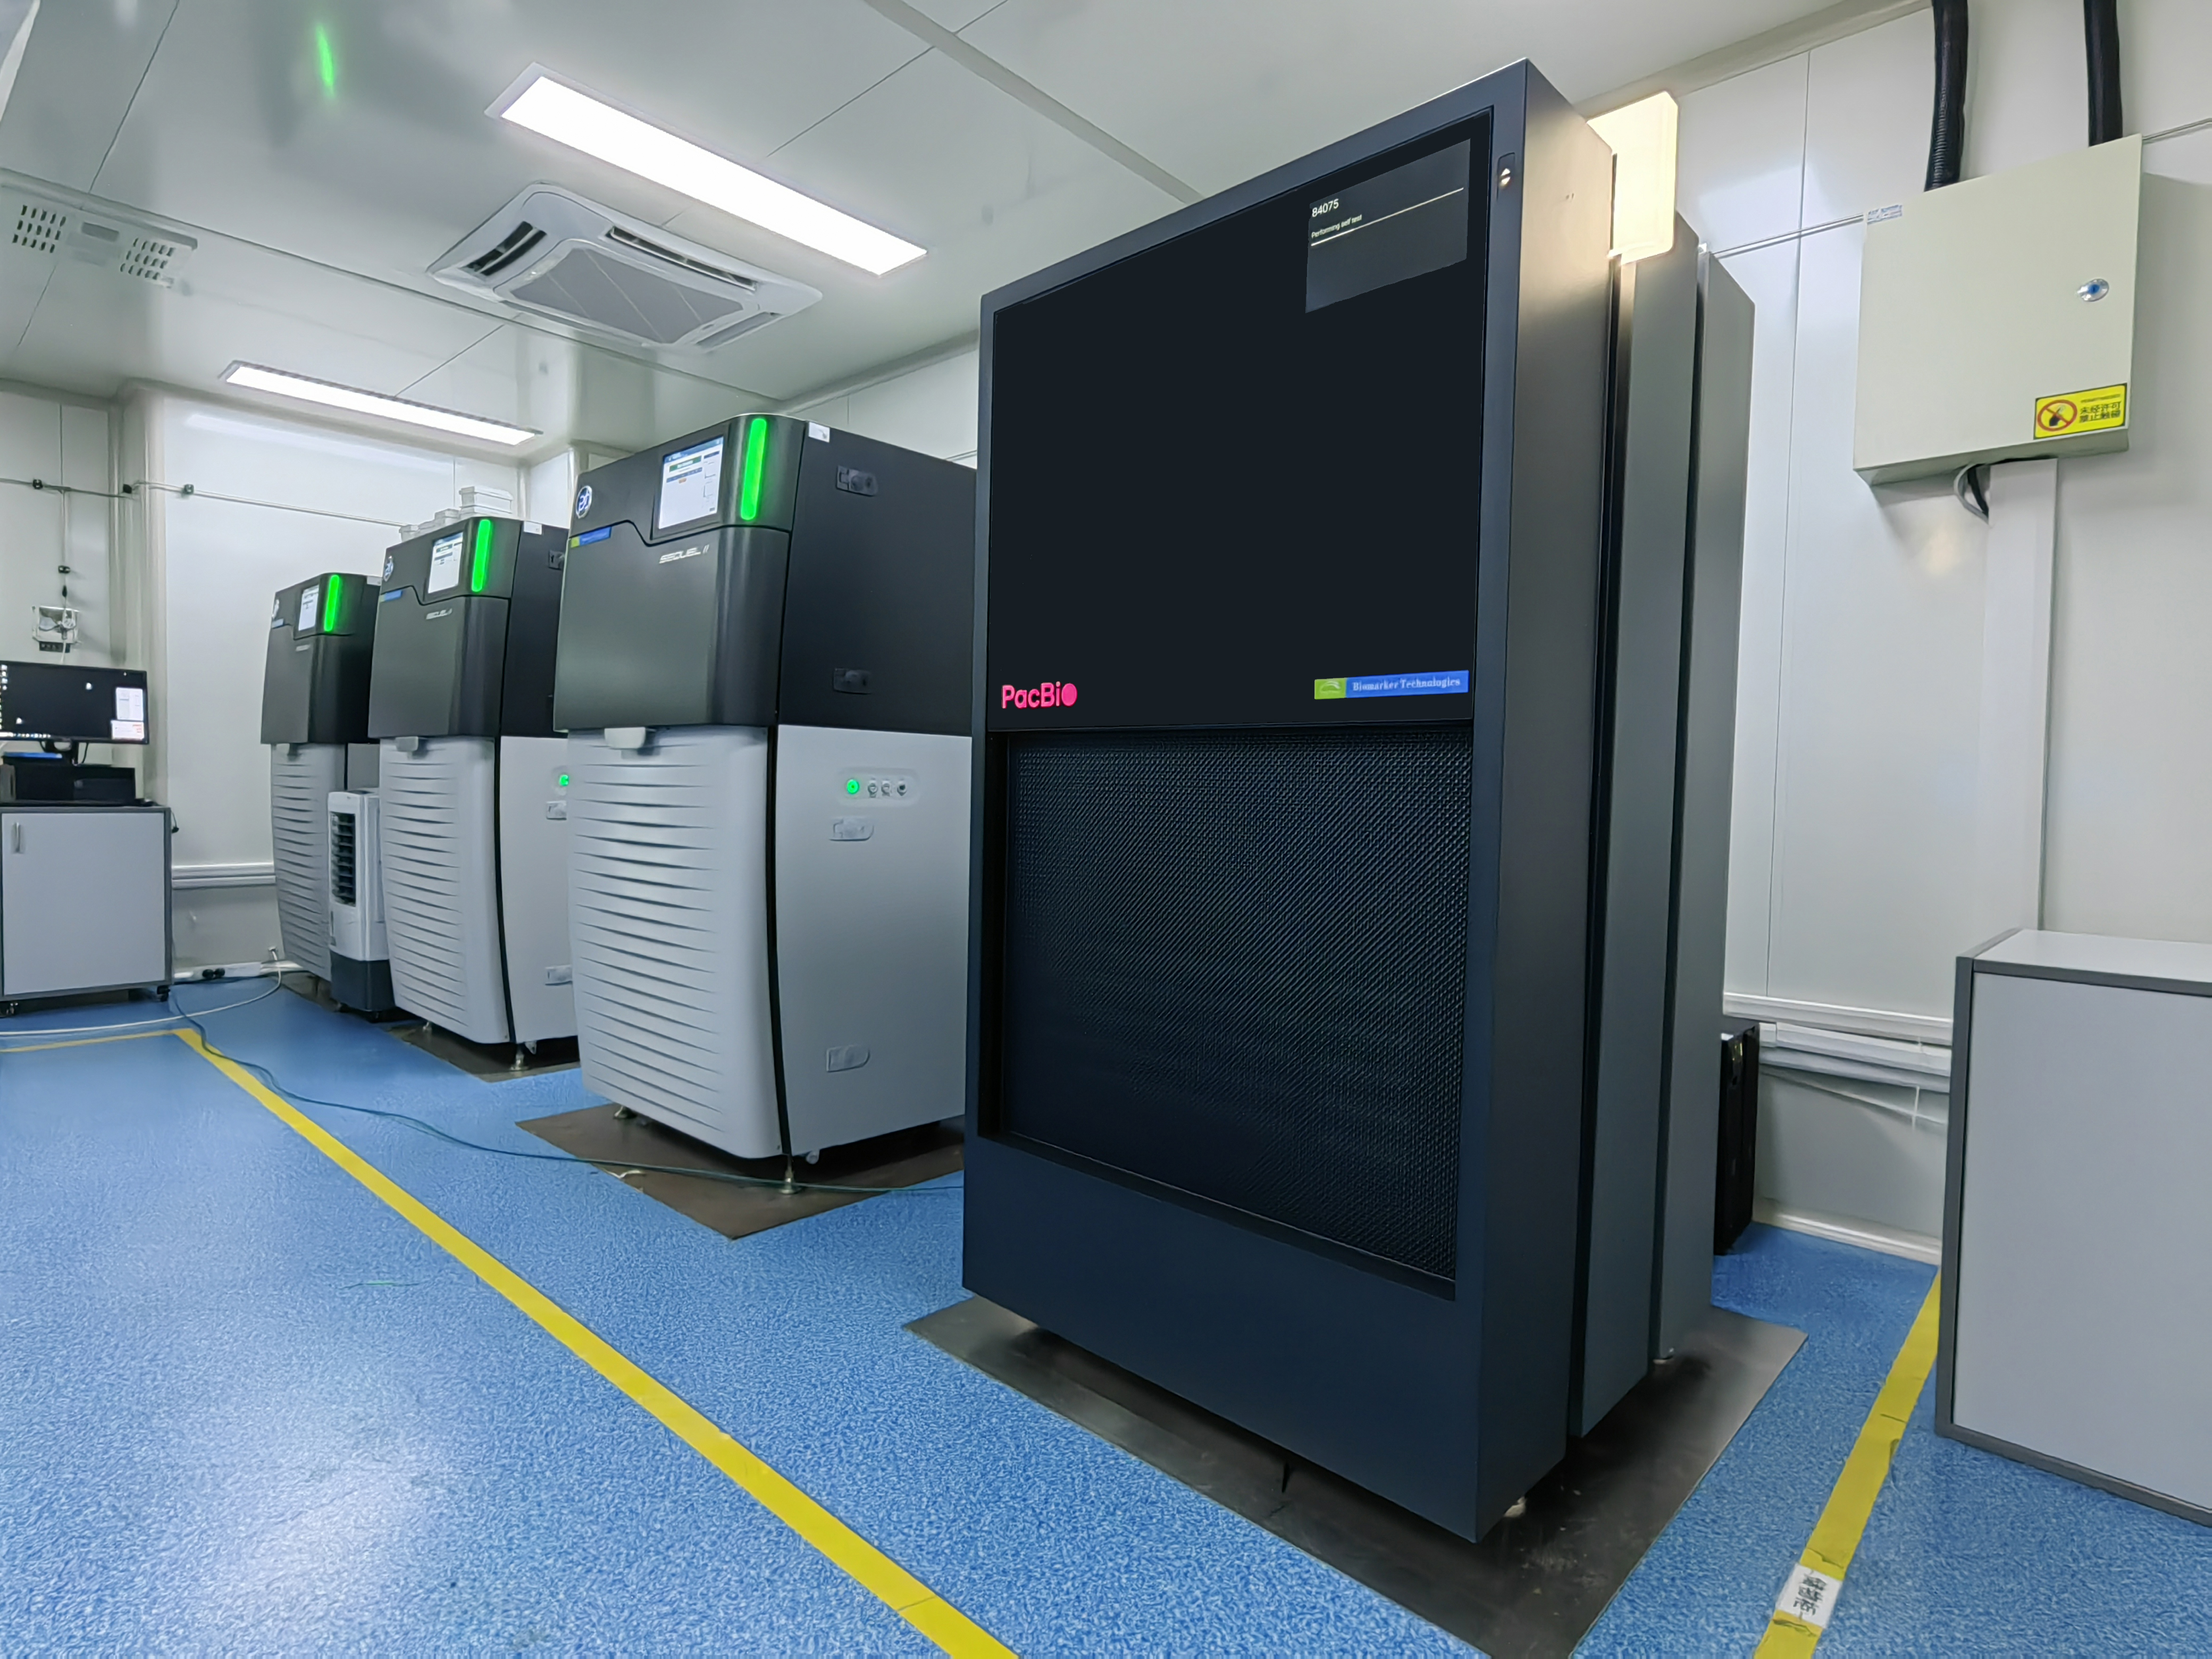
PacBio Long-Read Isoform Sequencing & Proteogenomics
Explore Service →
Whole Transcriptome & Deep Proteome Profiling
Explore Service →
BSA (Bulked Segregant Analysis) & Proteomic Trait Mapping
Explore Service →Learn more about our standards
We adhere to strict international regulations to provide top-tier scientific data.
View Enterprise Qualifications

