
Non‑Coding RNA Sequencing Companies & Products in the United States
Discover the leading platforms and customizable workflows driving transcriptomics research across North America. From small RNA validation to full-length isoform identification, our state-of-the-art sequencing services empower researchers with unmatched data resolution and bioinformatics support.
Commercial & Industrial Landscape of Non-Coding RNA in the United States
The transcriptomics and molecular biology market in the United States has seen a paradigm shift. Once considered "evolutionary junk," non-coding RNAs (ncRNAs)—including long non-coding RNAs (lncRNAs), microRNAs (miRNAs), circular RNAs (circRNAs), and piwi-interacting RNAs (piRNAs)—are now recognized as critical regulators of cellular physiology, epigenetic modification, and gene expression networks.
In major biotechnology hubs such as the San Francisco Bay Area, Boston-Cambridge, San Diego, and the Research Triangle Park in North Carolina, commercial enterprises and academic research institutes are collaborating to harness the power of ncRNA. The integration of high-throughput sequencing (HTS) platforms with advanced bioinformatics has allowed pharmaceutical firms to identify unique therapeutic targets. The US market is characterized by high demand for clinical-grade sequencing, biomarker discovery platforms, and automated workflow solutions that reduce turnaround times while maximizing data output.
Therapeutic Development
US biopharma leverages ncRNA sequencing for RNA-targeted therapeutics, antisense oligonucleotides (ASOs), and RNA interference (RNAi) drug discovery pipelines.
Liquid Biopsy & Diagnostics
Exosomal small RNAs serve as highly stable, minimally invasive biomarkers for early-stage oncology, neurodegenerative diseases, and cardiovascular monitoring.
Key Industry Trends Shaping Transcriptomics
As sequencing platforms evolve, the US scientific community is setting new benchmarks in resolution, accuracy, and biological interpretation.
Traditional bulk RNA sequencing averages cellular signals. Today, spatial transcriptomics (such as BMKMANU S3000) and single-cell platforms allow researchers to map ncRNA expression directly within tissue microenvironments, preserving crucial spatial context in oncology and developmental biology.
Platforms like PacBio and Oxford Nanopore are revolutionizing structural variant analysis. By sequencing full-length transcripts without fragmentation, researchers can accurately identify novel lncRNA isoforms, alternative splicing events, and complex fusion genes.
The volume of data generated by next-generation sequencing (NGS) requires massive computational infrastructure. Cloud platforms like BMKCloud enable researchers to perform complex multi-omics integration, secondary analysis, and data visualization in real-time.
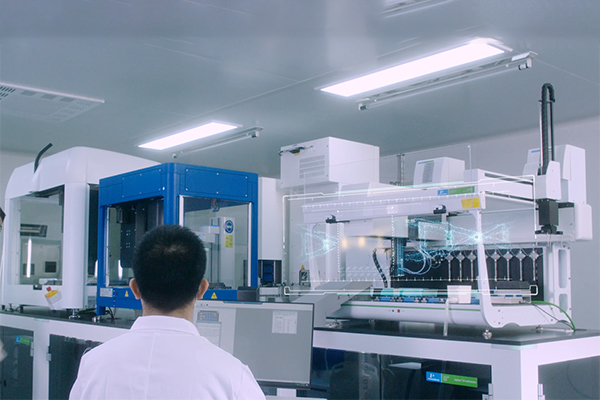
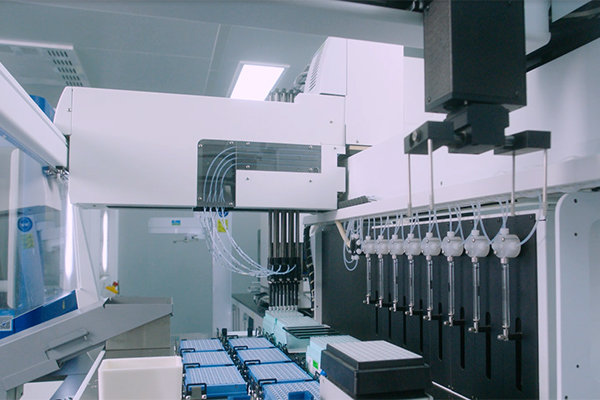
To meet the scale required by clinical trials and population-scale genomics, modern service providers are deploying automated liquid handling platforms (such as the Brilliant Lab 1000) to standardize library preparation and minimize human error.
Biomarker Technologies (BMKGene)
Biomarker Technologies (BMKGene), founded in 2009, is a leading genomics service provider with over 16 years of continuous innovation in high-throughput sequencing and bioinformatics. Backed by more than 60 national invention patents and 200+ software copyrights, we deliver comprehensive multi-omics solutions—spanning genomics, metagenomics, epigenetics, single-cell omics, transcriptomics, and our proprietary BMKMANU S3000 spatial transcriptome technology—supported by our advanced BMKCloud bioinformatics platform. We have established long-term collaborations with organizations across 84 regions worldwide, providing reliable genomic solutions on a global scale.
Our commitment to quality, speed, and analytical precision has made us a trusted partner for academic laboratories, biotechnology startups, and major agricultural research institutes in the United States and globally.
Advanced Biomolecular Laboratories
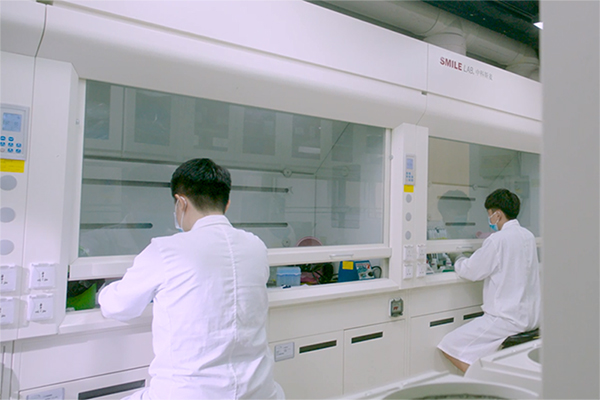
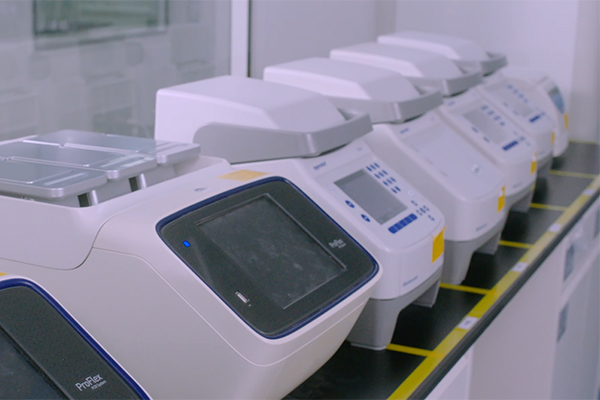
Operating over 20,000 square feet of state-of-the-art laboratory space equipped with standard sample extraction, library construction, clean rooms, and high-capacity sequencing suites under strict SOPs.
BMKCloud Bioinformatics Platform
Powered by 4,260 computing cores with peak computing power exceeding 121,708.8 Gflop per second, backed by CPUs with 41,104 memory and 3 PB total storage.
Our Sequencing & Analytical Platforms
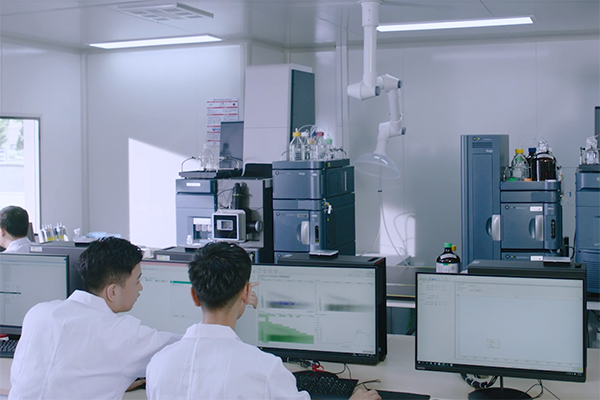
We offer access to a diverse array of industry-leading sequencing and mass spectrometry platforms to accommodate varied experimental designs and research goals.


PacBio platforms: Sequel II, Sequel, RSII
Nanopore platforms: PromethION P48, GridION X5, MinION
10X Genomics: 10X ChromiumX, 10X Chromium Controller
Illumina platforms: NovaSeq
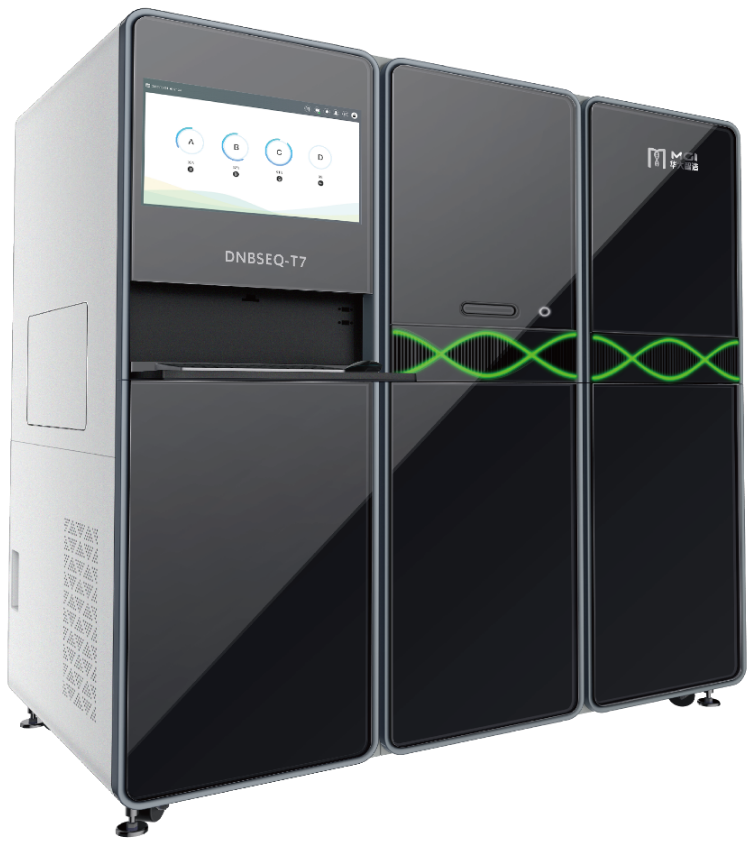
BGI-sequencing platforms: DNBSEQ-G400, DNBSEQ-T7
Bionano: Irys system
Mass Spectrometry: Waters XEVO G2-XS QTOF, QTRAP 6500+
Fully Automated NGS Library Construction
Brilliant Lab 1000 (BL1000)
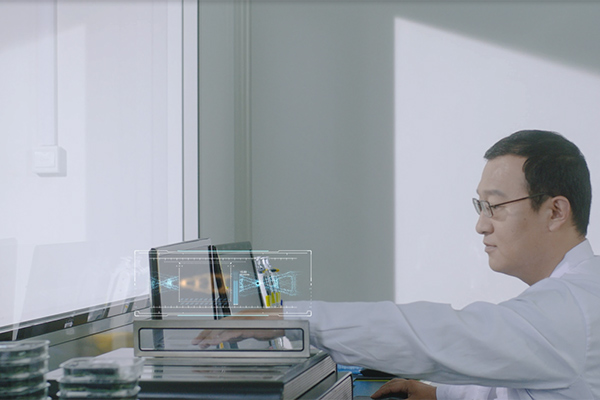
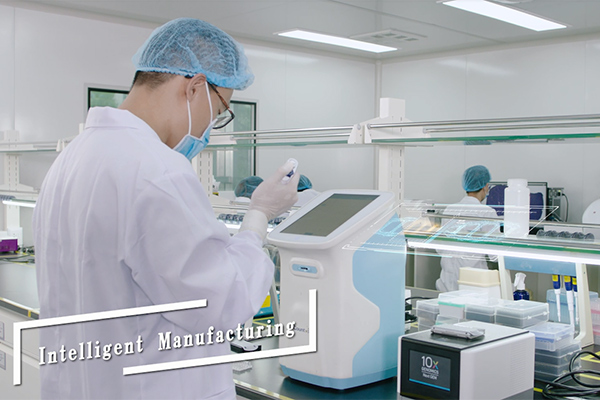
Biomarker Technologies (BMKGENE) and PerkinElmer have jointly built a fully automated experimental production line, called Brilliant Lab 1000 (BL1000), which is applied to high-throughput NGS library construction services.
By eliminating manual pipetting and human error, BMKGENE strives to greatly improve the entire line of sequencing products in terms of product types, production line throughput, delivery quality, and cycle time, to provide customers with better sequencing services.
Enterprise Qualification & Joint Laboratories
Our dedication to scientific rigor is demonstrated by our certifications, academic collaborations, and industry partnerships.


Quality Management & Patent Portfolio
Our operations conform to the highest global industrial benchmarks, backed by ISO certifications and custom bioinformatics patents.


Localized Applications of Non-Coding RNA Sequencing in the US
The practical deployment of transcriptomics services in the United States spans across clinical trials, academic investigations, and agricultural biotechnology developments. Below are the primary application scenes where BMKGene’s sequencing pipelines deliver critical biological insights.
1. Oncology & Liquid Biopsies
In oncology research clinics throughout the US, exosomal small RNAs are isolated from patient plasma or serum samples. By performing high-throughput Small RNA sequencing, researchers can profile circulating microRNAs (miRNAs) that are selectively packaged by tumor cells. This enables the discovery of diagnostic biomarkers for early cancer detection, therapy response monitoring, and minimal residual disease (MRD) tracking, bypassing the need for invasive tissue biopsies.
2. Neurological Disorder Pathogenesis
Neuroscience laboratories in major academic institutions utilize full-length transcriptomics and chromatin immunoprecipitation sequencing (ChIP-seq) to study epigenetic modifications and lncRNA regulation in brain tissue. Because long non-coding RNAs are highly tissue-specific and display complex splicing patterns in the central nervous system, long-read platforms like PacBio and Nanopore are crucial for mapping the structural isoforms implicated in Alzheimer's, Parkinson's, and autism spectrum disorders.
3. Agricultural Genomics & Crop Improvement
US agricultural biotechnology companies deploy bulked segregant analysis (BSA) and evolutionary genetics pipelines to identify agronomic traits in crops such as corn, soybeans, and cotton. By analyzing non-coding regulatory regions, researchers can identify genetic markers linked to drought tolerance, pest resistance, and yield optimization, speeding up marker-assisted selection (MAS) and molecular breeding programs.
Our Complete Transcriptomics & Genomics Products
Explore our complete portfolio of high-throughput sequencing products, library preparation solutions, and advanced bioinformatics services.
DNBSEQ pre-made libraries
Nanopore Full-length transcriptomics

Exosomal Small RNA Sequencing-Illumina

Evolutionary Genetics
GWAS

TGuide Smart Blood Genomic DNA Kit

Bulked Segregant analysis

Chromatin Immunoprecipitation Sequencing (ChIP-seq)
For inquiries about our products or pricelist, please leave your email to us.
We will be in touch within 24 hours.
Inquiry Now

