
Featured Spatial & Genomic Technologies


Understanding the Vital Role of rRNA Depletion in Spatial Transcriptomics
Spatial transcriptomics has emerged as a groundbreaking approach in modern molecular biology, enabling researchers to map the gene expression profiles of cells within their original tissue context. However, a major technical challenge in spatial transcriptomics workflows is the overwhelming presence of ribosomal RNA (rRNA). In typical eukaryotic cells, rRNA constitutes approximately 80% to 90% of total RNA. Without effective removal, these highly abundant transcripts dominate sequencing libraries, resulting in wasted sequencing reads and significantly reduced sensitivity for low-abundance transcripts, such as transcription factors, signaling molecules, and non-coding RNAs.
To overcome this bottleneck, rRNA depletion has become an indispensable preprocessing step. By selectively removing ribosomal transcripts while preserving the spatial integrity and complexity of the remaining transcriptome, researchers can unlock higher sequencing efficiency, lower experimental costs, and achieve superior spatial resolution. This is particularly crucial when dealing with challenging sample types, such as Formalin-Fixed Paraffin-Embedded (FFPE) tissues, where RNA degradation is common, and poly-A selection is often ineffective.
Why Poly-A Selection Falls Short in Spatial Biology
While poly-A capture is highly efficient for intact mRNA sequencing, it is heavily biased toward the 3' ends of transcripts. In spatial transcriptomics, especially when utilizing degraded clinical samples, poly-A selection fails to capture fragmented transcripts. rRNA depletion, conversely, targets and removes specific ribosomal sequences sequence-independently of the poly-A tail status, allowing for the comprehensive retrieval of both coding and non-coding transcripts across the entire tissue section.
Commercial and Industrial Landscape of Spatial Transcriptomics Marketing
The global market for spatial biology is experiencing an unprecedented surge, driven by the demand for precision medicine, target drug discovery, and deep oncology profiling. Biotech companies, pharmaceutical giants, and academic institutions are actively investing in spatial transcriptomics platforms. Within this competitive landscape, service providers that offer robust, automated, and high-fidelity rRNA depletion workflows hold a distinct market advantage.
From a marketing and industrial perspective, offering integrated rRNA depletion services solves a critical pain point for B2B clients: sequencing cost optimization. High-depth sequencing is expensive, and wasting 80% of reads on non-informative ribosomal sequences is commercially unviable. By highlighting advanced depletion methodologies, service providers can market their solutions as high-value, cost-effective, and highly sensitive. This positioning is essential for scaling B2B genomics operations and securing large-scale clinical trial partnerships.
Key Drivers of the Spatial Biology Market
- Clinical Research Integration: Increased utilization of spatial profiling in clinical trials to identify predictive biomarkers for immunotherapy.
- Technological Convergence: The merging of spatial transcriptomics with single-cell sequencing and proteomics to deliver multi-omic spatial maps.
- Automation and Throughput: The transition from manual library preparation to automated liquid-handling systems, such as the Brilliant Lab 1000, ensuring high reproducibility and fast turnaround times.
Deep Application Scenarios of rRNA-Depleted Spatial Transcriptomics
The application of rRNA depletion in spatial transcriptomics spans across various critical domains of biological and clinical research. By removing the background noise of ribosomal RNA, researchers can focus on the biologically relevant transcripts that drive cellular function and disease pathology.
1. Oncology & The Tumor Microenvironment (TME)
In cancer research, understanding the spatial organization of the tumor microenvironment is key to deciphering tumor progression, metastasis, and therapy resistance. rRNA-depleted spatial transcriptomics allows for the detailed mapping of immune cell infiltration, stromal interactions, and heterogeneous tumor cell states directly within clinical FFPE tumor biopsies. This level of detail is vital for developing personalized therapeutic strategies and identifying novel immune checkpoints.
2. Neuroscience and Brain Mapping
The mammalian brain is characterized by an incredibly complex spatial architecture with distinct anatomical regions and cellular layers. Traditional bulk RNA sequencing loses this spatial context, while single-cell sequencing lacks tissue coordinates. Spatial transcriptomics, optimized with advanced rRNA depletion, enables neuroscientists to profile low-abundance neurotransmitter receptors and localized synaptic transcripts across brain slices, shedding light on neurodegenerative diseases like Alzheimer's and Parkinson's.
3. Plant Biology and Crop Improvement
Unlike animal tissues, plant tissues are rich in cell walls, secondary metabolites, and chloroplasts, presenting unique challenges for RNA extraction and sequencing. Plant cells contain not only cytosolic rRNA but also mitochondrial and plastidial rRNAs. Efficient multi-organelle rRNA depletion is critical for spatial transcriptomics in plant tissues, enabling the study of developmental biology, pathogen resistance, and environmental adaptation at a spatial level.
Future Trends in Spatial Transcriptomics and Bioinformatics
As the spatial transcriptomics field matures, several technological and bioinformatics trends are shaping its future. The integration of long-read sequencing technologies, such as Nanopore and PacBio, with spatial resolution is poised to revolutionize isoform-level transcript mapping. Furthermore, the role of cloud-based bioinformatics platforms is becoming increasingly central to handling the massive datasets generated by spatial sequencing runs.
BMKGene is at the forefront of these trends, leveraging its proprietary BMKMANU S3000 spatial transcriptome technology and the BMKCloud bioinformatics platform. By combining high-density spatial capture arrays with automated library preparation and advanced cloud computing, BMKGene provides researchers with an end-to-end workflow that guarantees high-resolution data, quick turnaround times, and robust biological insights.
Biomarker Technologies (BMKGene)
Biomarker Technologies (BMKGene), founded in 2009, is a leading genomics service provider with over 16 years of continuous innovation in high-throughput sequencing and bioinformatics. Backed by more than 60 national invention patents and 200+ software copyrights, we deliver comprehensive multi-omics solutions—spanning genomics, metagenomics, epigenetics, single-cell omics, transcriptomics, and our proprietary BMKMANU S3000 spatial transcriptome technology—supported by our advanced BMKCloud bioinformatics platform. We have established long-term collaborations with organizations across 84 regions worldwide, providing reliable genomic solutions on a global scale.

Our Platforms
PacBio platforms: Sequel II, Sequel, RSII
Nanopore platforms: PromethION P48, GridION X5 MinION
10X Genomics: 10X ChromiumX, 10X Chromium Controller
Illumina platforms: NovaSeq
BGI-sequencing platforms: DNBSEQ-G400, DNBSEQ-T7
Bionano Irys system
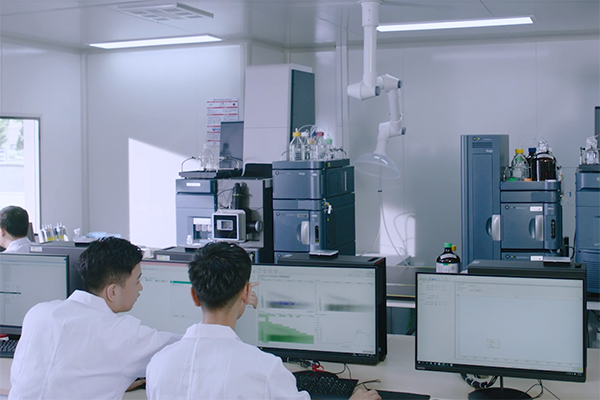
Waters XEVO G2-XS QTOF
QTRAP 6500+

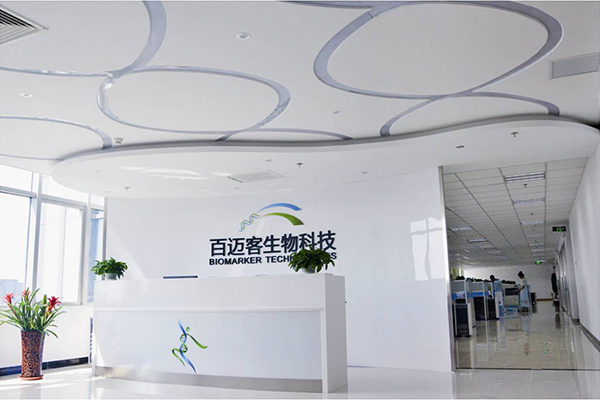
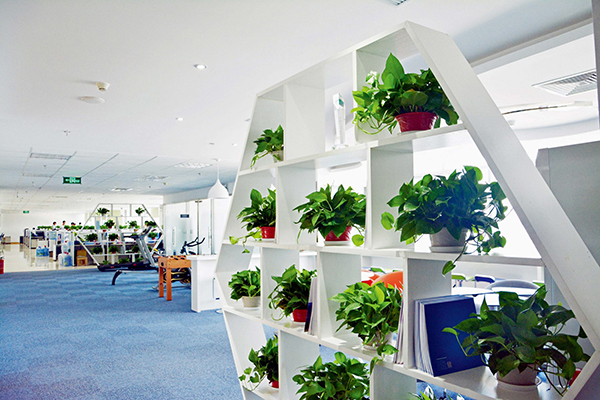
Over 20,000 Square Feet Facility
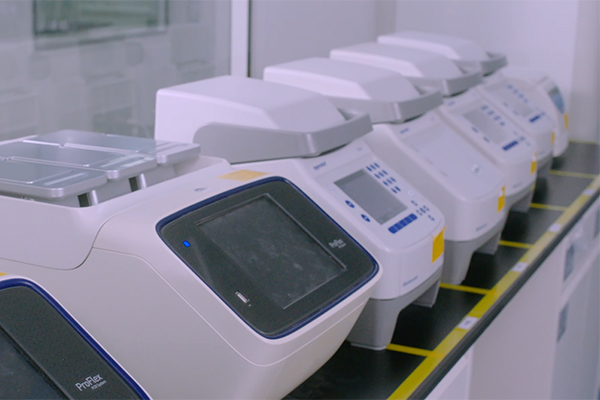
Advanced biomolecular laboratory instruments
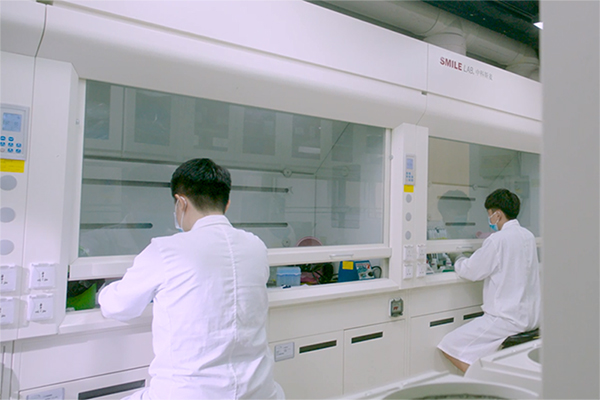
Standard labs of sample extraction, library construction, clean rooms, sequencing labs
Standard procedures from sample extraction to sequencing under strict SOPs

Reliable, Easy-to-use On-line Bioinformatic Analysis Platform
Self-developed BMKCloud platform
CPUs with 41,104 memory and 3 PB total storage
4,260 computing cores with peak computing power over 121,708.8 Gflop per second.
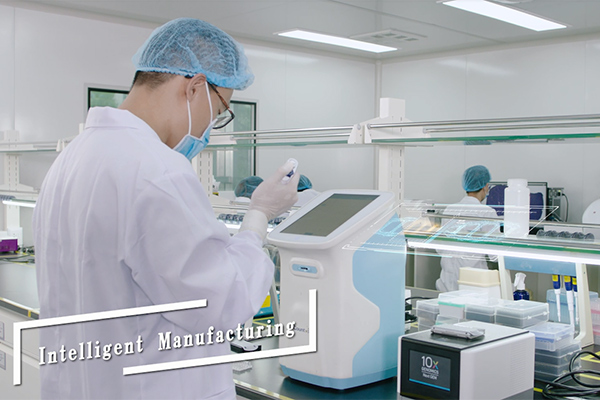
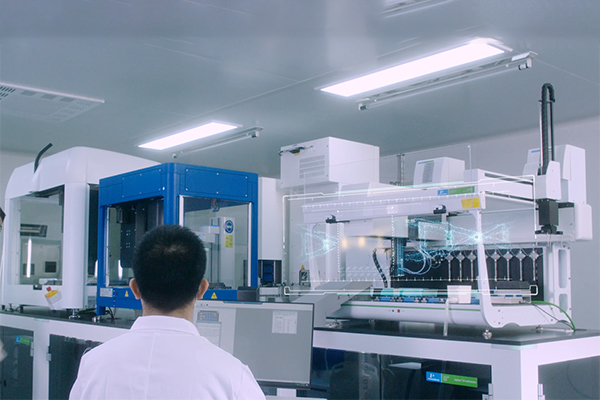
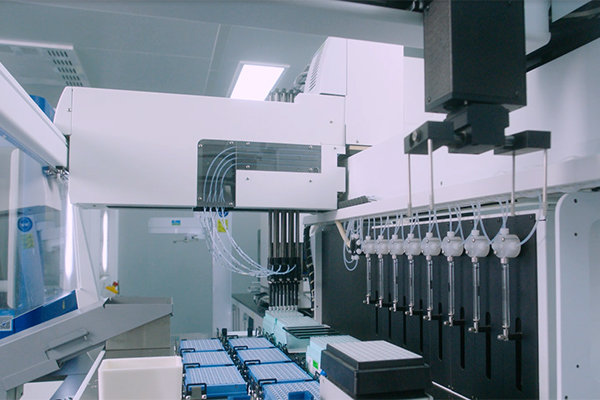
Fully Automated Platform for Next-generation sequencing--Brilliant Lab 1000
Biomarker technologies (BMKGENE) and PerkinElmer have jointly built a fully automated experimental production line, called Brilliant Lab 1000 (BL1000), which is applied to the high-throughput NGS library construction service.
BMKGENE strives to greatly improve the entire line of sequencing products in terms of product types, production line throughput, delivery quality, and cycle time, to provide customers with better sequencing services.
Enterprise Qualification & Patents


