
Featured T2T Scaffolding Solutions
Harness the power of complete chromosome reconstruction to drive high-impact genomic research and content generation.

T2T-Guided Eukaryotic Transcriptome & mRNA Sequencing
Align RNA transcripts to complete, gap-free reference genomes for absolute quantification and novel isoform discovery.

T2T Evolutionary Genetics & Comparative Genomics
Trace evolutionary trajectories, chromosomal rearrangements, and speciation events with gapless alignment maps.

T2T Plant & Animal De Novo Genome Sequencing
Assemble complex plant and animal genomes from telomere to telomere, revealing highly repetitive regions and centromeres.

Hi-C Chromatin Interaction for T2T Scaffold Assembly
Utilize spatial chromatin contact mapping to scaffold contigs into complete, chromosome-level, gap-free structures.
The Dawn of the T2T Genomics Era: Breaking the Barriers of Genetic Gaps
For decades, the global scientific community accepted a compromised reality: reference genomes were incomplete. Traditional Next-Generation Sequencing (NGS) and early long-read technologies struggled to bridge the highly repetitive regions of genomes, leaving substantial "gaps." These unsequenced segments, primarily located at centromeres, telomeres, and within segment duplications, were often dismissed as genomic "dark matter." However, the emergence of Telomere-to-Telomere (T2T) Gap-Free Chromosome Assembly has revolutionized this paradigm, allowing researchers to build the complete, contiguous blueprint of life from start to finish.
By resolving repetitive structures and complex structural variations, T2T assembly serves as the ultimate benchmark for genome sequencing, providing the foundation for unprecedented discoveries in functional genomics, evolutionary biology, and agricultural biotechnology.
Industrial Landscape & Commercial Growth of Gap-Free Genomics
The genomics industry is currently transitioning from draft-quality genomes to gold-standard T2T assemblies. Historically, draft genomes served as functional maps, but they frequently missed key regulatory components, structural variants, and gene copies hidden within repetitive regions. Today, commercial sectors—ranging from agricultural seed developers to precision medicine firms—demand gap-free chromosome assemblies to ensure the absolute accuracy of their downstream applications.
Industrially, this transition is driven by the rapid cost reduction of long-read sequencing platforms (such as PacBio HiFi and Oxford Nanopore Ultra-Long) alongside advanced chromatin conformation capture technologies like Hi-C. The commercial value of T2T assembly lies in its ability to eliminate false positives in variant calling, accurately profile gene copy number variations (CNVs), and map previously inaccessible regions of the genome. In agricultural biotechnology, for example, identifying the complete sequence of complex polyploid crops allows for precise gene editing (CRISPR-Cas9) targeting disease resistance and yield enhancement, reducing product development cycles by years.
Complete sequencing from telomere to telomere, ensuring no missing elements in critical functional regions.
Unparalleled resolution of structural variants, transposable elements, and segment duplications.
Direct detection of DNA methylation patterns across centromeric and telomeric regions without PCR bias.
Deep Dive: High-Impact Application Scenarios of T2T Assembly
1. Plant and Animal Breeding and Agritech
Agricultural genomics deals with some of the most complex, highly repetitive, and polyploid genomes in existence (e.g., wheat, sugarcane, and various timber species). T2T assembly enables breeders to construct haplotype-resolved genomes. This means researchers can distinguish between maternal and paternal chromosomes, mapping the precise location of quantitative trait loci (QTLs) linked to drought tolerance, pest resistance, and nutritional value. By assembling gap-free chromosomes, breeders can leverage genomic selection with absolute confidence, paving the way for the next green revolution.
2. Evolutionary Genetics and Speciation Research
Evolutionary biologists study the structural changes that occur over millennia. Gaps in genomes obscure structural rearrangements, such as inversions and translocations, which are primary drivers of speciation and adaptation. T2T genomes provide an unblemished window into chromosomal evolution, allowing scientists to compare precise centromeric shifts and telomeric sequence dynamics across related species. This depth of information is crucial for understanding how organisms adapt to rapid environmental changes.
3. Human Pathogen Genomics and Epigenomics
In medical research, T2T assembly unlocks the "dark genome"—regions containing disease-susceptibility genes that were previously impossible to map accurately. This includes highly homologous gene families involved in immune response and neurological development. Furthermore, combining T2T assemblies with long-read sequencing allows for the simultaneous profiling of genetic sequences and epigenetic modifications (like 5mC methylation). This dual-layer mapping is critical for understanding oncogenesis, where epigenetic silencing of tumor suppressor genes often occurs in highly repetitive genomic landscapes.
Future Trends: Pangenomics and AI-Driven Assembly
The future of genomics lies in the creation of T2T pangenomes. Rather than relying on a single reference genome, pangenomics captures the entire genetic diversity of a species by combining multiple T2T-level assemblies. This approach is becoming the standard for crop species and human population genetics. Concurrently, machine learning algorithms and AI-driven bioinformatics pipelines are rapidly accelerating the assembly process, reducing the time required to resolve complex repetitive loops and lowering computational costs. As these technologies mature, T2T gap-free assembly will transition from a premium research service to a routine baseline for all sequencing projects.
About Biomarker Technologies (BMKGene)
A trusted global leader in genomics services, delivering cutting-edge multi-omics solutions for over 16 years.
Biomarker Technologies (BMKGene), founded in 2009, is a leading genomics service provider with over 16 years of continuous innovation in high-throughput sequencing and bioinformatics. Backed by more than 60 national invention patents and 200+ software copyrights, we deliver comprehensive multi-omics solutions—spanning genomics, metagenomics, epigenetics, single-cell omics, transcriptomics, and our proprietary BMKMANU S3000 spatial transcriptome technology—supported by our advanced BMKCloud bioinformatics platform. We have established long-term collaborations with organizations across 84 regions worldwide, providing reliable genomic solutions on a global scale.
Our Leading Multi-level High-throughput Sequencing Platforms

Long-Read & Single-Cell Platforms
PacBio platforms: Sequel II, Sequel, RSII
Nanopore platforms: PromethION P48, GridION X5, MinION
10X Genomics: 10X ChromiumX, 10X Chromium Controller

Short-Read & Specialized Systems
Illumina platforms: NovaSeq
BGI-sequencing platforms: DNBSEQ-G400, DNBSEQ-T7
Optical Mapping: Bionano Irys system
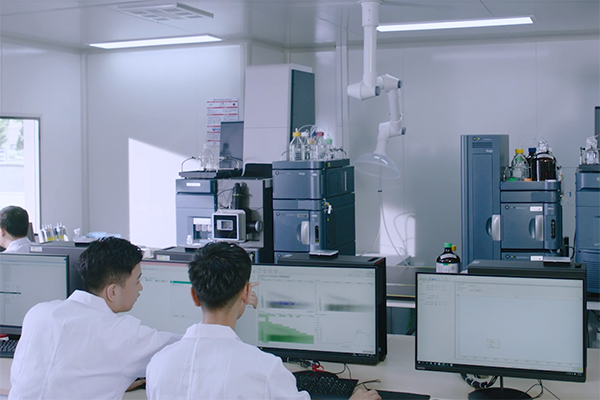
Mass Spectrometry: Waters XEVO G2-XS QTOF, QTRAP 6500+

Advanced Bioinformatics & Facilities
Facility: Over 20,000 square feet advanced laboratory space with strict SOPs from extraction to sequencing.
BMKCloud: Self-developed platform with 4,260 computing cores, 41,104 memory, 3 PB storage, and peak power over 121,708.8 Gflop/s.
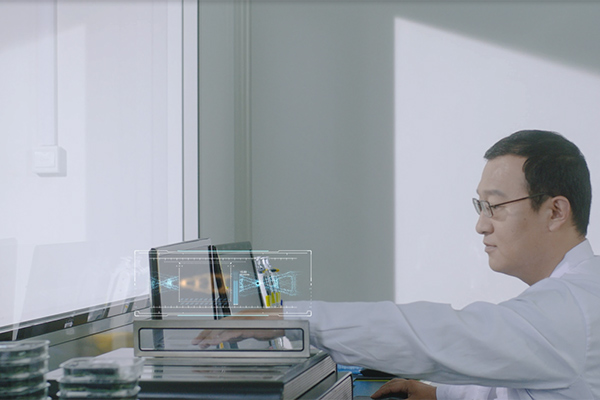
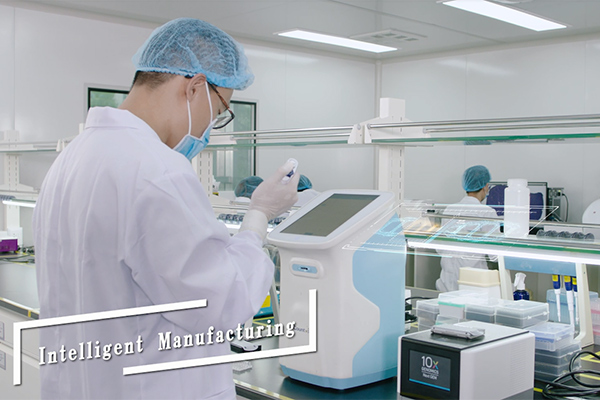
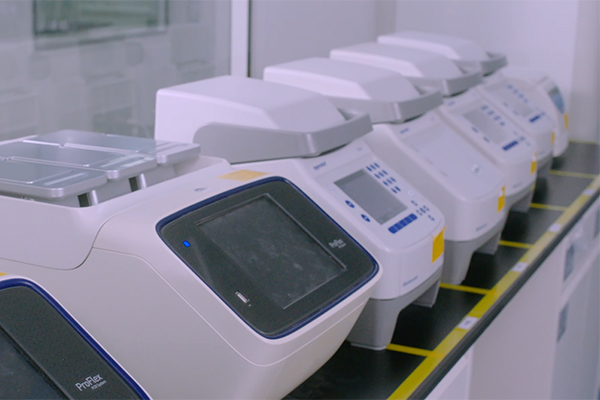
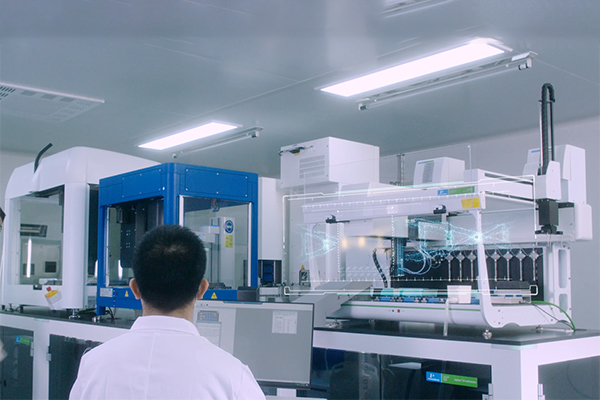
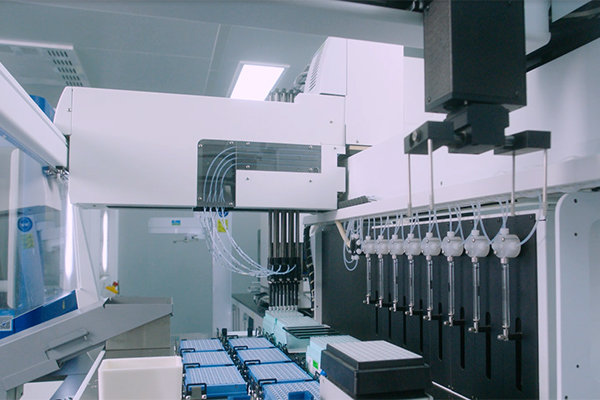
Fully Automated Platform for Next-generation sequencing--Brilliant Lab 1000
Biomarker technologies (BMKGENE) and PerkinElmer have jointly built a fully automated experimental production line, called Brilliant Lab 1000 (BL1000), which is applied to the high-throughput NGS library construction service.
BMKGENE strives to greatly improve the entire line of sequencing products in terms of product types, production line throughput, delivery quality, and cycle time, to provide customers with better sequencing services.
Enterprise Qualifications & Patents
Our commitment to quality, innovation, and scientific excellence is backed by global certifications and extensive intellectual property.


Complete Genomics Product Portfolio
Explore our full suite of sequencing and analysis services, optimized for complete chromosome-level research.
T2T-Guided Eukaryotic Transcriptome & mRNA Sequencing
Align RNA transcripts to complete, gap-free reference genomes for absolute quantification and novel isoform discovery.
T2T Evolutionary Genetics & Comparative Genomics
Trace evolutionary trajectories, chromosomal rearrangements, and speciation events with gapless alignment maps.

Exosomal RNA Profiling via T2T Reference Mapping
Characterize exosomal mRNA, LncRNA, and CircRNA dynamics with high-resolution reference alignments.

Single-Nuclei RNA Sequencing for T2T Tissue Atlases
Uncover cellular heterogeneity in challenging tissues by mapping single-nuclei transcripts to gap-free assemblies.
Hi-C Chromatin Interaction for T2T Scaffold Assembly
Utilize spatial chromatin contact mapping to scaffold contigs into complete, chromosome-level, gap-free structures.
T2T Plant & Animal De Novo Genome Sequencing
Assemble complex plant and animal genomes from telomere to telomere, revealing highly repetitive regions and centromeres.
PacBio Iso-Seq Full-Length Transcriptome for T2T Validation
Analyze direct, full-length transcripts without assembly, ideal for validating novel genes in T2T regions.

TGuide Smart DNA Kit for Metagenomic T2T Scaffolding
High-yield DNA extraction optimized for long-read sequencing, ensuring high molecular weight DNA for T2T pipelines.


