1. The Rise of T2T Gap-Free Chromosome Assembly in Modern Science
For decades, genomics has operated under the constraints of "draft" reference genomes. While early sequencing technologies provided the scaffolding of life, they left substantial gaps in highly repetitive, heterochromatic regions, telomeres, and centromeres. The advent of Telomere-to-Telomere (T2T) gap-free chromosome assembly has shattered these barriers. Utilizing a combination of ultra-long sequencing reads (such as Oxford Nanopore) and highly accurate long reads (PacBio HiFi), T2T assembly resolves every single base pair across entire chromosomes from end to end.
This complete blueprint is not just a triumph for genomics; it represents a paradigm shift for downstream functional omics. By eliminating assembly gaps, researchers can now access previously hidden genomic regions that encode novel proteins, structural variations, and complex regulatory networks. T2T assembly provides the absolute foundation required to accurately map the proteomic and metabolomic landscape of any organism.
SEO Insight: Integrating T2T gap-free assemblies with proteomics and metabolomics represents the cutting edge of systems biology. Without a complete reference genome, mass spectrometry data for novel isoforms and specialized metabolites often remains unmappable, creating a "dark proteome" and "dark metabolome" that limits scientific discovery.
2. Bridging Genomics to Proteomics: Unmasking the Dark Proteome
Proteomics relies heavily on reference databases to match mass spectrometry (MS/MS) spectra to known peptide sequences. If a gene is located within a genomic gap or is poorly assembled, its corresponding protein will be absent from the reference database. Consequently, mass spectrometers will detect these proteins, but bioinformatic pipelines will fail to identify them, classifying them as uninterpretable noise.
Complete ORF Discovery
T2T genomes uncover full open reading frames (ORFs) within previously inaccessible repeat regions, allowing the identification of novel, tissue-specific, or disease-associated proteins.
Isoform Resolution
Combining T2T genomics with long-read transcriptomics (such as PacBio Iso-Seq) allows precise mapping of alternative splicing events, ensuring every protein isoform is represented.
Structural Variant Translation
Structural variants (SVs) resolved by T2T genomes often translate into altered protein structures, crucial for understanding phenotypic variation and disease mechanisms.
By providing a gap-free reference, T2T assembly ensures that the customized protein databases used in proteogenomics are exhaustive. This is particularly vital in cancer research, where chromosomal rearrangements and novel fusion proteins frequently occur in repetitive regions that traditional sequencing technologies fail to resolve.
3. Unlocking the Dark Metabolome: Linking Genes to Specialized Metabolites
Metabolomics profiles the small molecules that drive biological processes. Unlike proteins, metabolites are synthesized by complex networks of enzymes. The genes encoding these enzymes are often clustered together in the genome as Biosynthetic Gene Clusters (BGCs). In plants, fungi, and microbes, BGCs are frequently located in highly repetitive, subtelomeric, or heterochromatic regions.
Without T2T gap-free assembly, these gene clusters are often fragmented across different contigs, making it impossible to reconstruct the complete biosynthetic pathway. T2T genomes resolve these clusters intact, allowing researchers to:
- Accurately annotate biosynthetic enzymes and regulatory elements within BGCs.
- Correlate genomic variations directly with metabolite abundance profiles.
- Predict novel secondary metabolites in medicinal plants and industrial microbes.
- Understand the evolutionary mechanisms of metabolic diversity across species.
This integration of T2T genomics and metabolomics is accelerating the discovery of novel biofuels, biopesticides, and pharmaceuticals, transforming the landscape of industrial biotechnology.
4. Industrial and Commercial Applications of T2T-Enabled Multi-Omics
The synergy of T2T assembly, proteomics, and metabolomics is driving innovation across several key industries:
A. Agriculture and Crop Breeding
Modern agriculture faces the challenge of climate change. Developing climate-resilient crops requires a deep understanding of stress-response pathways. T2T genomes of complex polyploid crops allow researchers to map the entire proteomic and metabolomic response to drought, salinity, and pests. This facilitates marker-assisted selection and gene-editing strategies to breed high-yield, resilient crop varieties.
B. Pharmaceutical Discovery and Precision Medicine
In drug discovery, identifying the exact targets of bioactive molecules is critical. By combining T2T reference genomes with spatial proteomics and untargeted metabolomics, pharmaceutical companies can profile drug-target interactions with cell-type specificity. This reduces off-target effects and accelerates clinical trial timelines.
C. Synthetic Biology and Metabolic Engineering
Synthetic biologists design microbes to produce high-value chemicals. A gap-free genome provides the exact blueprint of the host organism's metabolic network. By integrating proteomic flux data with T2T metabolic reconstructions, researchers can identify bottleneck enzymes and engineer pathways for optimal yield and efficiency.
About Biomarker Technologies (BMKGene)
Biomarker Technologies (BMKGene), founded in 2009, is a leading genomics service provider with over 16 years of continuous innovation in high-throughput sequencing and bioinformatics. Backed by more than 60 national invention patents and 200+ software copyrights, we deliver comprehensive multi-omics solutions—spanning genomics, metagenomics, epigenetics, single-cell omics, transcriptomics, and our proprietary BMKMANU S3000 spatial transcriptome technology—supported by our advanced BMKCloud bioinformatics platform. We have established long-term collaborations with organizations across 84 regions worldwide, providing reliable genomic solutions on a global scale.
Our Leading Multi-level High-throughput Sequencing Platforms

Sequencing Platforms
PacBio platforms: Sequel II, Sequel, RSII
Nanopore platforms: PromethION P48, GridION X5, MinION
10X Genomics: 10X ChromiumX, 10X Chromium Controller
Illumina platforms: NovaSeq
BGI-sequencing platforms: DNBSEQ-G400, DNBSEQ-T7
Bionano Irys system

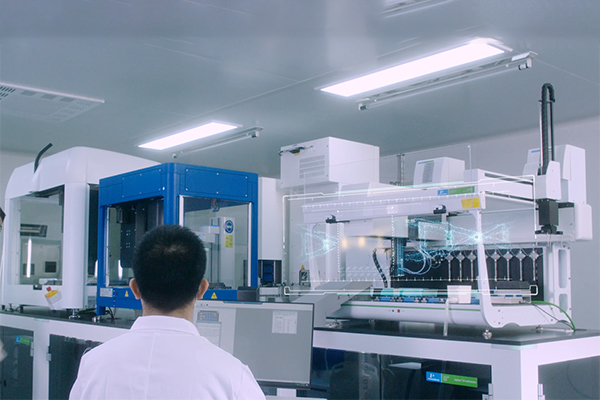
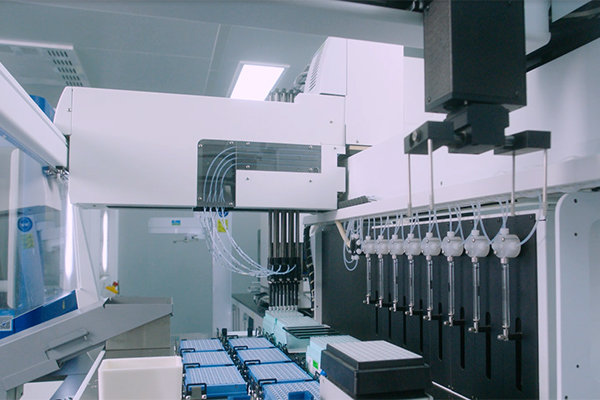
Automatic Laboratories
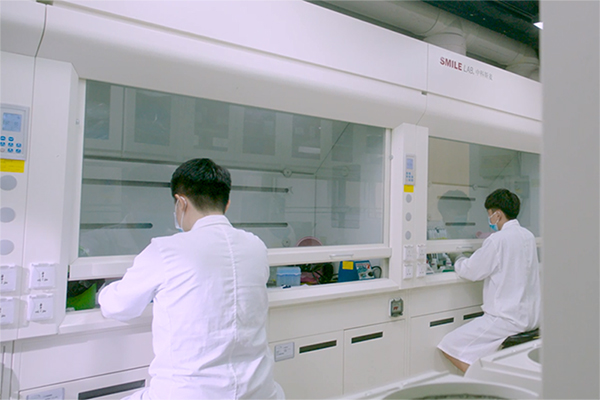
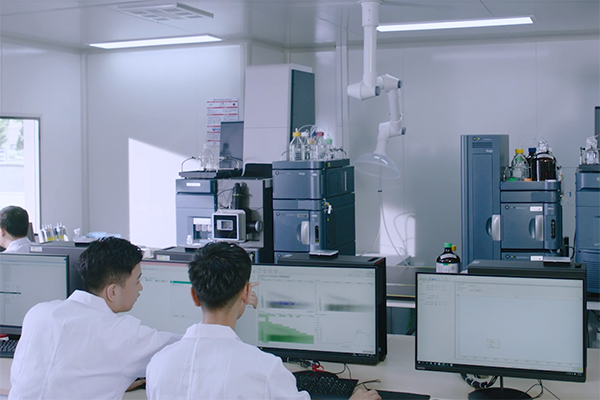
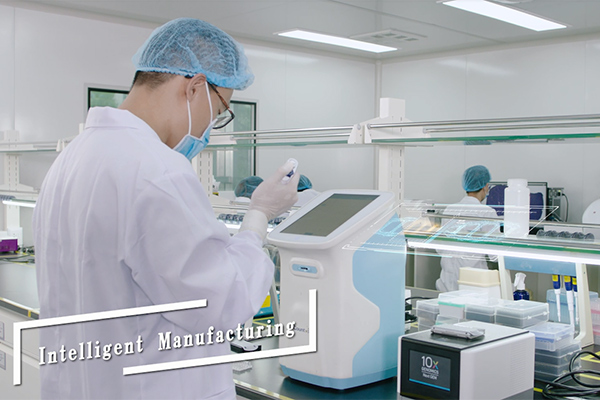
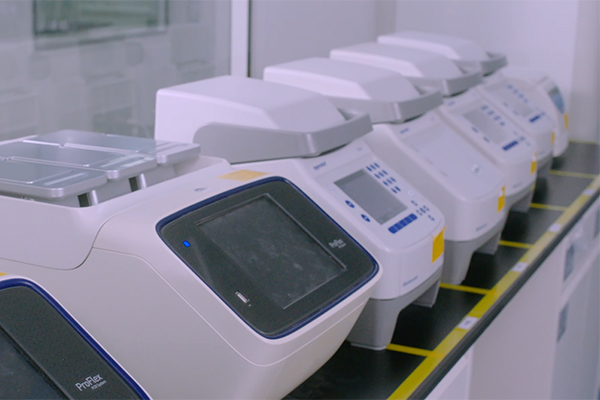
Over 20,000 square feet facility equipped with advanced biomolecular laboratory instruments. Standardized laboratories for sample extraction, library construction, clean rooms, and sequencing operations, running under strict SOPs.

Bioinformatic Cloud
Our self-developed BMKCloud platform features CPUs with 41,104 memory, 3 PB total storage, and 4,260 computing cores, delivering a peak computing power exceeding 121,708.8 Gflop per second.
Fully Automated Platform for Next-Generation Sequencing
Brilliant Lab 1000 (BL1000)
Biomarker Technologies (BMKGENE) and PerkinElmer have jointly built a fully automated experimental production line, called Brilliant Lab 1000 (BL1000), which is applied to high-throughput NGS library construction services.
BMKGENE strives to greatly improve the entire line of sequencing products in terms of product types, production line throughput, delivery quality, and cycle time, to provide customers with industry-leading sequencing services.
Our Advanced Manufacturing Facility
Enterprise Qualifications & Patents
BMKGene maintains the highest industry standards with rigorous quality systems, certified laboratories, and proprietary intellectual property.


Request a Custom Quote or Consult with Our Experts
For inquiries about our T2T assembly services, multi-omics integration pipelines, or pricing, get in touch with us. We will contact you within 24 hours.
Inquiry NowOur Comprehensive Product Portfolio
PacBio-Full-length Transcriptome (Non-Reference)

Plant/Animal Whole Genome Sequencing

TGuide Smart Magnetic Tissue DNA Kit

Assay for Transposase-Accessible Chromatin (ATAC-seq)
circ-RNA Sequencing & Analysis

Mass Spectrometry Metabolomics

TGuide Smart Soil / Stool DNA Kit