
Featured Genomic & Proteomic Solutions
Explore our core high-throughput sequencing technologies tailored for comprehensive biological insights.


Deep Dive: Whole Exome Sequencing (WES) in modern Genomics
Analyzing market trends, commercial landscapes, and how robust genomic data fuels academic and medical content creation.
🧬1. The Paradigm of Genome Sequencing Content Creation
In the contemporary era of biotechnology and digital healthcare, "Genome Sequencing Content Creation" refers to the systematic generation, translation, and dissemination of genomic data into actionable biological knowledge. This encompasses the development of clinical diagnostic reports, scientific literature, mutation databases, and educational assets. At the core of this content engine lies Whole Exome Sequencing (WES).
While Whole Genome Sequencing (WGS) deciphers all 3 billion base pairs of the human genome, WES selectively targets the exome—the protein-coding regions that represent approximately 1% to 2% of the genome but harbor over 85% of known disease-causing mutations. By focusing sequencing power on these critical regions, WES provides an optimal balance of high coverage depth, cost efficiency, and clinical interpretability, making it the most practical data source for high-quality genomic content creation.
📊2. Commercial & Industrial Status of WES
The global market for Whole Exome Sequencing is experiencing rapid expansion, driven by the declining cost of next-generation sequencing (NGS), growing adoption of personalized medicine, and rising prevalence of genetic disorders. Currently, the biotechnology industry utilizes WES for a multitude of commercial applications:
- Clinical Diagnostics: WES is the gold standard for identifying the genetic etiology of rare and undiagnosed diseases, significantly shortening the diagnostic odyssey for patients.
- Precision Oncology: Commercial laboratories leverage exome sequencing of tumor-normal pairs to detect somatic mutations, copy number variations (CNVs), and mutational signatures, enabling oncologists to prescribe targeted therapies.
- Pharmaceutical R&D: Drug developers utilize large-scale exome data to identify novel therapeutic targets, validate biomarkers, and stratify patients for clinical trials, reducing drug development timelines and failure rates.
The industrialization of WES requires massive automation. Modern genomic service providers are shifting from manual sample preparation to fully automated molecular biology workflows. This reduces human error, increases throughput, and ensures highly reproducible sequencing libraries, which are essential for generating standardized data for downstream content creation.
🚀3. Developmental Trends in Exome Sequencing
As sequencing technologies mature, several key trends are shaping the future of WES and genome sequencing content creation:
A. Transition to Long-Read Exome Capture: Traditional WES relies on short-read sequencing (e.g., Illumina platforms), which can struggle with highly repetitive regions, pseudogenes, and structural variants. The integration of long-read sequencing technologies (such as PacBio HiFi reads and Oxford Nanopore platforms) with exome capture assays is emerging as a powerful tool to resolve complex genomic loci, providing complete structural variant detection across the exome.
B. AI-Driven Variant Interpretation: The bottleneck of WES is no longer data generation, but data analysis. Artificial Intelligence (AI) and machine learning algorithms are being integrated into bioinformatics pipelines to predict the pathogenicity of novel variants, automate clinical report generation, and translate raw sequence data into comprehensive biological narratives.
C. Multi-Omics Convergence: To create holistic biological profiles, researchers are increasingly combining WES with transcriptomics (RNA-Seq), proteomics, and metabolomics. This multi-layered approach allows scientists to correlate genetic variations (exome) with actual protein expression and metabolic phenotypes, creating richer datasets for multi-omics content creation.
🔬4. Deep Application Scenarios of WES
Whole Exome Sequencing acts as a foundational pillar across diverse scientific and clinical applications:
Rare Disease Diagnostics: WES excels in clinical settings for pediatric genetics. By sequencing the exome of the patient and their parents (Trio-WES), bioinformaticians can rapidly filter out benign variants and pinpoint *de novo* mutations responsible for developmental delays, congenital anomalies, and metabolic disorders.
Population Genetics & Biobanks: Large-scale population studies rely on WES to construct genetic variant databases specific to diverse ethnic cohorts. These databases serve as reference panels, improving the accuracy of variant interpretation globally and providing the raw material for epidemiological research publications.
Agricultural Genomics (Exome Capture): Although WES is predominantly associated with human medicine, exome capture technologies are increasingly applied in agriculture. For polyploid species with massive, complex genomes (such as wheat or cotton), sequencing the exome allows breeders to identify functional polymorphisms linked to agronomic traits, accelerating marker-assisted selection and crop improvement.
Biomarker Technologies (BMKGene)
Biomarker Technologies (BMKGene), founded in 2009, is a leading genomics service provider with over 16 years of continuous innovation in high-throughput sequencing and bioinformatics. Backed by more than 60 national invention patents and 200+ software copyrights, we deliver comprehensive multi-omics solutions—spanning genomics, metagenomics, epigenetics, single-cell omics, transcriptomics, and our proprietary BMKMANU S3000 spatial transcriptome technology—supported by our advanced BMKCloud bioinformatics platform. We have established long-term collaborations with organizations across 84 regions worldwide, providing reliable genomic solutions on a global scale.
Our Advanced Platforms & Facilities
Leveraging state-of-the-art sequencing platforms and massive computational power to deliver top-tier genomic datasets.

Leading Platforms
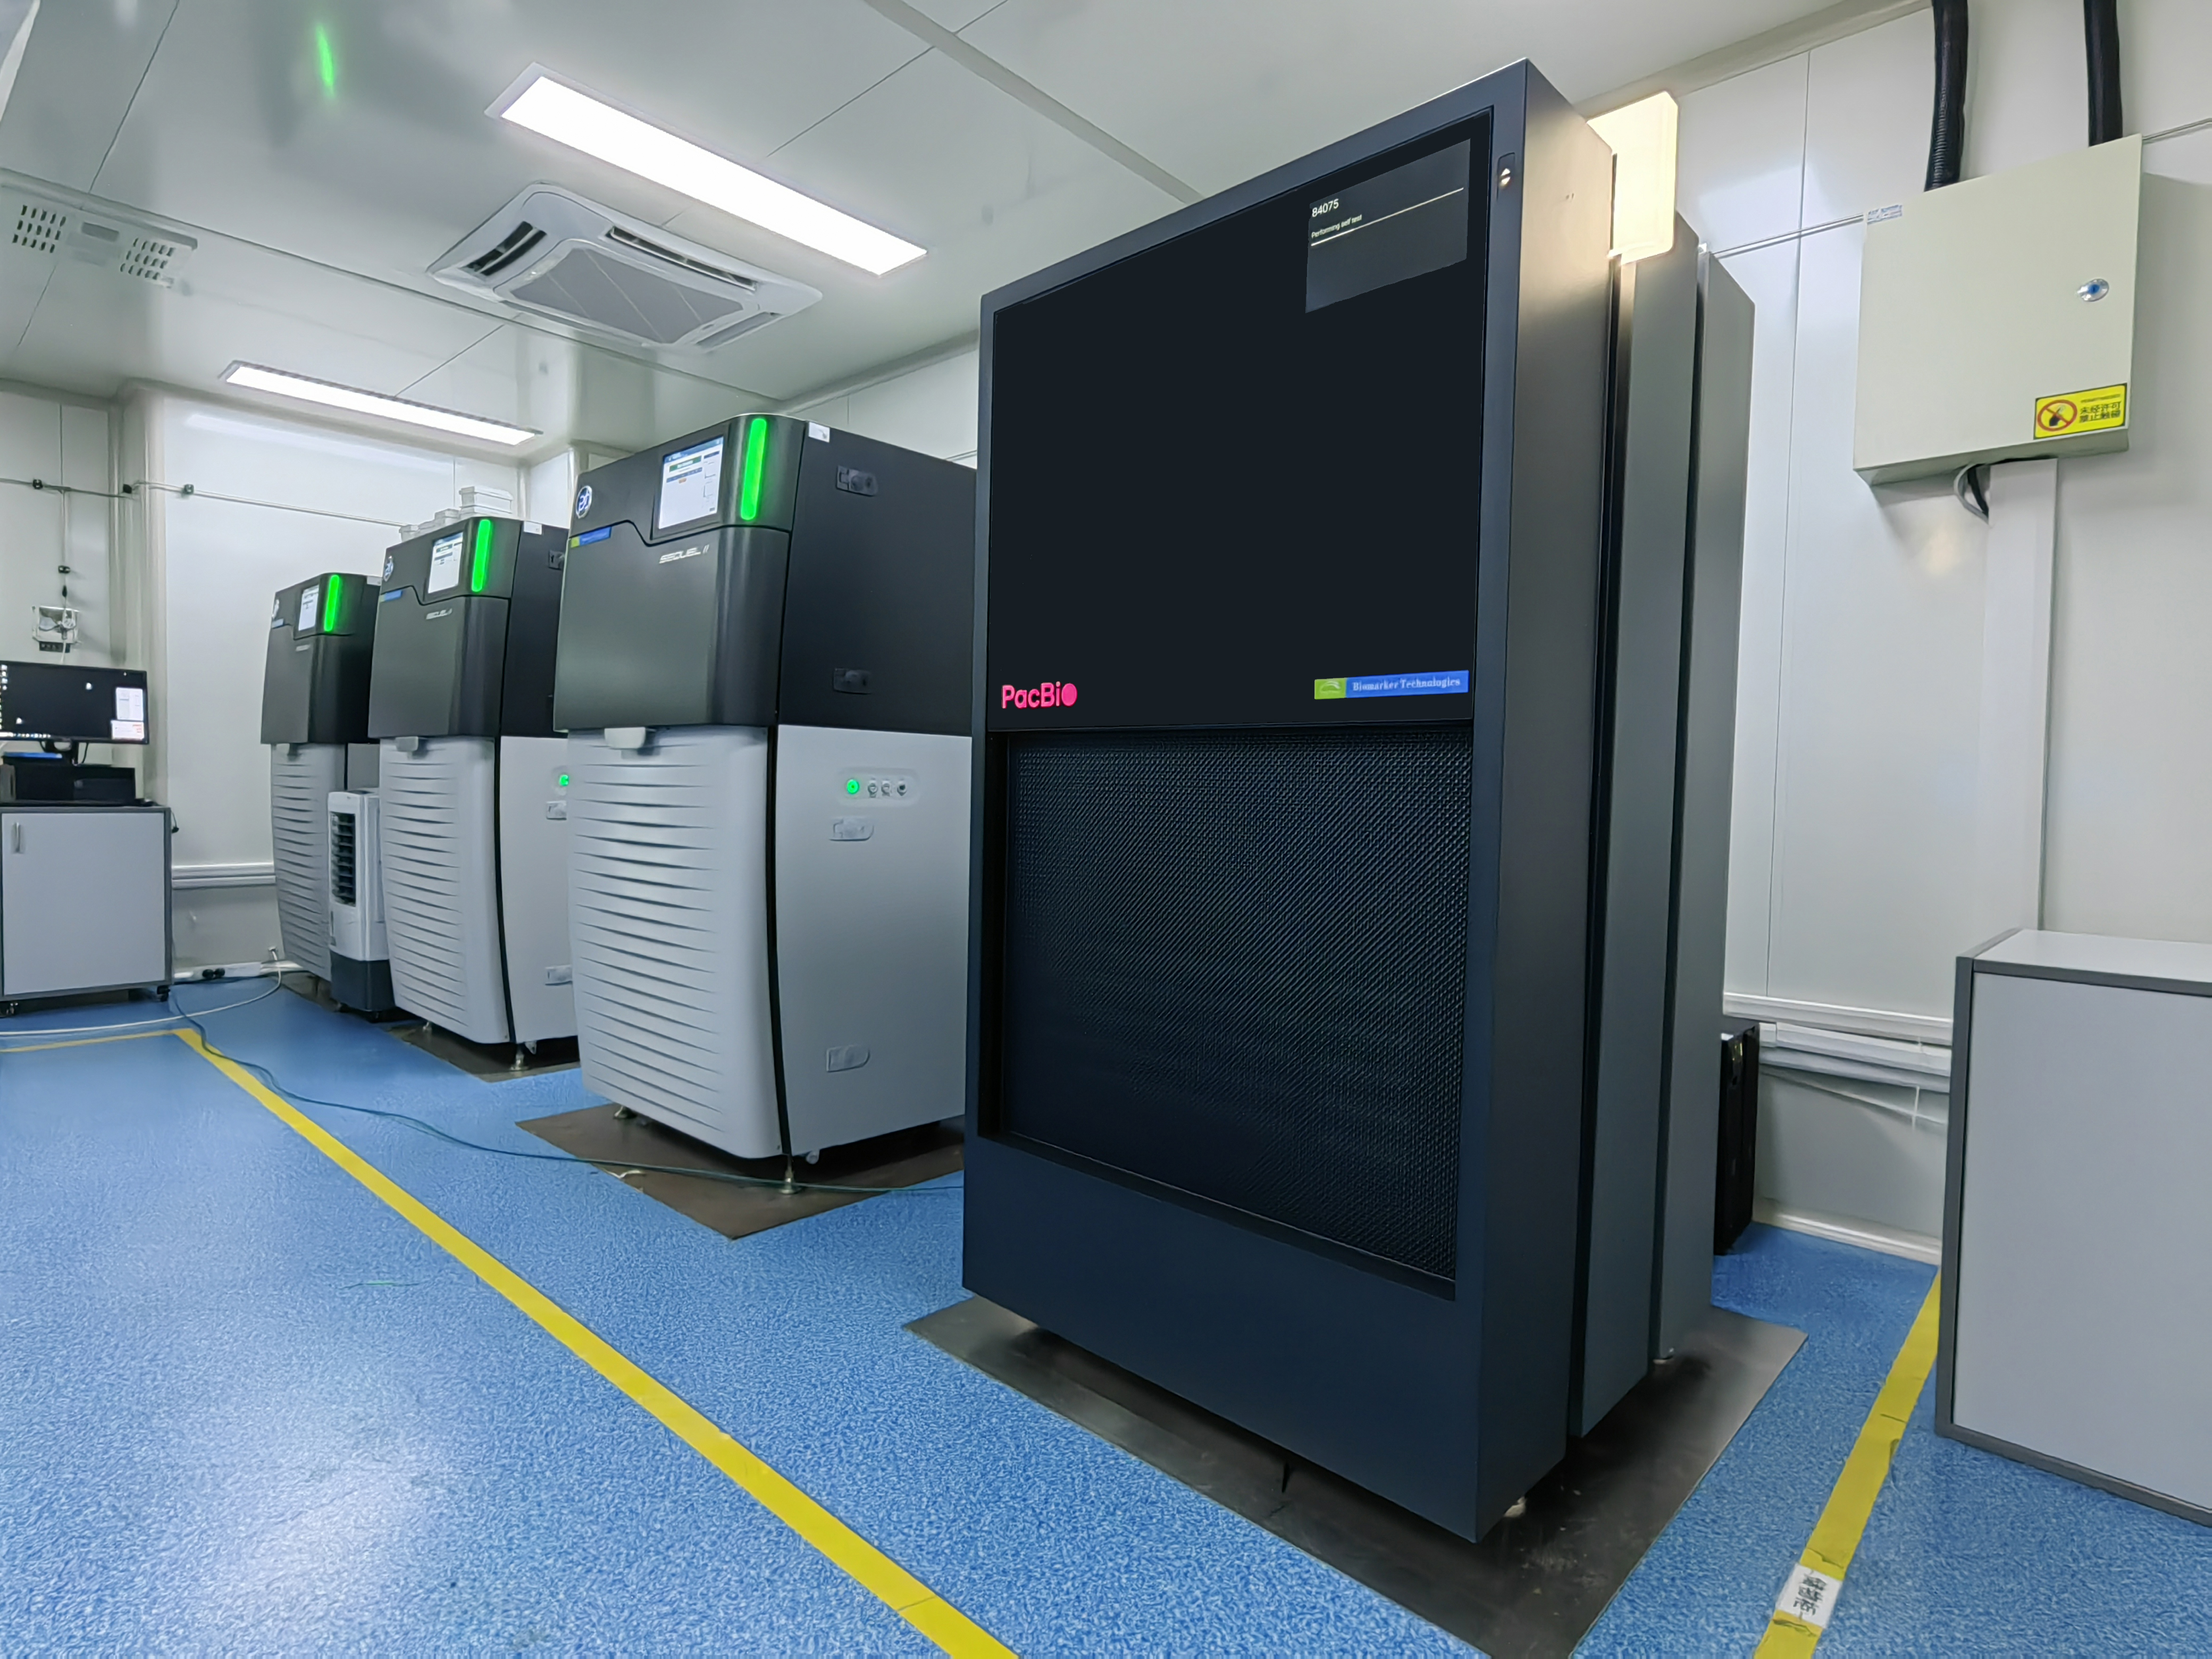
PacBio platforms: Sequel II, Sequel, RSII
Nanopore platforms: PromethION P48, GridION X5 MinION
10X Genomics: 10X ChromiumX, 10X Chromium Controller
Illumina platforms: NovaSeq
BGI platforms: DNBSEQ-G400, DNBSEQ-T7
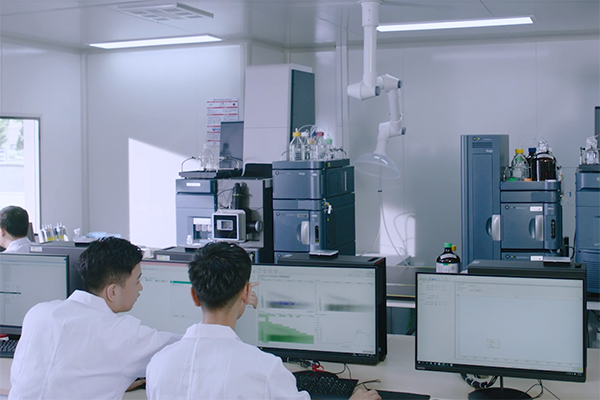
Other Instruments: Bionano Irys system, Waters XEVO G2-XS QTOF, QTRAP 6500+

World-Class Facility
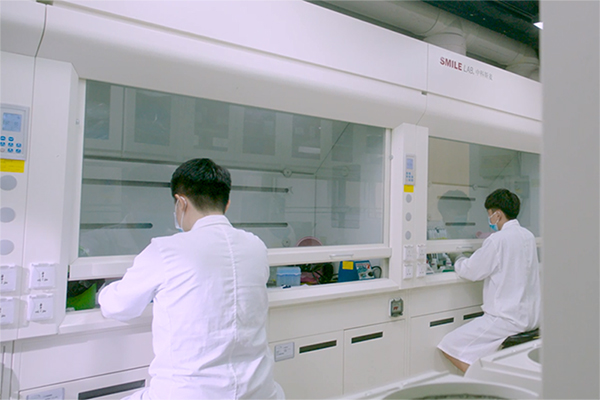
Over 20,000 square feet place: Housing advanced biomolecular laboratory instruments.
Standardized laboratories designed for sample extraction, NGS library construction, clean rooms, and sequencing operations.
Strict Standard Operating Procedures (SOPs) enforced from sample arrival to final data delivery to guarantee maximum reliability.

BMKCloud Platform
An ease-to-use online bioinformatic analysis platform developed entirely in-house.
Compute Power: 4,260 computing cores with peak computing power exceeding 121,708.8 Gflop per second.
Memory & Storage: CPUs with 41,104 memory and 3 PB total high-performance storage capacity.
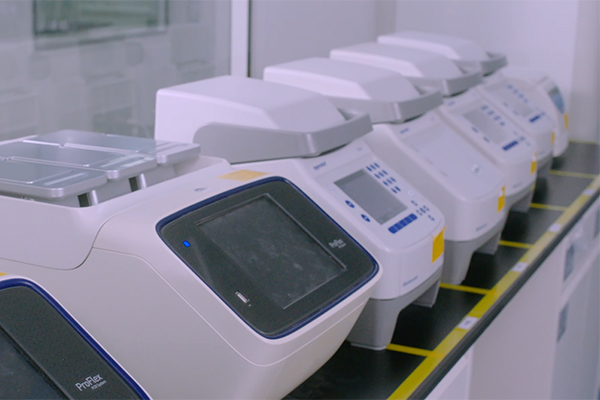
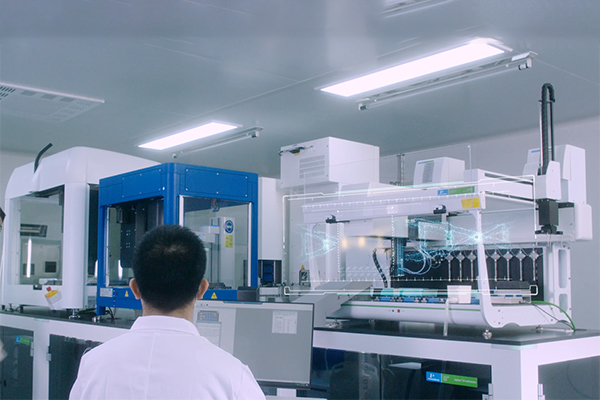
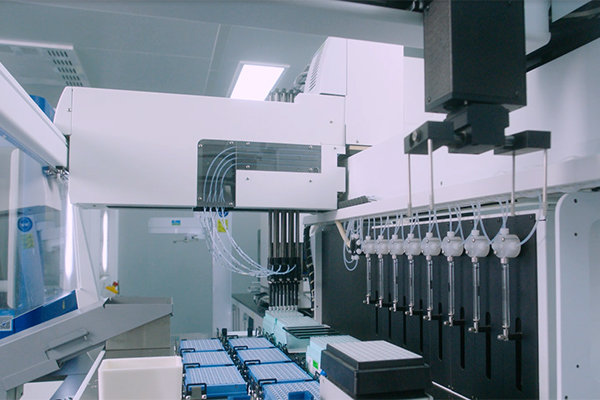
Fully Automated NGS Library Construction: Brilliant Lab 1000
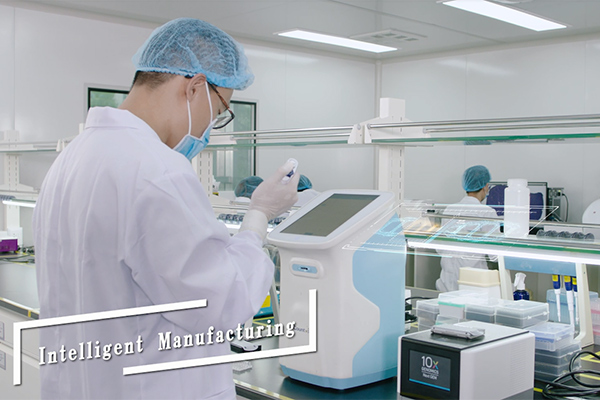
Biomarker Technologies (BMKGENE) and PerkinElmer have jointly built a fully automated experimental production line, called Brilliant Lab 1000 (BL1000), which is applied to high-throughput NGS library construction services.
By automating the library preparation process, BMKGENE significantly minimizes human error, improves consistency, and drastically reduces turnaround times. This system enables us to scale our sequencing operations to meet the demands of large-scale clinical trials and genome sequencing projects, delivering unmatched quality and efficiency.
Enterprise Qualifications & Patents
Demonstrating our commitment to quality, innovation, and scientific excellence through global certifications and proprietary technologies.


Our Complete Product Portfolio
Explore our full selection of sequencing and multi-omics services designed to accelerate your scientific research.


